Semantic Enhancement Guide
Overview
Besides a label and a description, each component can hold RDF statements that bind it to concepts in published ontologies, and those statements are written into the published schema. This guide covers ontologies you upload, the links the AI adds during processing, and the links you add by hand.
Ontologies
An uploaded ontology is an RDF file whose concepts the automatic linking step can find. Uploading one also registers its namespace, so the abbreviation can be used as a prefix and the ontology can be picked as a preferred ontology in Settings.
Uploading an ontology
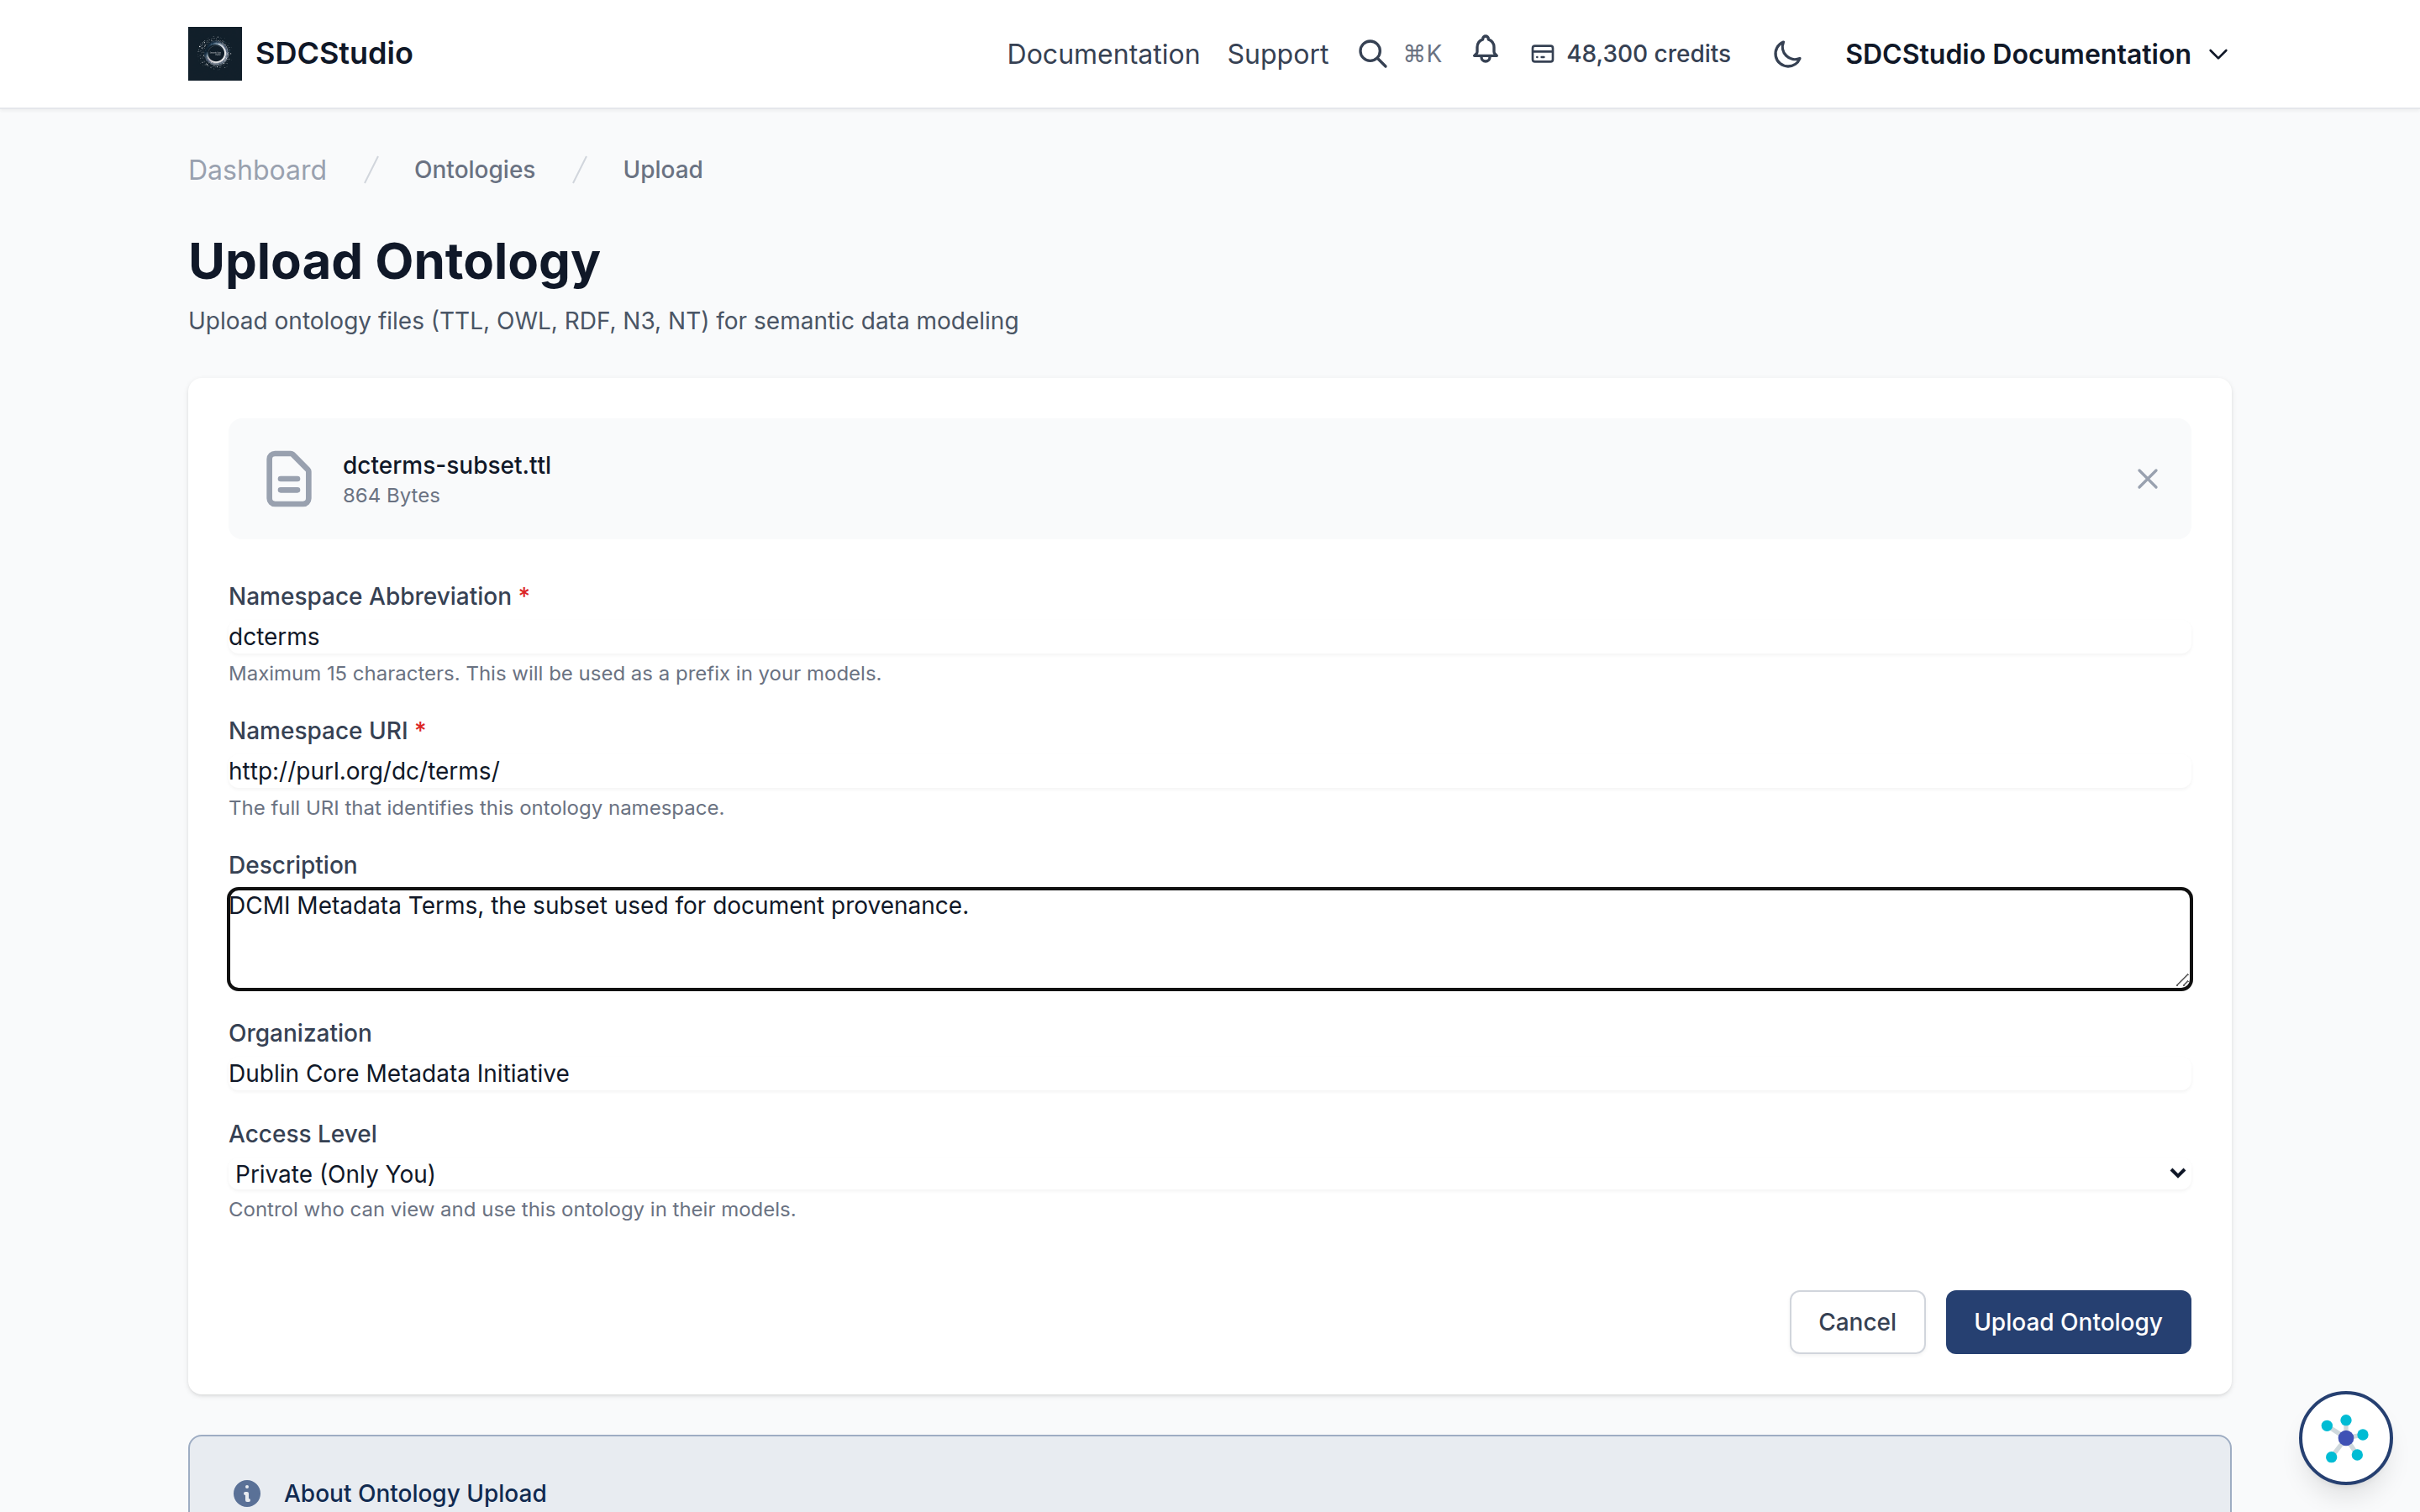
Open Ontologies at /app/ontologies (there is also a Manage Ontologies link next to Preferred Ontologies in Settings) and click Upload Ontology.
- File: TTL, OWL, RDF, N3 or NT, up to 10 MB.
- Namespace Abbreviation (required): up to 15 characters, used as a prefix in your models, for example
foaforschema. - Namespace URI (required): the full namespace, for example
http://xmlns.com/foaf/0.1/. - Description and Organization (optional).
- Access Level: Private (Only You), Team (Your Team), Corporate (Your Organization) or Public (All Users). The default is Private. Team and Corporate both mean the same thing today: the ontology is listed for every user who shares a project team with you.
Click Upload Ontology. The file is stored and loaded into the triplestore in the same request, and the page moves to the ontology's detail page.
The abbreviation and the URI must each be unique across all uploaded ontologies on the server. If either one is already taken, the form shows the server's message under that field (and "Please correct the fields marked below." above the form): choose another abbreviation, or check the URI, and upload again.
Statuses
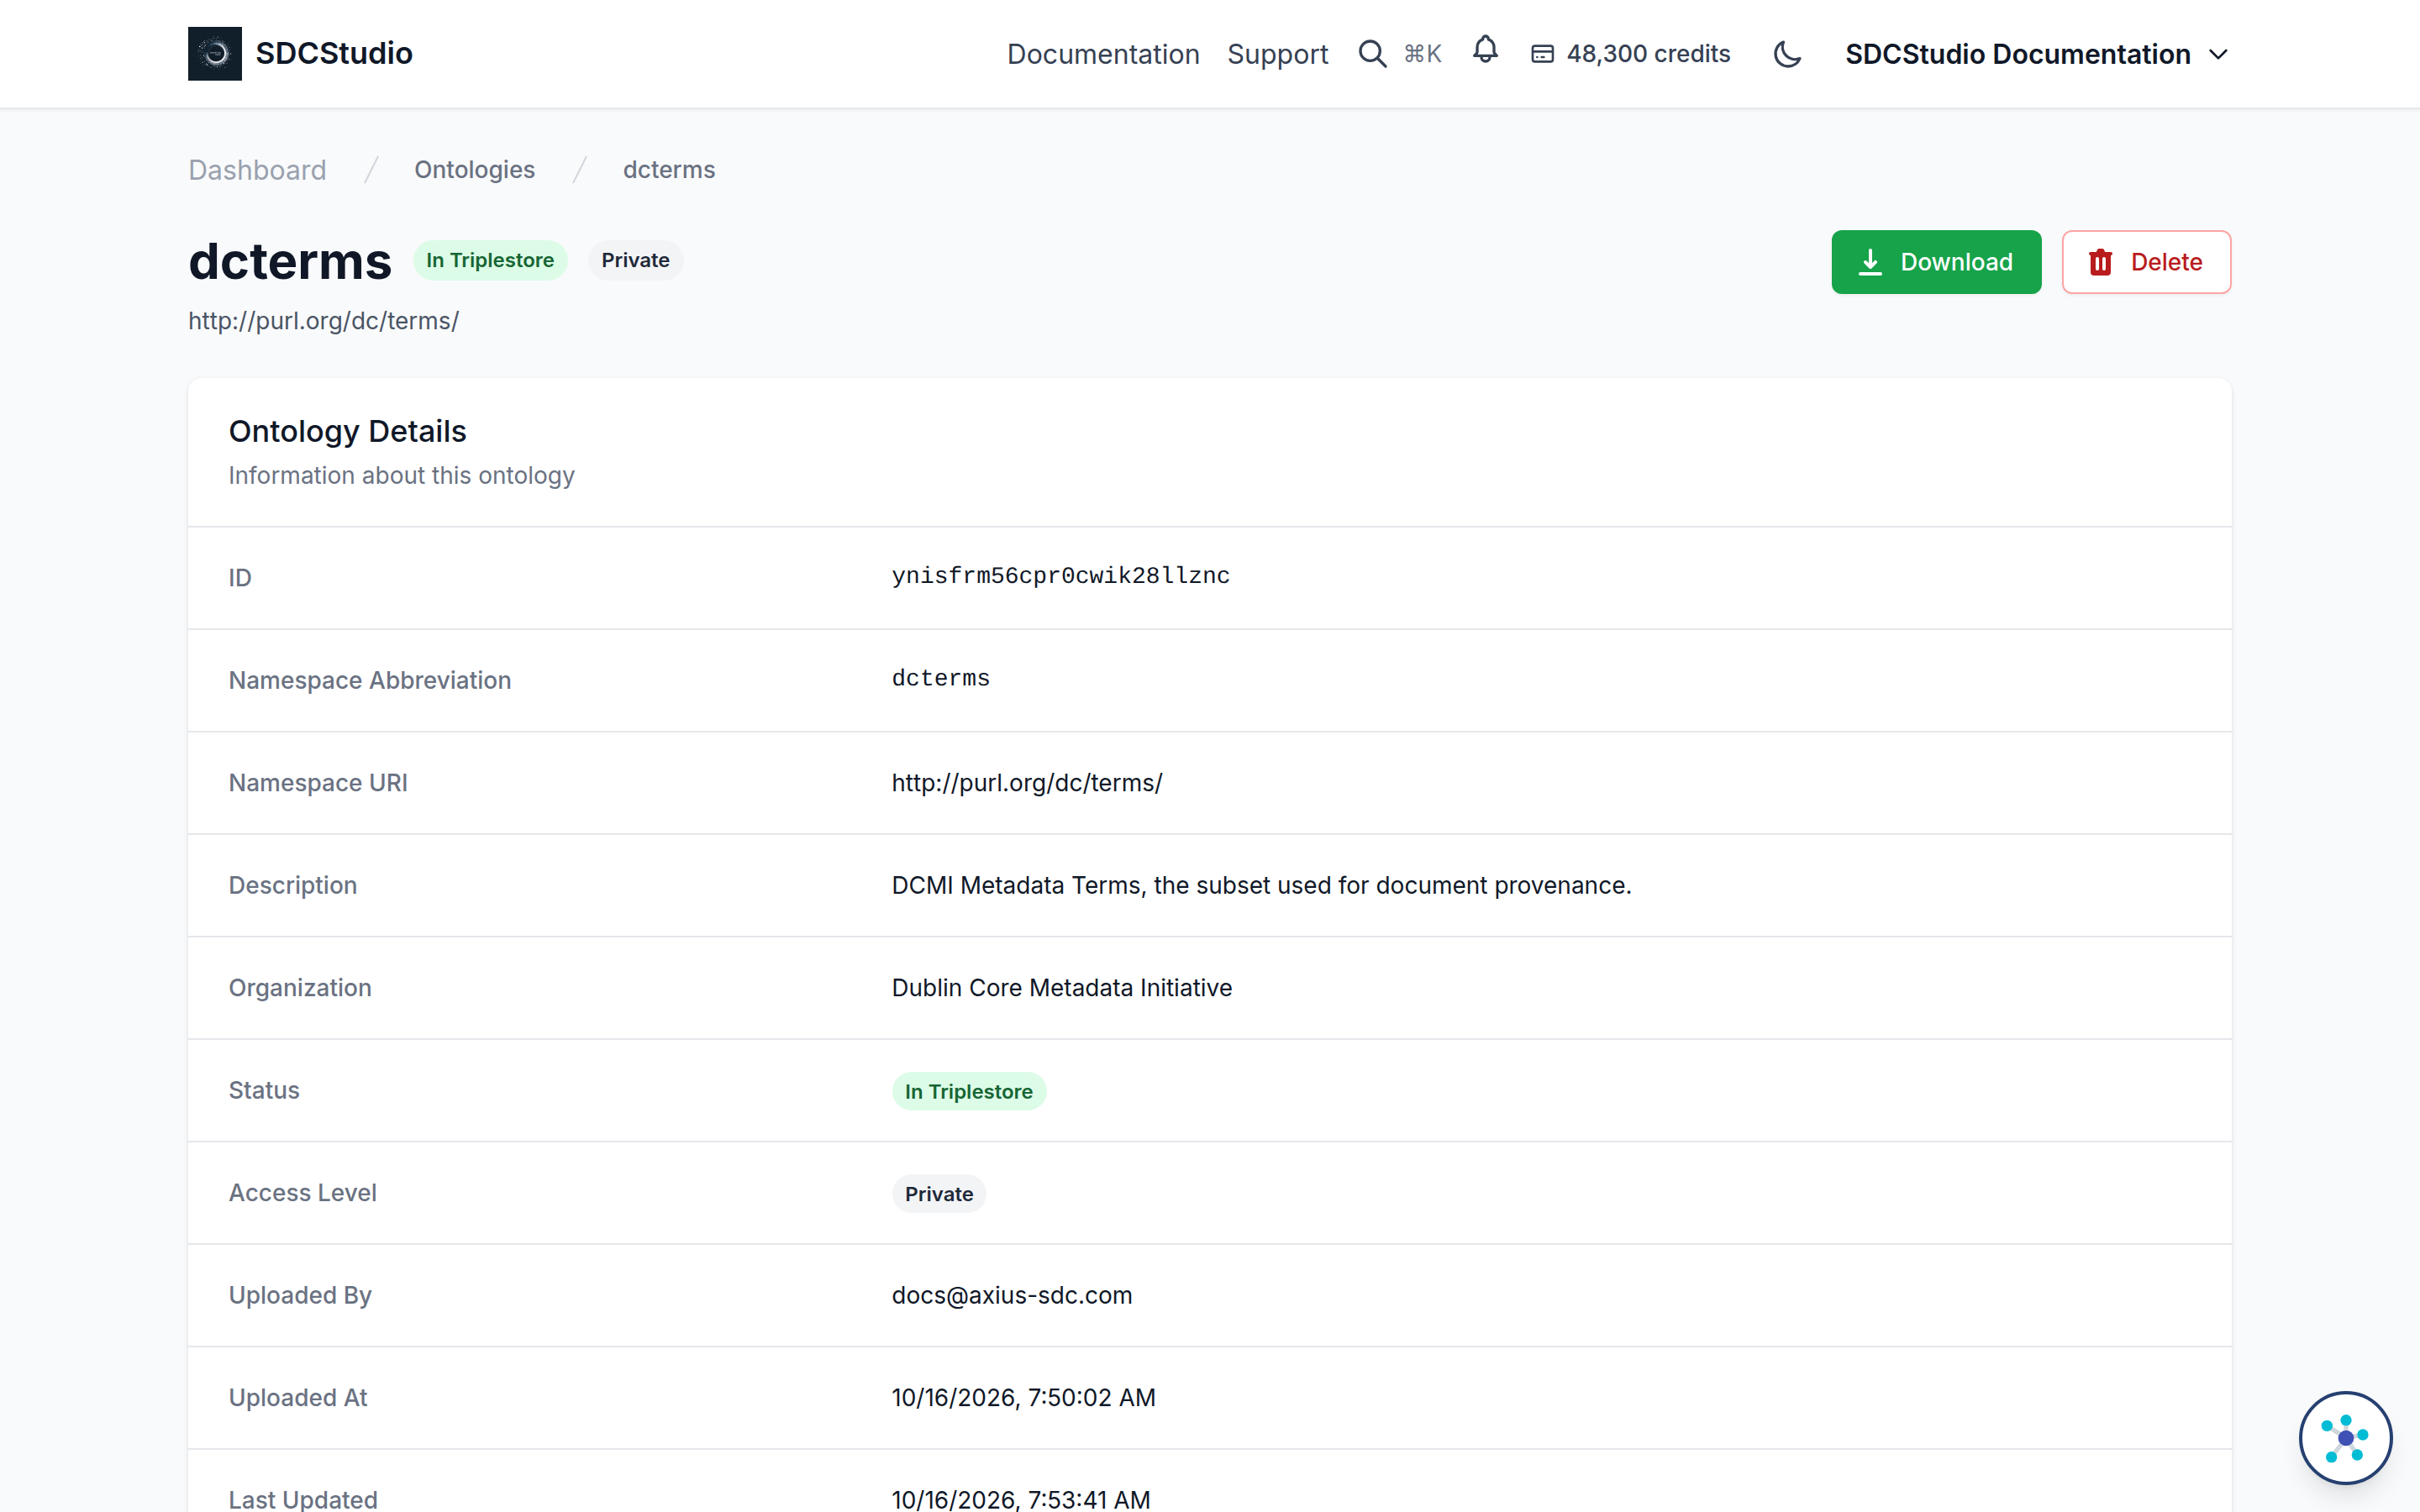
Each ontology shows one of three statuses, on the list and on its detail page:
- In Triplestore: loaded and available to the automatic linking step.
- Filesystem Only: the file is stored but the load into the triplestore failed. The error text is shown under the entry and on the detail page.
- Error: the upload record could not be processed at all.
For anything not In Triplestore, the uploader (or a staff user) sees a Reprocess button on the list and on the detail page. It retries the load from the stored file and updates the status. A failed load is usually a syntax error in the file or a format that does not match the extension (.owl and .rdf are sent as RDF/XML, everything else as Turtle).
Managing ontologies
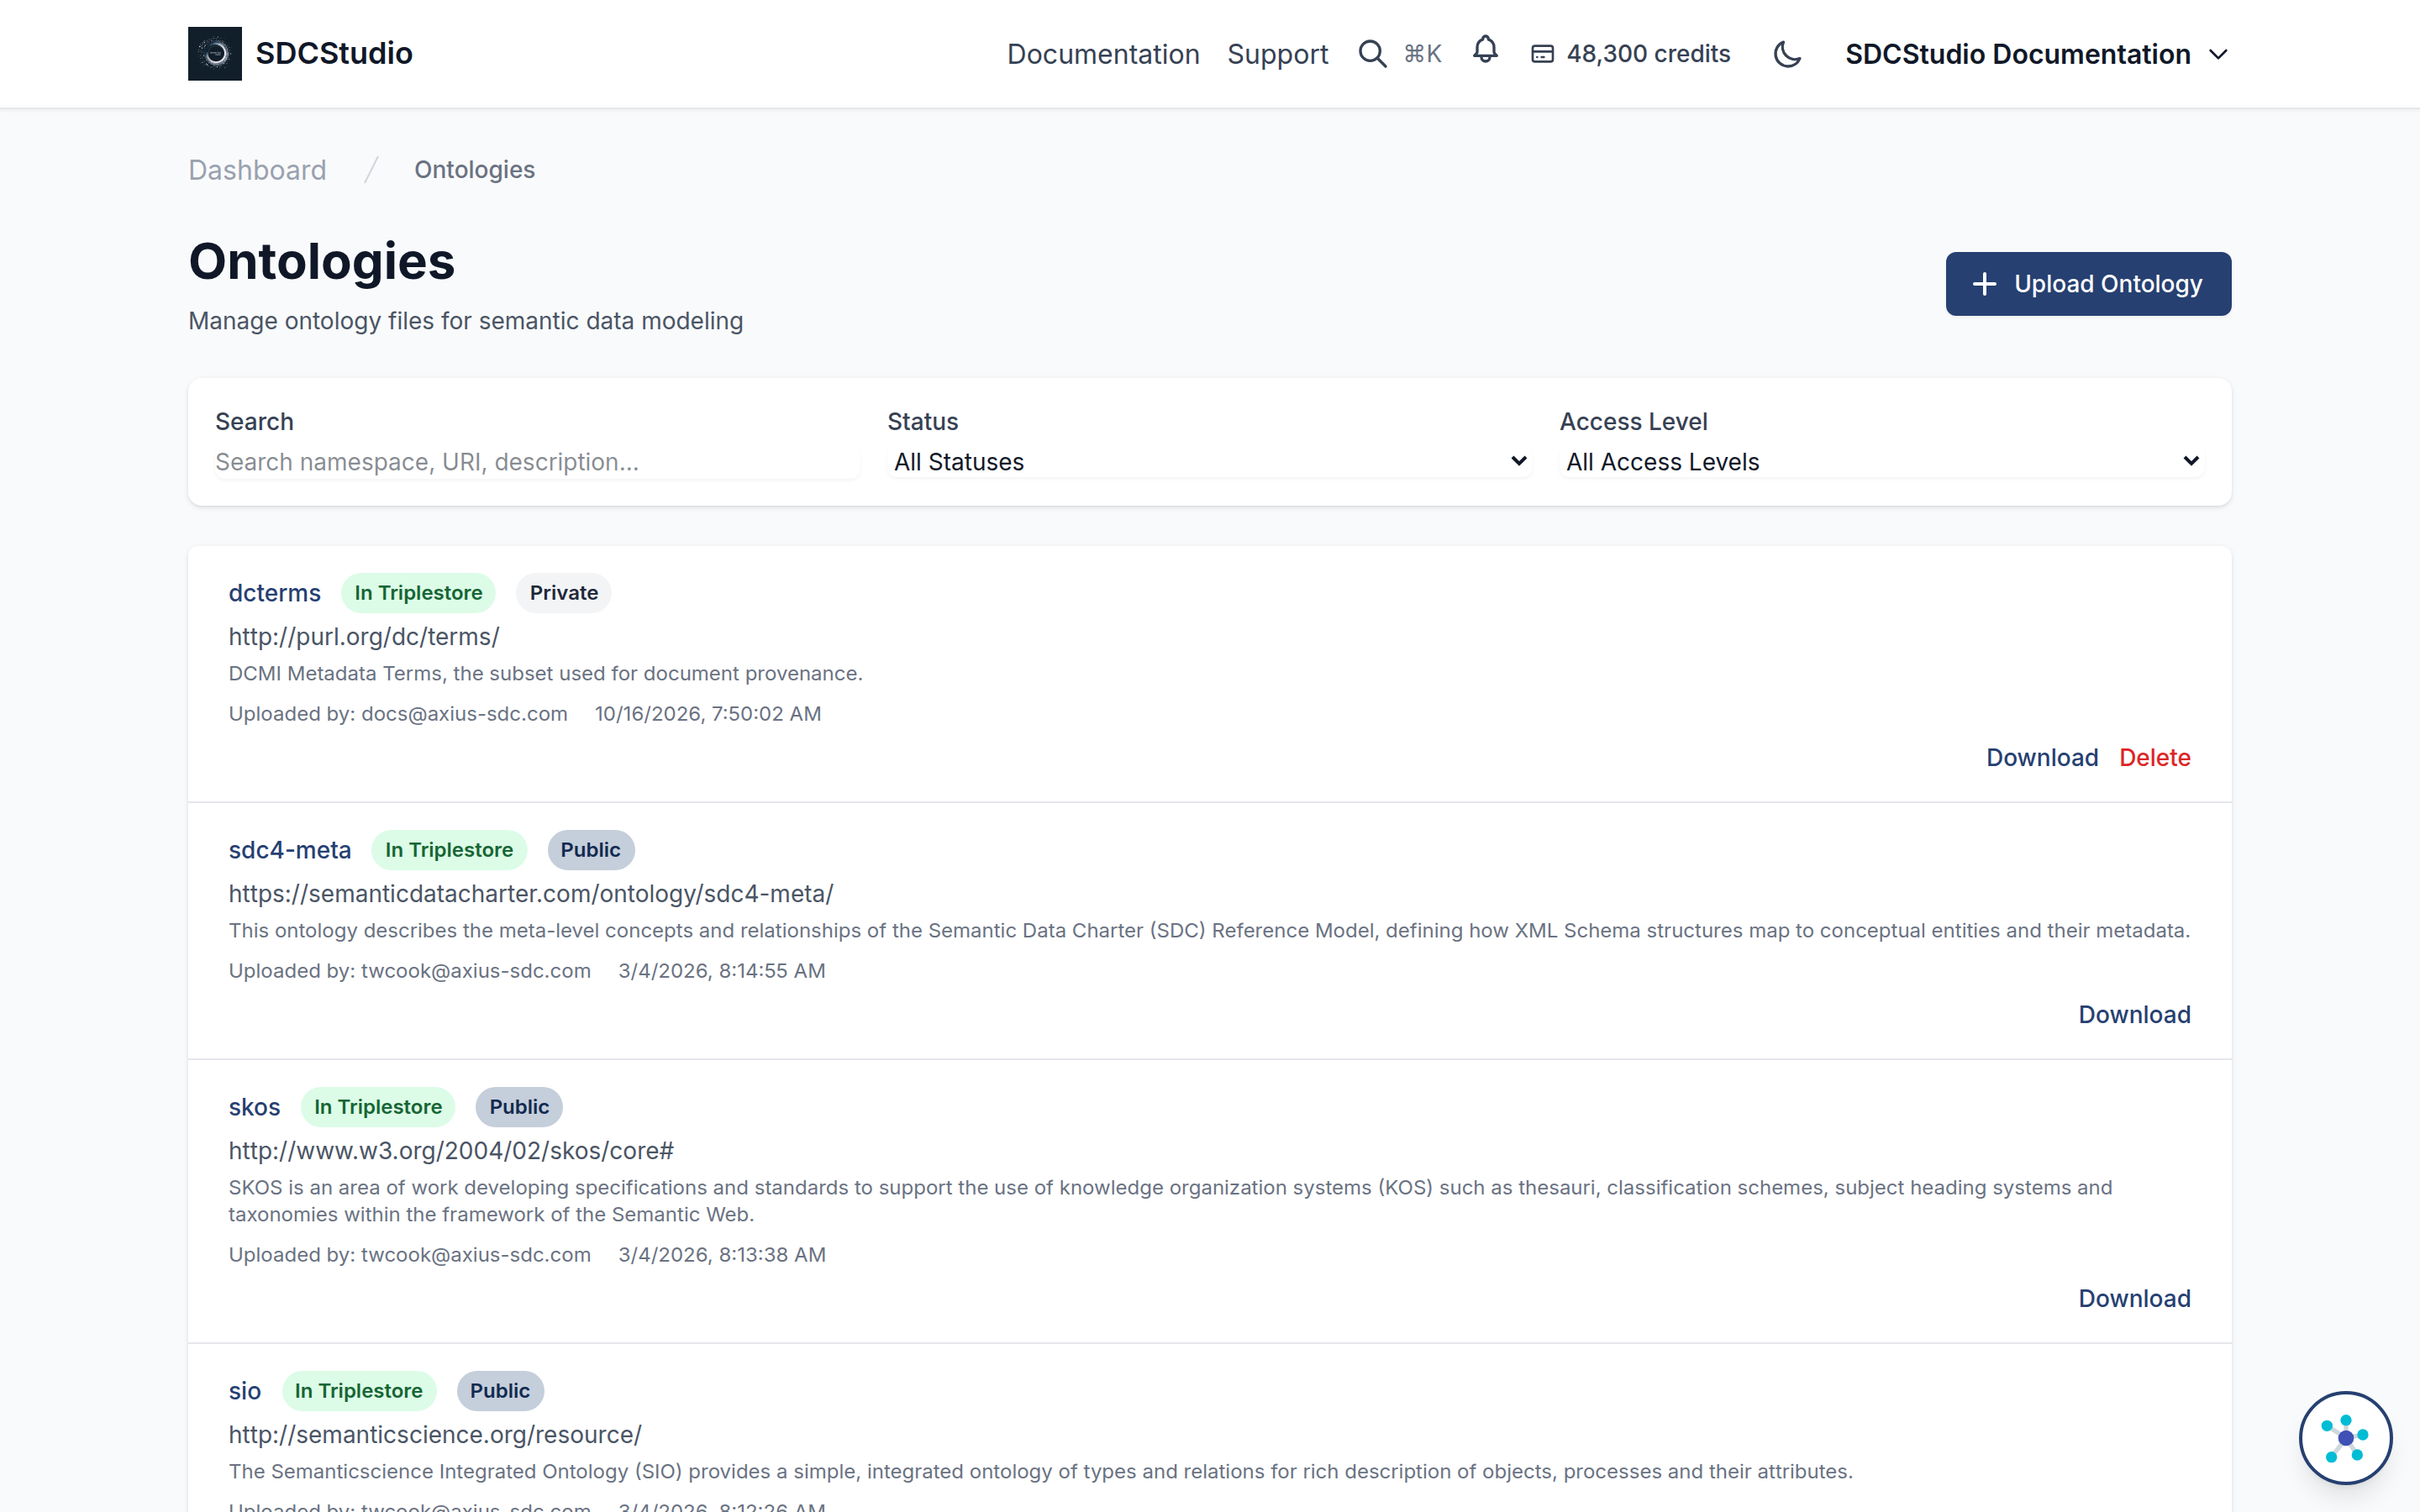
The list shows your own uploads, every Public ontology, and the Team and Corporate ones uploaded by people who share a project team with you; staff see all. It can be searched by abbreviation, URI, description or organization and filtered by status (In Triplestore, Filesystem Only, Error) or access level. Each entry has Download (the original file), Reprocess (when not in the triplestore) and Delete (uploader or staff only).
Preferred ontologies
In Settings on the Preferences tab, the Modeler Information section has:
- Preferred Ontologies: every registered namespace, standard or uploaded, is on the Available side; move the ones that matter for your domain to Selected and click Save Modeler Settings.
- Ontology Weight Multipliers: Preferred, Standard and External weights (0.1 to 5.0), used when the automatic linking step scores candidate concepts.
- Preferred Ontology Service: an optional URL stored with your profile.
Your non-standard preferred ontologies are listed on the Upload page, with an Edit in Settings link, and go into the analysis prompts as a general domain hint for every CSV you upload. During linking, their namespaces are added to the triplestore query and their abbreviations are passed to the AI as the ontologies to prefer.
Automatic linking during AI processing
When an upload is processed (see AI Processing), each new component goes through three linking steps after it is created:
- Type-level statements. Every component type gets a fixed
rdf:typefrom schema.org:schema:Textfor a string,schema:Boolean,schema:Integerfor a count,schema:Numberfor a quantity, float or double,schema:DateTimefor a temporal,schema:URLfor a link. A token also getsrdf:type skos:ConceptSchemeandskos:exactMatch schema:DefinedTermSet. Files, ordinals, units and clusters get no type-level statement. - Reference documents. If the label, description or dataset domain contains certain keywords, an
rdfs:seeAlsolink is added to the matching authority, for example HL7 FHIR, WHO ICD-11, the WHO ATC classification or the W3C Data Privacy Vocabulary. - Concept match. Keywords from the column name and description are searched against the labels and comments of everything loaded in the triplestore (up to three results), and the AI proposes up to five candidate IRIs from standard ontologies; each AI candidate is fetched over HTTP, with a ten second timeout, and dropped if it does not resolve. The candidates are scored, with preferred ontologies weighted as set in Settings, and filtered; the first candidate that remains becomes a single RDF Object on the component, so review it before you publish. The predicate follows the relationship the engine classified:
skos:closeMatchby default, orskos:exactMatch,skos:relatedMatch,skos:broadMatch,skos:narrowMatch,owl:equivalentClass,rdfs:seeAlsoorrdfs:isDefinedBy.
If no acceptable match is found, the component is still created without a concept link. Every generated link can be reviewed and changed on the component before you publish.
Manual linking
RDF Objects
A semantic link is an RDF Object: a named pair of a predicate (a prefix plus a term, such as skos:closeMatch) and an object URI. RDF Objects belong to a project; one marked Is Public? can be selected by every other modeler, otherwise it is visible only inside its project. A component can carry any number of them.
In the Component Wizard and the edit form
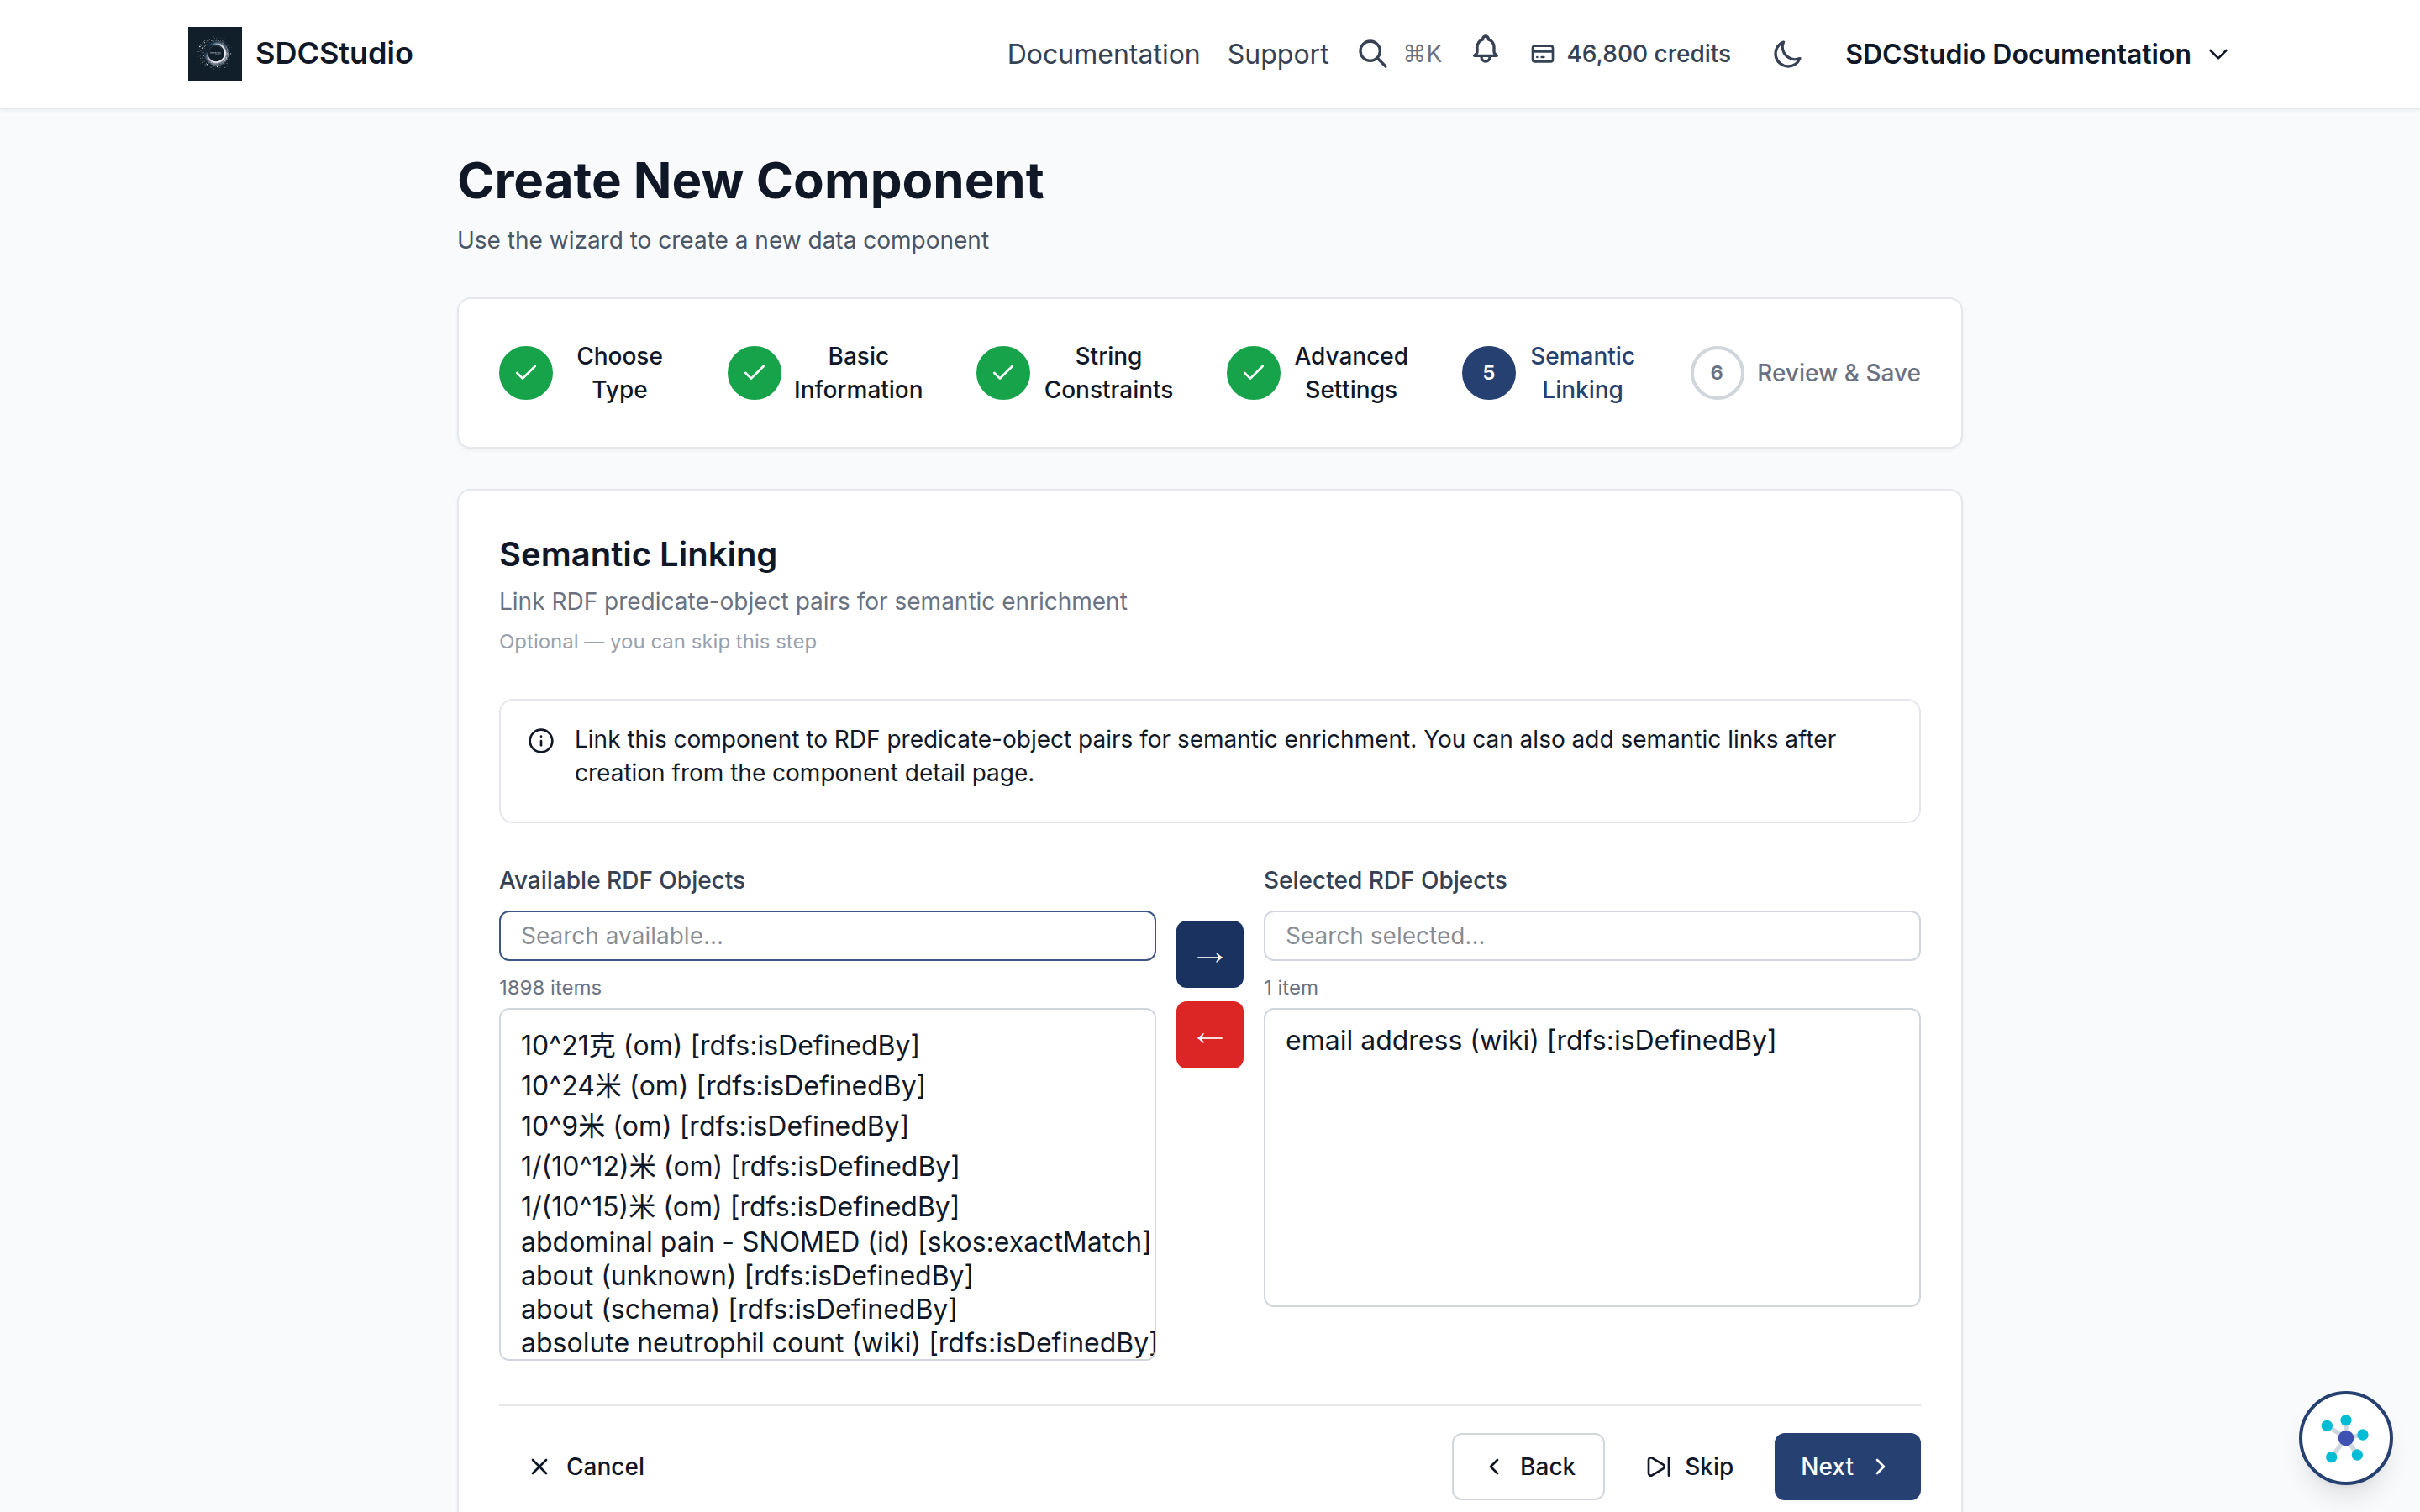
The wizard's Semantic Linking step, and the Semantic Linking section of the edit form, show two lists (the Cluster Wizard has no semantic step; a cluster's links are added in its edit form): Available RDF Objects and Selected RDF Objects. Type in the search box above either list to filter it, then use Add selected, Add all, Remove selected or Remove all.
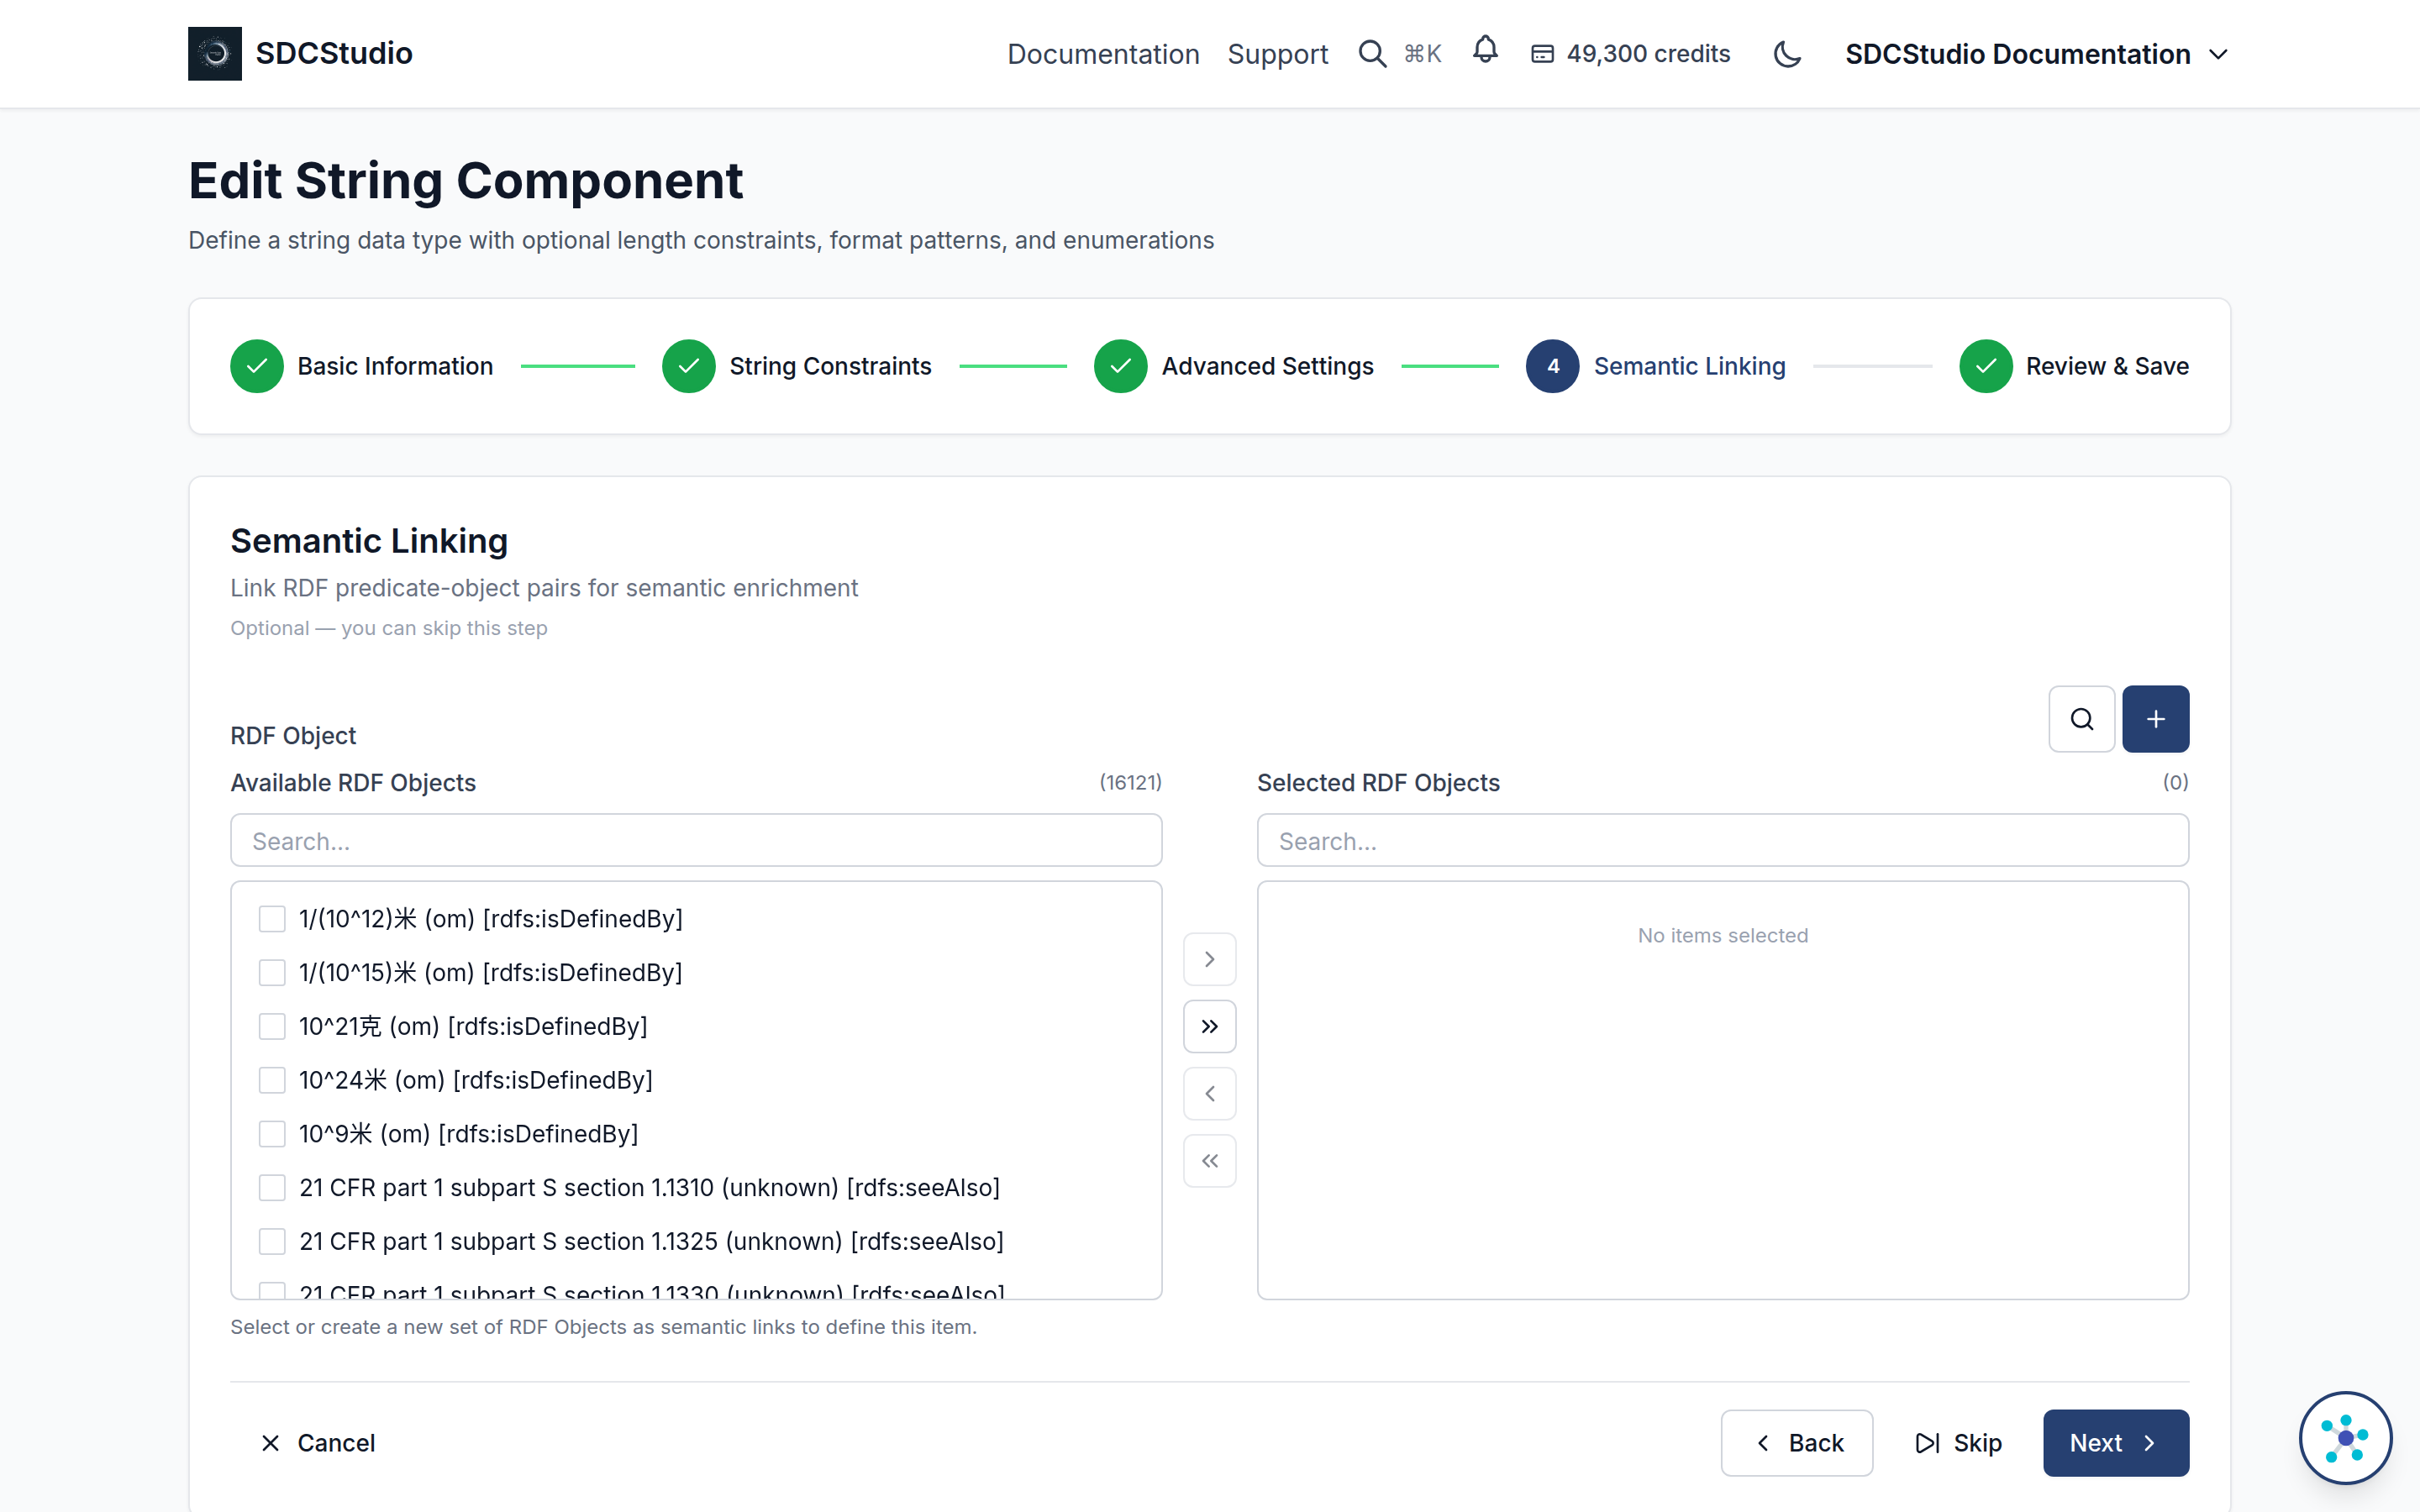
Next to the RDF Object label are two icon buttons. Search Google for controlled vocabularies opens a web search in a new tab built from the project name and the component's label and description. Create new RDF Object opens the dialog below; it needs a project selected first.
The Create New RDF Object dialog
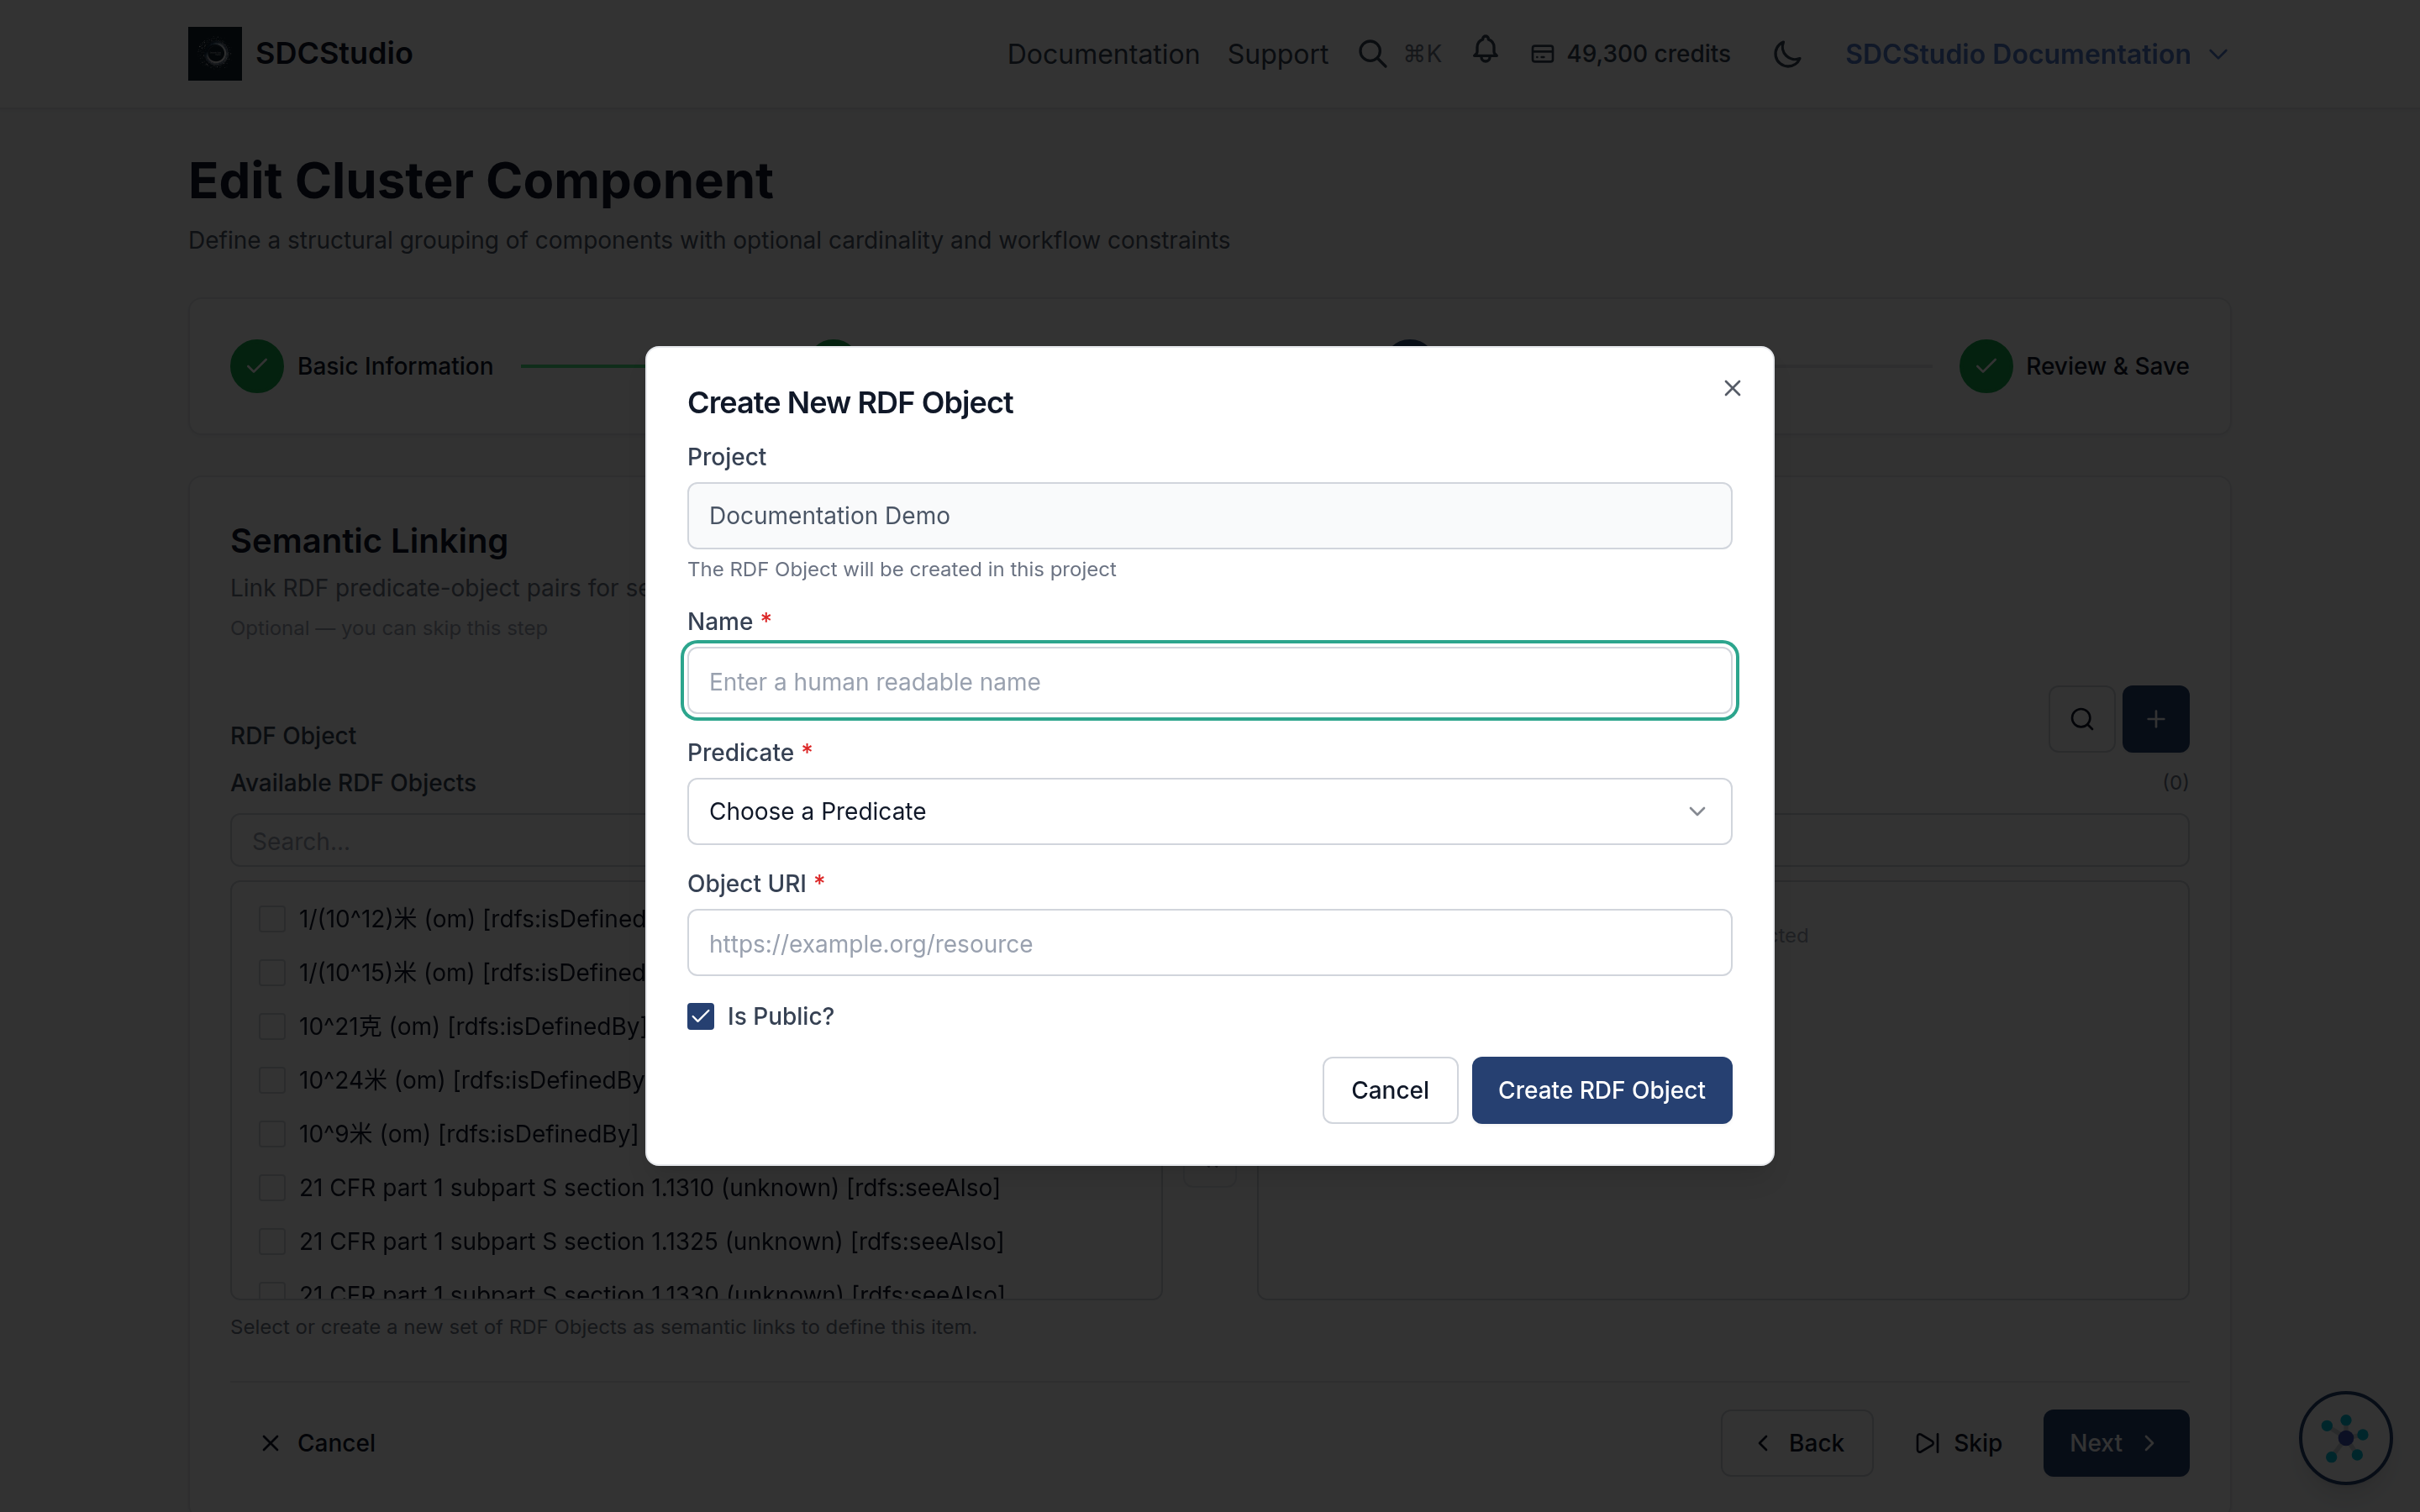
- Project: fixed to the component's project.
- Name: a human-readable name, only used to pick the object from a list; it is not part of the component's semantics.
- Predicate: choose from the registered predicates.
- Object URI: the IRI of the concept, for example
https://schema.org/email. - Is Public?: make the object available to every other modeler.
Click Create RDF Object. The new object is added to the Selected list at once.
What gets published
When a component is published, its XSD gains an xsd:appinfo block holding an rdf:Description about the component: its type in the Semantic Data Charter reference model, its rdfs:label and rdfs:comment, and one element per RDF Object, for example <skos:closeMatch rdf:resource="https://schema.org/email"/>. The RDF artifact of a generated model package is extracted from these appinfo blocks, so every Governed Data Record validated by the schema resolves to the same concepts.
Suggestion endpoints
A set of suggestion endpoints under /api/v1/rag/ exists for API users; the web application does not use them.
Next steps
- AI Processing Guide: what happens to an upload.
- Generating Outputs: the artifacts a published model produces.
- Troubleshooting: ontology upload and processing errors.
- Questions: contact@axius-sdc.com