Your First Data Model
Overview
This guide walks you through creating your first data model in SDCStudio using the web interface. You'll learn the complete workflow from configuring Settings and uploading ontologies to generating the output package from a published model.
Time to Complete: 15-20 minutes
What You'll Learn
- How to configure Settings and upload ontologies
- How to navigate the web interface
- How to upload and process data files
- How the agents analyze and enhance your data with ontologies
- How to review and customize model components
- How to publish and generate the output package
Prerequisites
- An active SDCStudio account at https://sdcstudio.axius-sdc.com with a funded wallet. A new account is taken to
/app/welcomeand must fund its wallet before anything else in the app opens: click Fund $10 & Start and pay $10 (10,000 credits) through Stripe; larger packs are sold afterwards in Settings > Wallet. The credits are yours and are spent per operation; nothing is charged by time. The gate applies to accounts created on or after 1 August 2026 and releases for good the first time the wallet holds a positive balance. Until then the rest of the app is not reachable; the public catalog API and the practitioner directory need no account. - A sample CSV file (or use our example below)
- (Optional but recommended) Project or domain specific ontologies (.ttl, .owl, .rdf, .n3, or .nt)
Step 0: Configure Settings First (Critical)
Before creating your first model, configure your Settings. This is the most important step for getting high-quality semantic suggestions.
Access Settings
- Sign In to SDCStudio
- Open the user menu (top right) and click Settings, or go to
/app/settings - You'll see a page with six tabs: Profile, Preferences, Teams Management, Wallet, Practitioner, API Keys
Upload Your Ontologies
Why This Matters: - The agents use your preferred ontologies to understand your domain - Better semantic suggestions and component creation - Consistency with your organization's data vocabulary - Improved validation and relationship detection
Important Note:
- Ontologies live on their own page, /app/ontologies; Settings only chooses which uploaded ontologies are preferred
- Upload the vocabularies your project uses: your organization's data dictionary, project-specific terminology, or a public ontology your domain relies on
- Ontologies uploaded with a Team, Corporate, or Public access level are visible to others
Upload Process:
- Open the Ontologies page: Settings > Preferences > Modeler Information > Manage Ontologies, or go to
/app/ontologies - Click "Upload Ontology"
- Choose your file (.ttl, .owl, .rdf, .n3, or .nt, up to 10 MB):
- Your organization's custom vocabulary
- Project-specific data dictionary
- Industry-specific terminology
- Fill in the form:
- Namespace abbreviation: the prefix used in your models, at most 15 characters (for example,
acme) - Namespace URI: the ontology's namespace
- Description: "Custom vocabulary for our product classification"
- Organization: who publishes it
- Access Level: Private, Team, Corporate, or Public
- Click "Upload Ontology"
- Repeat for multiple ontologies
- Back in Settings > Preferences, move each ontology into Selected Ontologies under Preferred Ontologies and click Save Modeler Settings
What to Upload: - - Your organization's data dictionary - - Custom business vocabularies specific to your domain - - Project-specific terminology - - Public ontologies your domain relies on, if nobody on your team has uploaded them yet
Configure Your Profile
- Click the "Profile" tab
- Update:
- Full Name, First Name, Last Name
- Organization
- Intended Usage (optional)
- Click "Save Changes"
Now you're ready. Your preferred ontologies will inform all agent processing.
Step 1: Create Your First Project
Projects organize all your related work in one place. Your account already has one project, created with it: named after you, private, and set as your default. You can build in it, rename it on its page, or create another to keep this work separate.
Navigate and Create
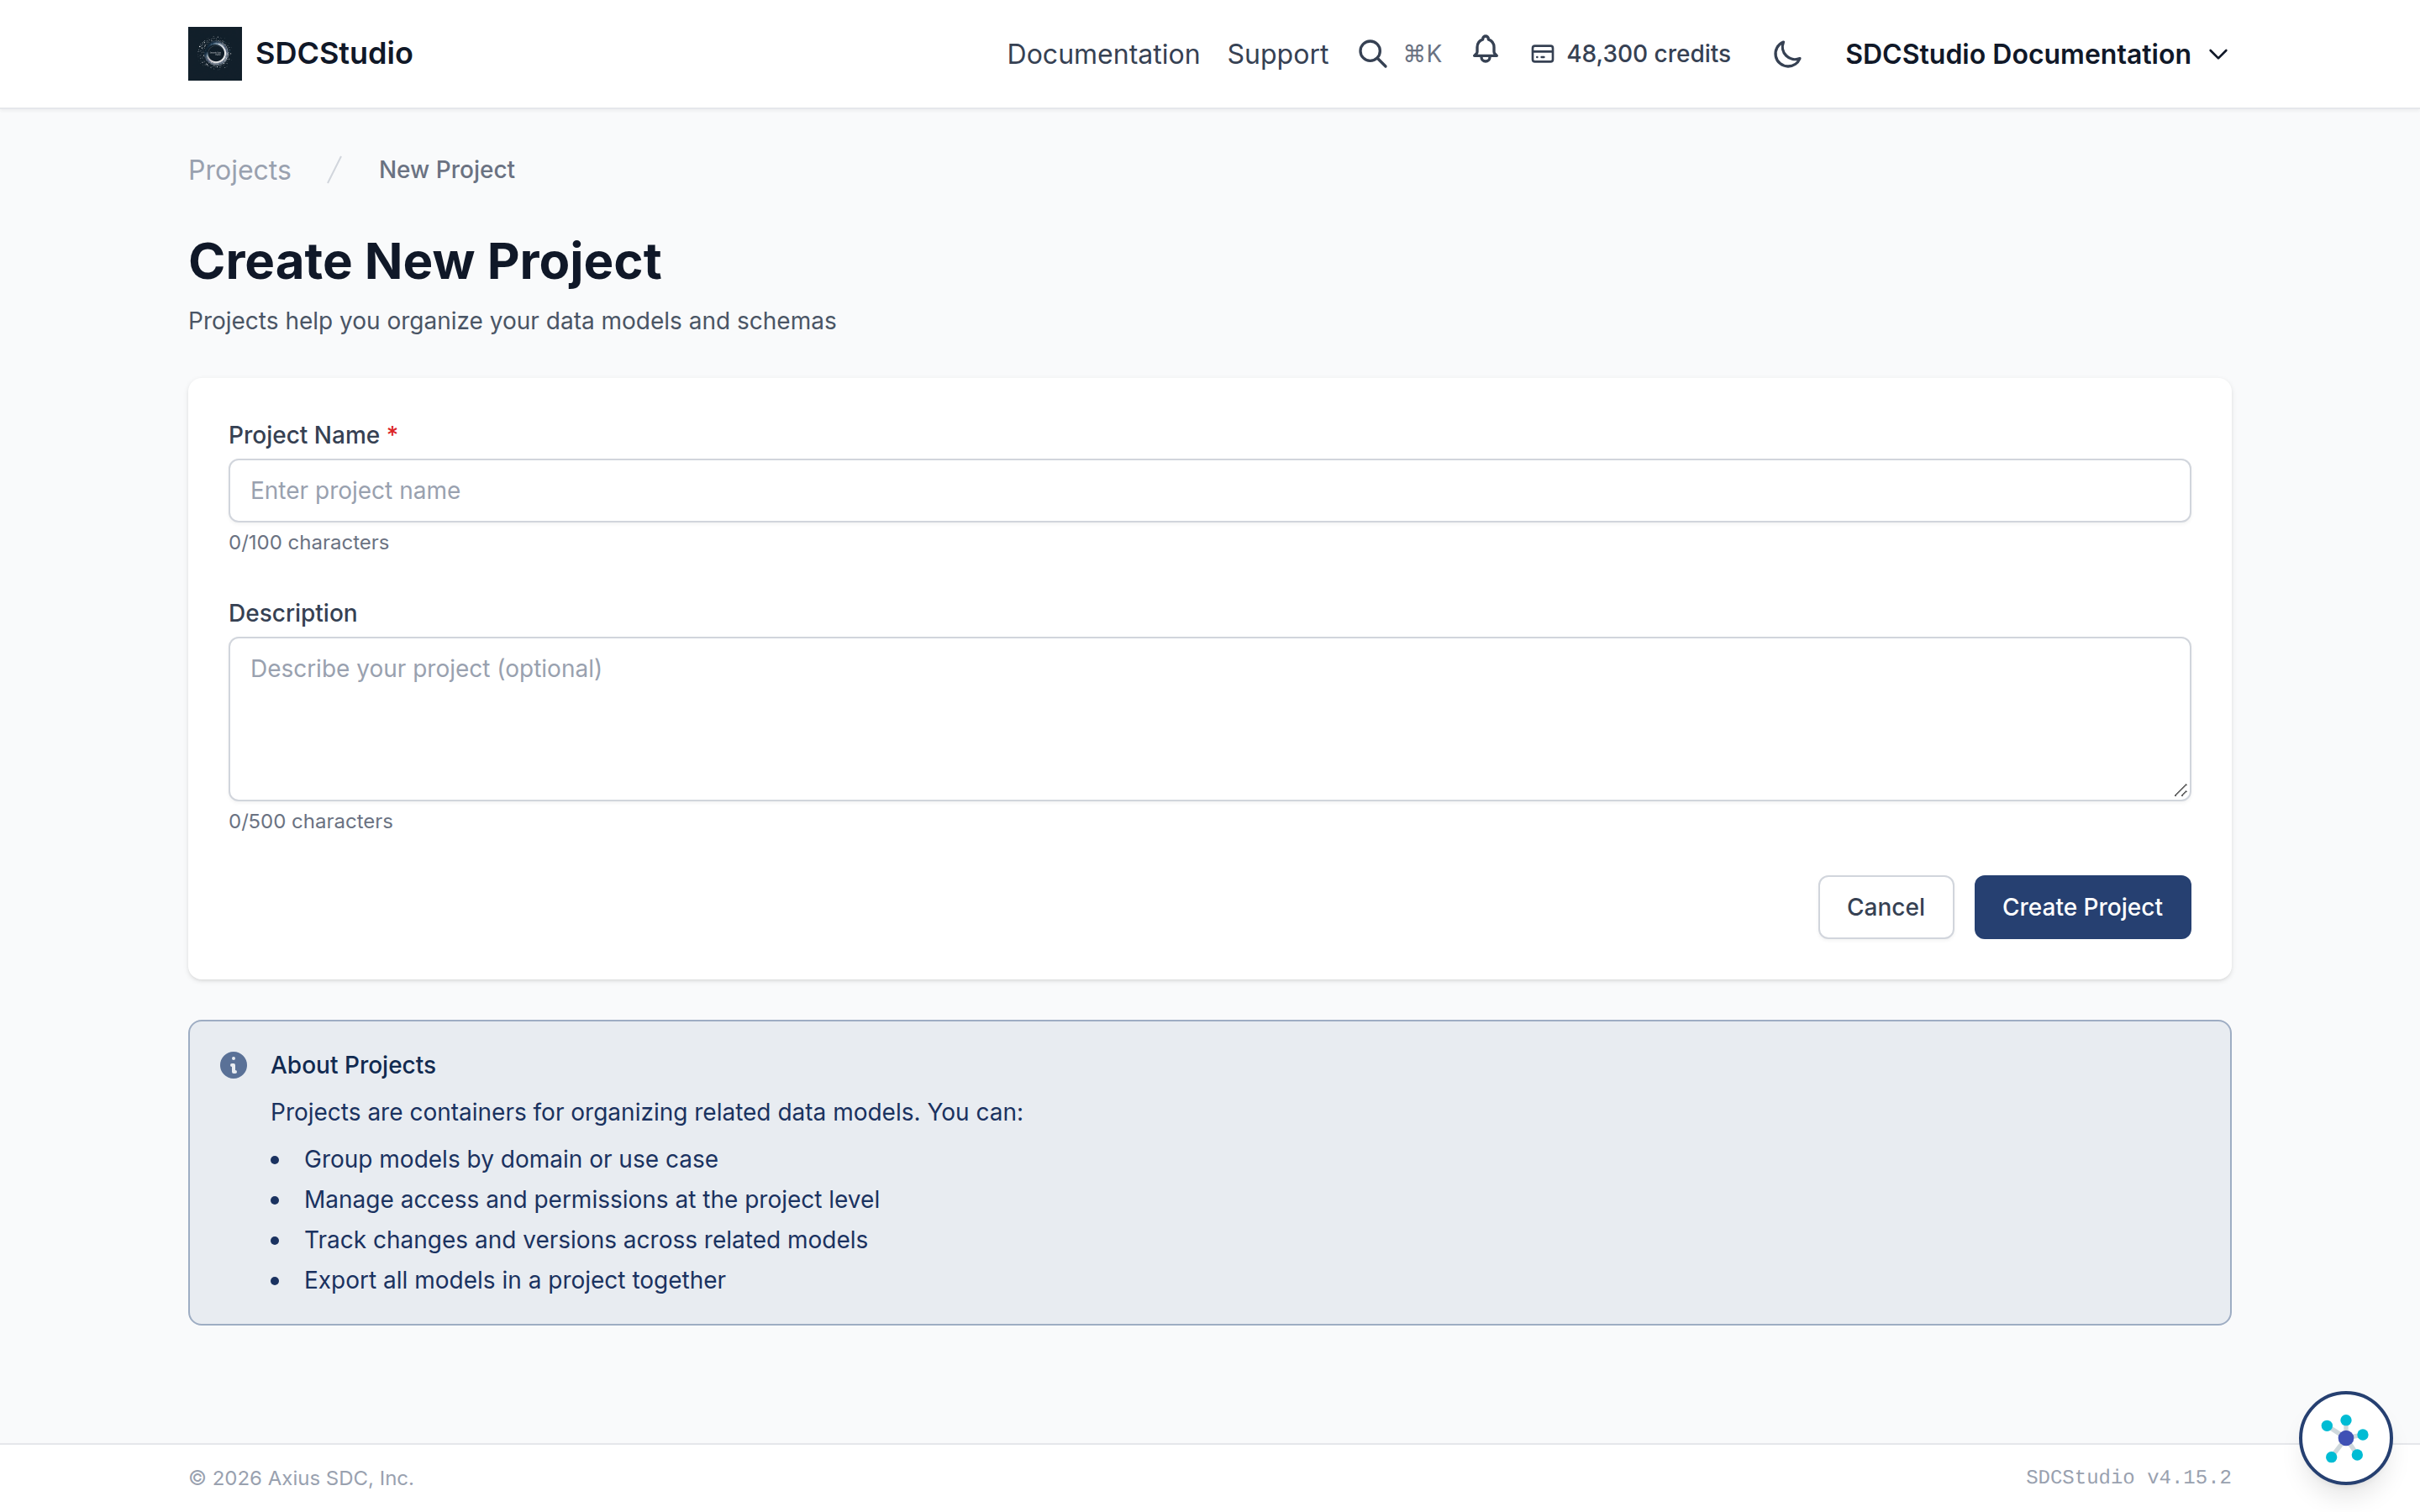
- Open "Projects" (
/app/projects) from the Dashboard - Click the "New Project" button
- Fill in the form:
- Name:
Customer Management - Description:
Learning SDCStudio with customer data - Click "Create Project"
You'll be taken to the project page: a details card, a Members card, and a Data Models (0) list with New Model (which opens the Model Wizard) and Advanced Form beside it. The project's team is created with it; members and roles are managed in the project page's Members section.
Step 2: Prepare Your Data
For this guide, create a file called customers.csv:
customer_id,first_name,last_name,email,phone,signup_date,status,total_purchases,last_purchase_amount
1001,Jane,Smith,jane.smith@email.com,+1-555-0101,2024-01-15,active,5,129.99
1002,John,Doe,john.doe@email.com,+1-555-0102,2024-02-20,active,3,89.50
1003,Maria,Garcia,maria.garcia@email.com,+1-555-0103,2024-03-10,inactive,0,0.00
1004,James,Wilson,james.wilson@email.com,+1-555-0104,2024-04-05,active,12,249.99
1005,Lisa,Anderson,lisa.anderson@email.com,+1-555-0105,2024-05-12,active,7,179.50
This Data Includes: - Identifiers: Customer IDs - Text: Names, email addresses - Phone Numbers: With country code pattern - Dates: ISO date format - Categories: Status (active/inactive) - Counts: Purchase counts - Decimals: Currency amounts
Step 3: Upload Your Data
Upload Process
Cost: 100 credits for each new component and each new cluster the upload creates, taken when processing completes; columns matched to existing components are free, and nothing is charged if processing fails.
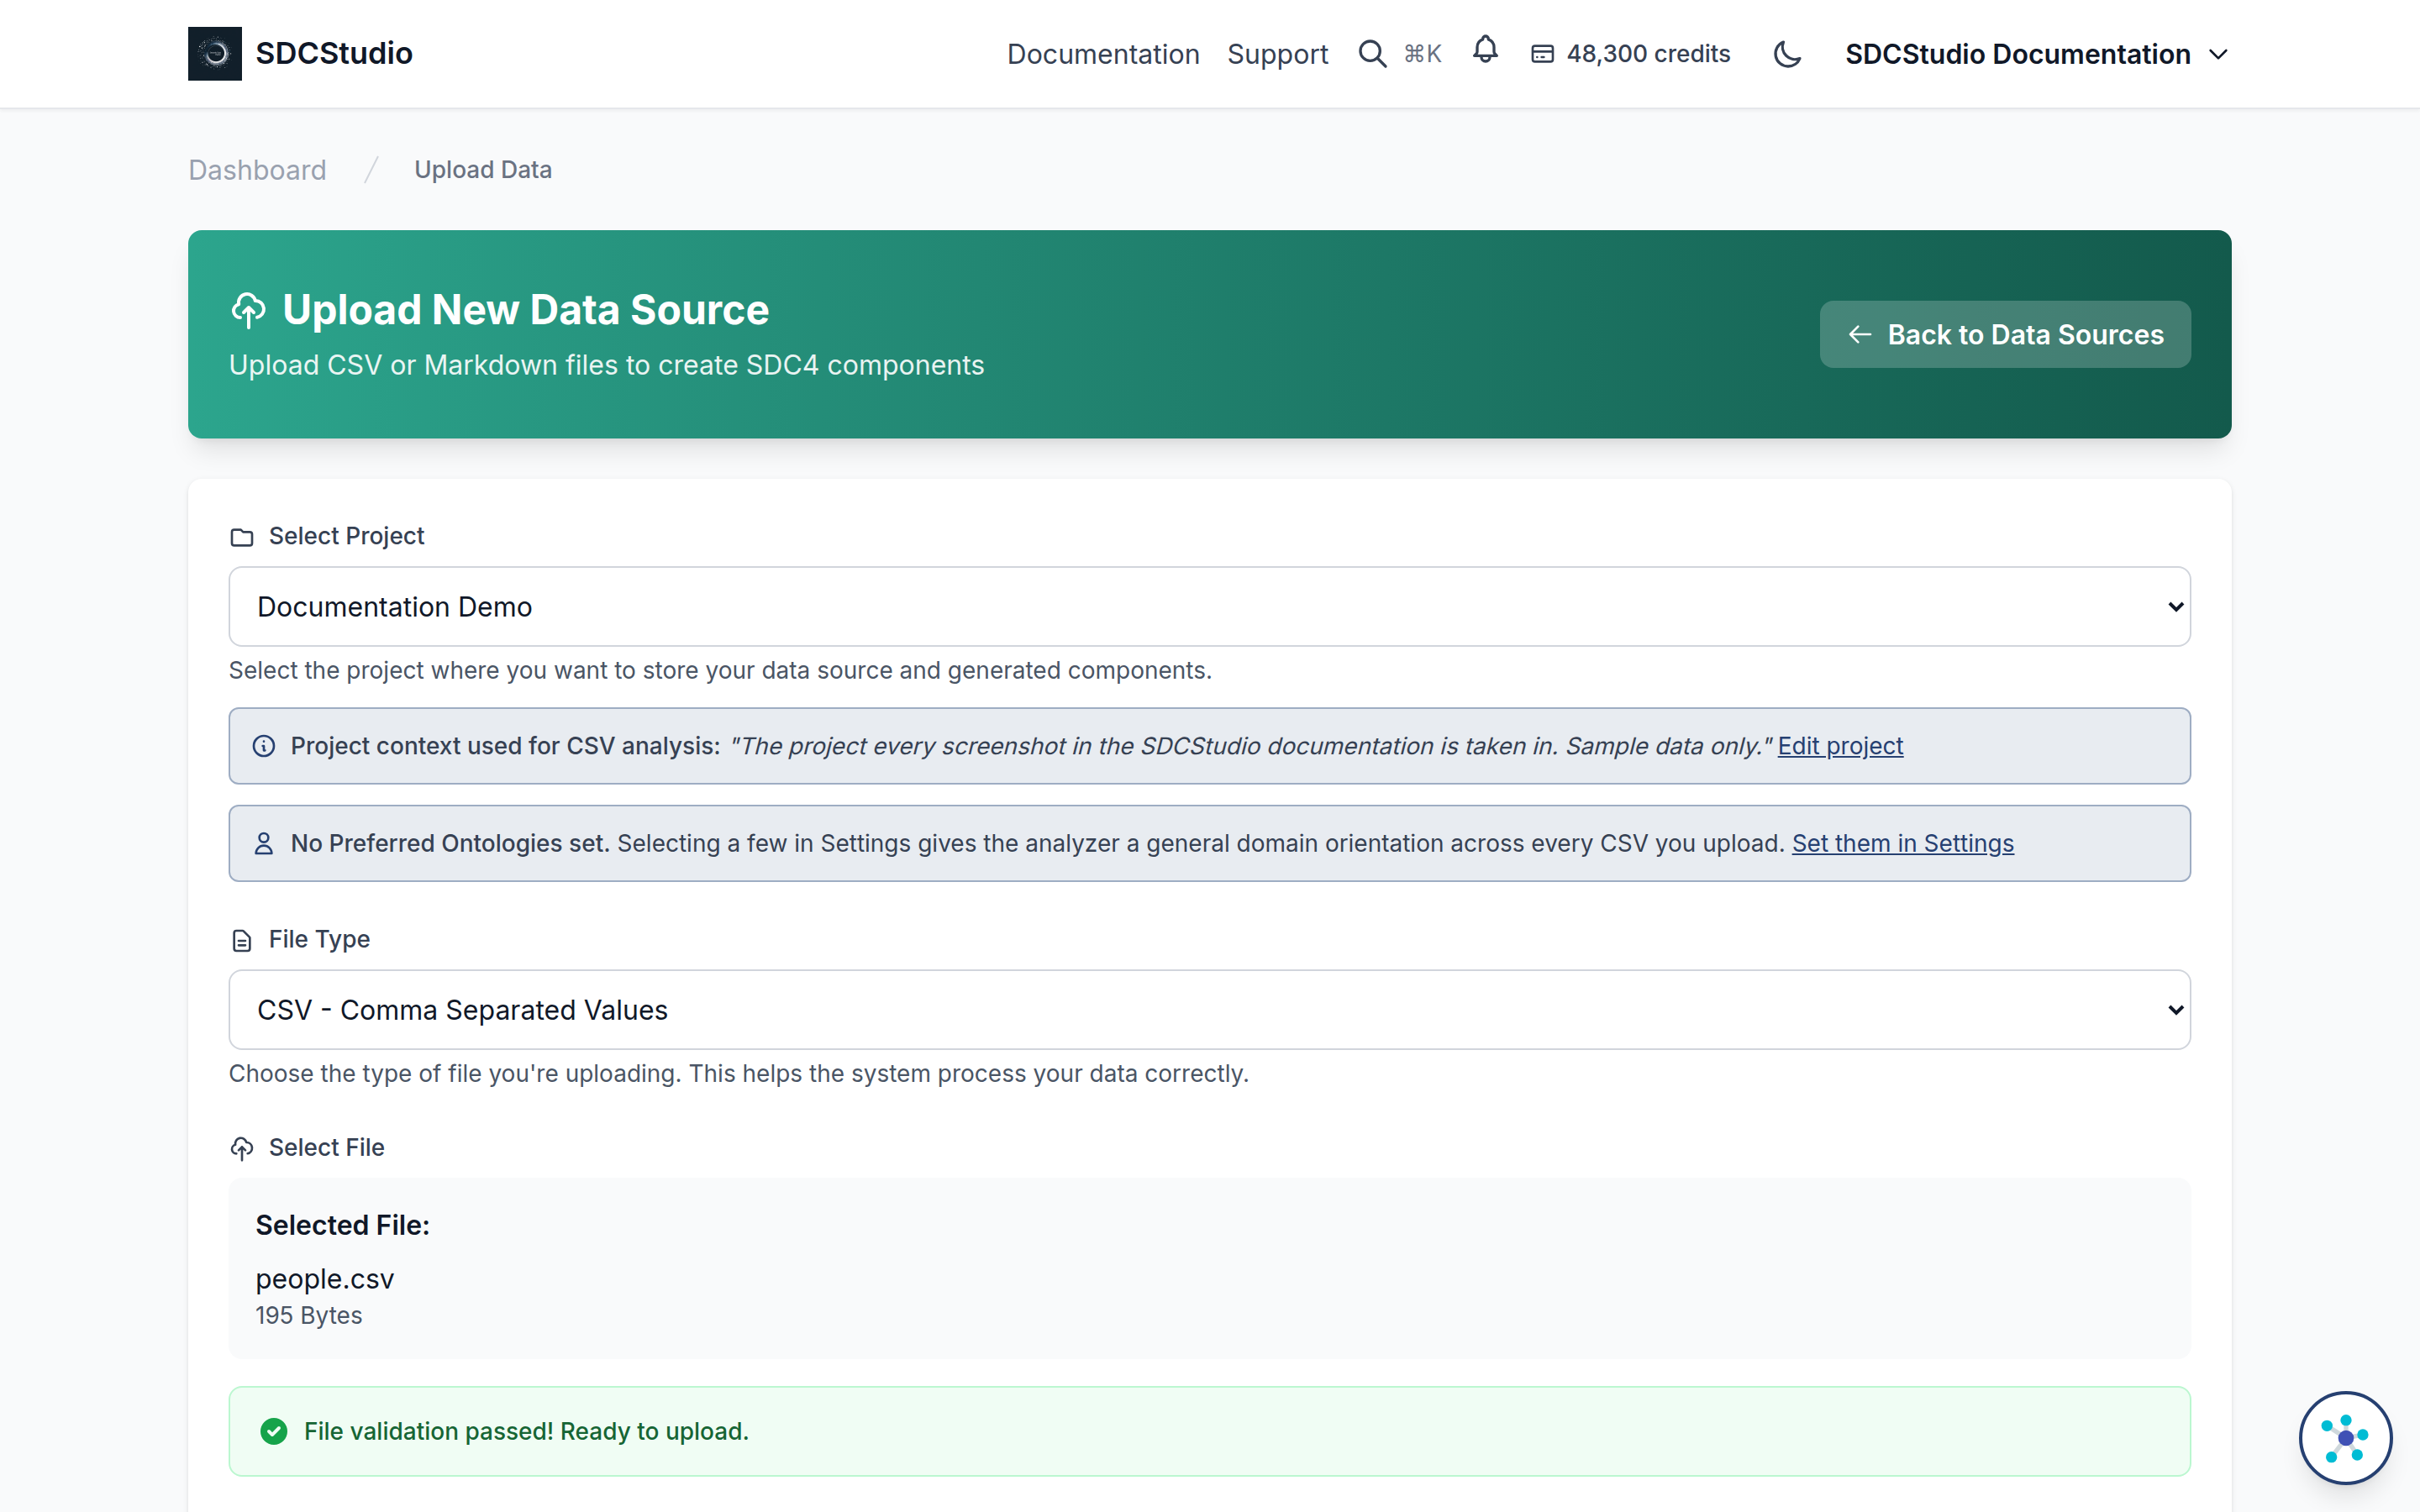
- Open the user menu and click Upload Data; this opens Data Sources (
/app/data-sources) - Click "Upload New Data" (
/app/upload) - Select Project:
Customer Management - Select File Type: CSV
- Choose a file: your
customers.csv(.csv or .md, up to 50 MB) - Click "Upload File"
Your file appears in the Data Sources list with the status Uploaded.
Following Progress
- The Data Sources page (
/app/data-sources) shows each upload's status badge; reload it to see a change
Step 4: Watch the Two-Stage Processing
SDCStudio works in two phases. Watch the status badge on the Data Sources page.
Phase 1: Structural Parsing (Fast)
Status Flow: Uploaded → Parsing → Parsed
What's Happening Behind the Scenes:
The parser is:
- Detecting the file format (CSV)
- Identifying columns:
- customer_id, first_name, last_name, email, phone
- signup_date, status, total_purchases, last_purchase_amount
- Inferring data types. For example, it might infer:
- customer_id: Integer → XdCount
- first_name, last_name: Text → XdString
- email: Text with pattern → XdString (with an email pattern)
- phone: Text with pattern → XdString (with a phone pattern)
- signup_date: Date → XdTemporal
- status: Category text → XdString (with an enumeration)
- total_purchases: Integer count → XdCount
- last_purchase_amount: Decimal → a quantified type with a currency unit
A parsing failure shows as Error. You can keep working while processing runs.
Phase 2: Agent Enhancement (Longer)
Status Flow: Agent Processing → Modeling → Completed
What's Happening:
The agents, informed by your preferred ontologies, might propose:
- Semantic Analysis:
- "customer_id is a unique identifier"
- "email is contact information"
-
"status represents account state"
-
Pattern Recognition:
- An email pattern such as
^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$ - A phone pattern: country code + area code + number
-
Status values limited to "active" or "inactive"
-
Ontology Matching (your ontologies at work):
- Matching "email" and "phone" to contact terms in your preferred ontologies
-
Applying domain-specific validation from your ontologies
-
Validation Rules:
- Email: required, pattern validation, maximum length
- Phone: optional, pattern validation
- Status: must be "active" or "inactive"
- Purchases: non-negative integer
-
Amount: non-negative decimal with a currency unit
-
Grouping:
- Every column's component is placed in one cluster named
customers Data Cluster
A failure here shows as Agent Error; the row offers Retry Processing, which reruns the agents without re-parsing the file.
Step 5: Review Your Generated Data Model
Once the status shows Completed:
Navigate to Your Model
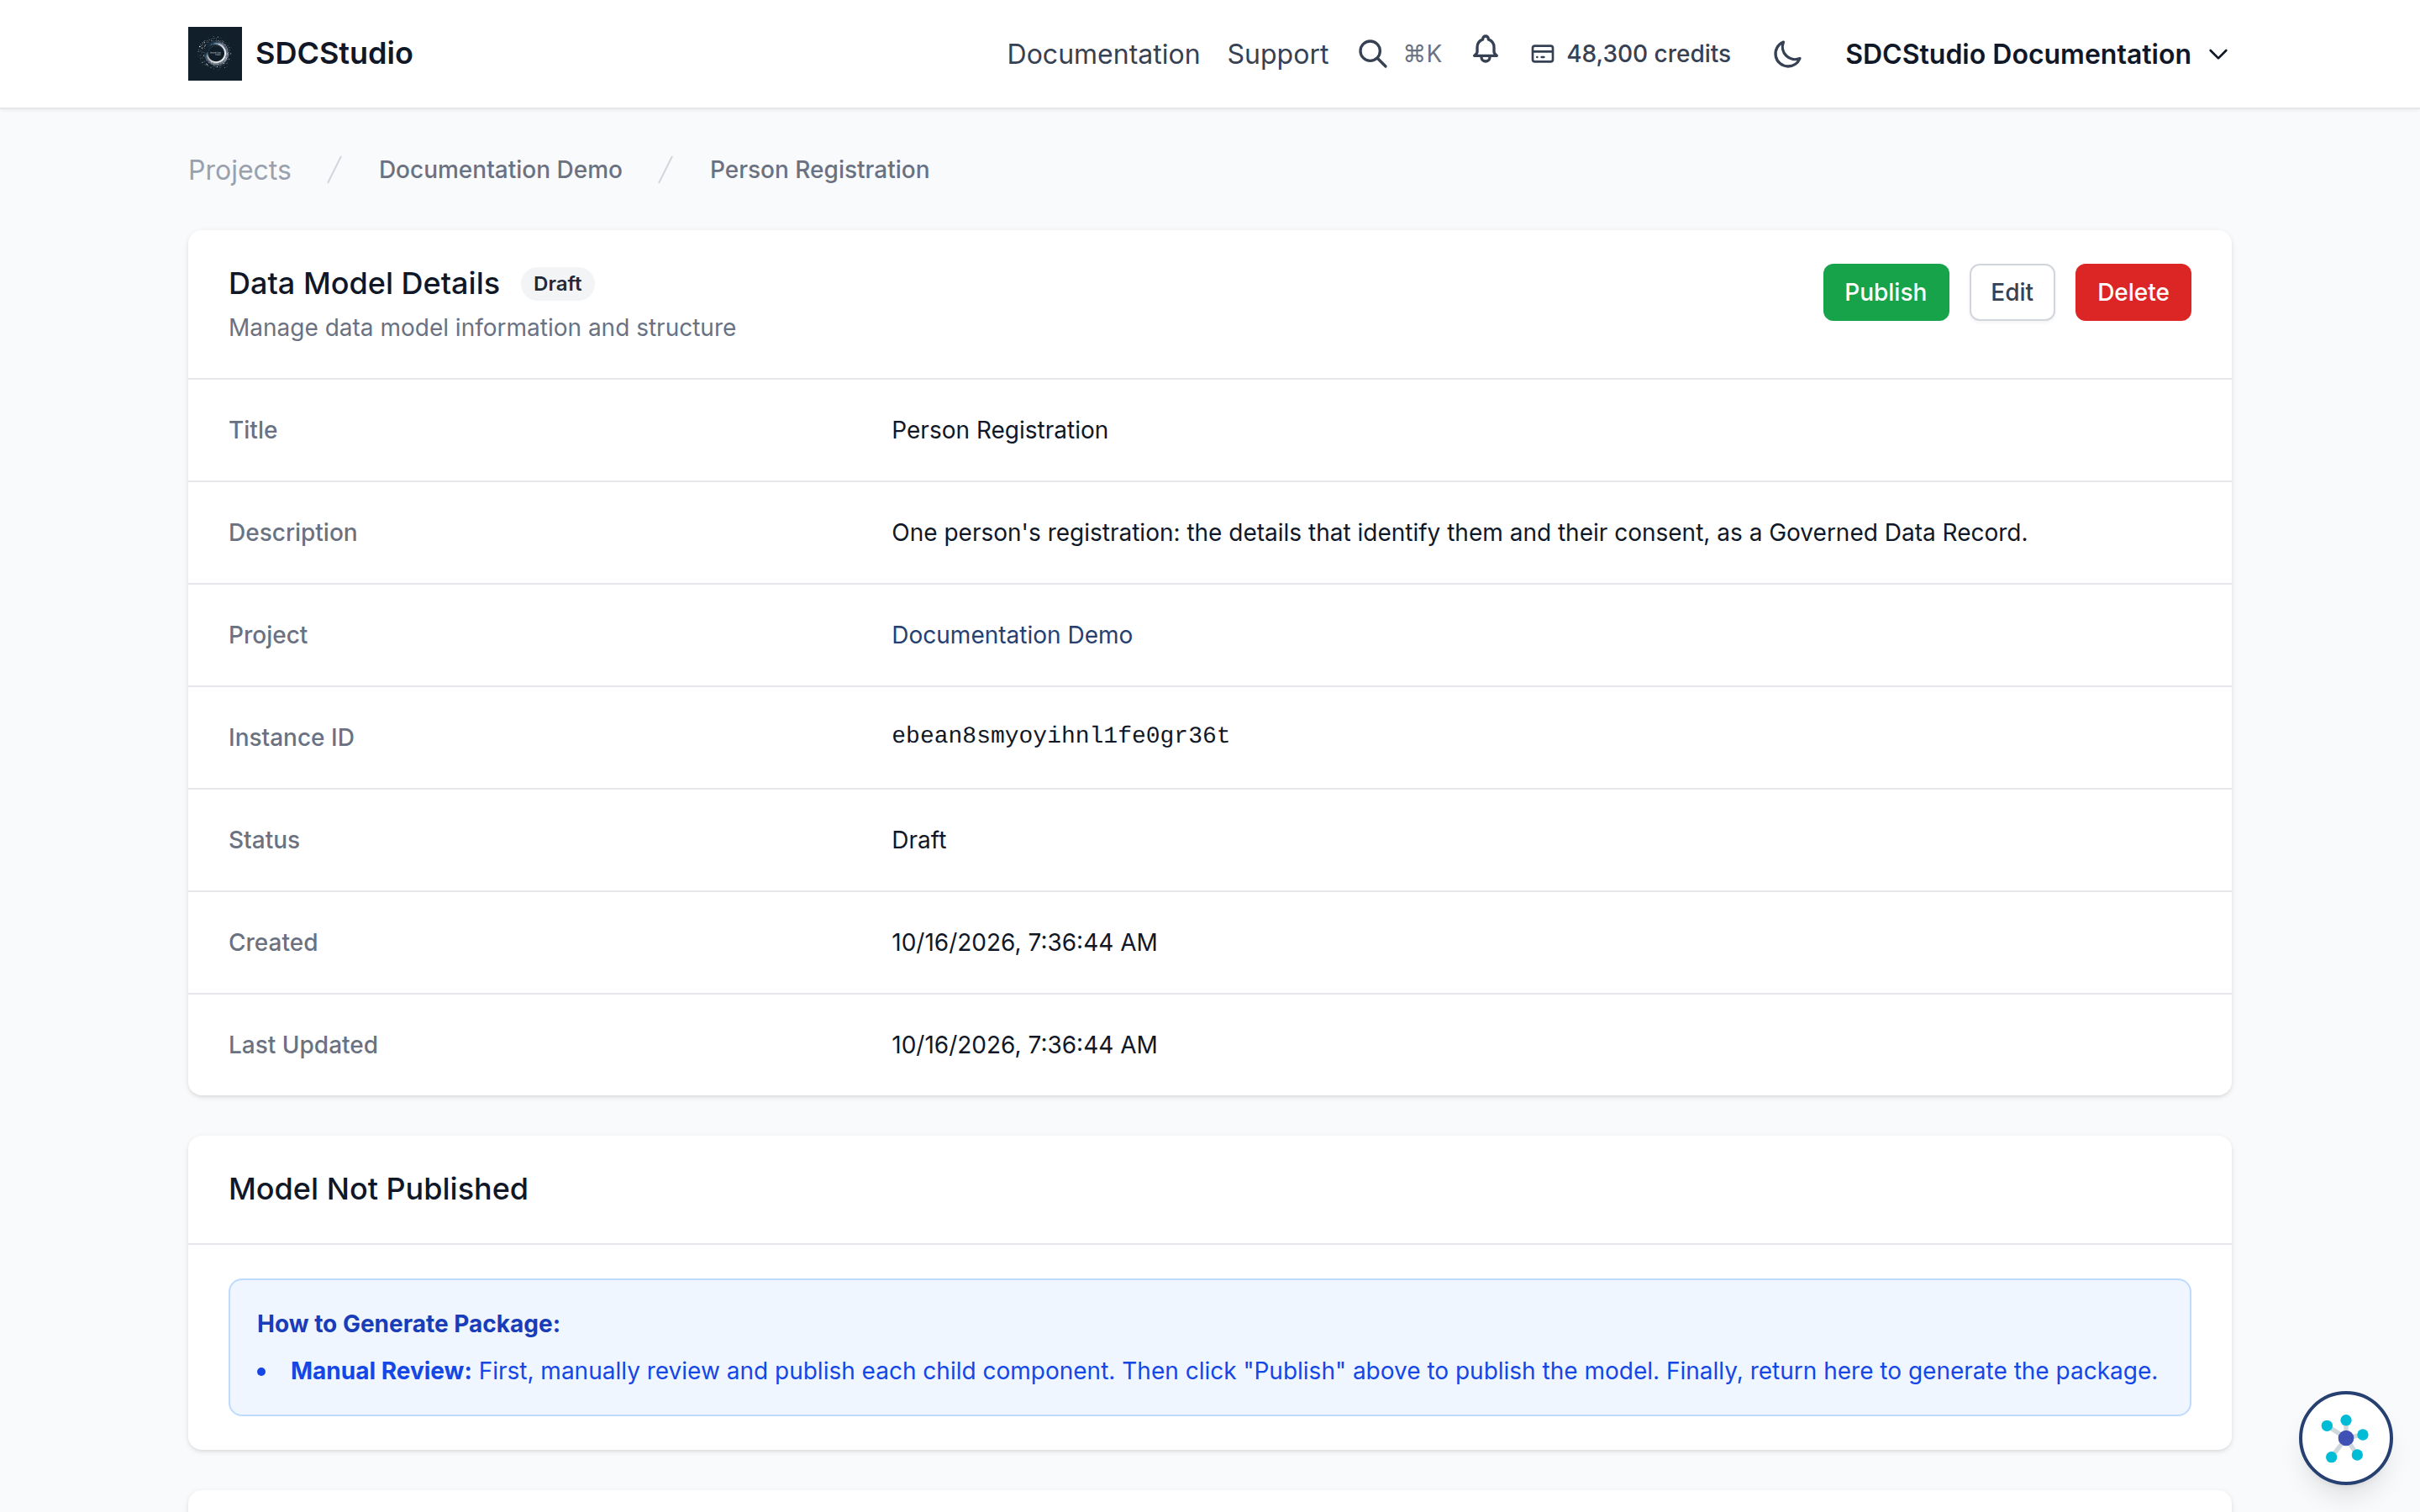
- Open your project from Projects; the new model appears in its Data Models list (or open Data Models,
/app/models) - Click the model name to open details
Explore the Model Structure
The model page shows a details card and a Data Model Visualization graph of the cluster and its components (hover a node for its type):
Data Model Level
- Title:
customers, the file name without its extension - Instance ID: Auto-generated CUID2, read-only
- Status:
Draft(ready to edit and publish) - Project:
Customer Management
Cluster Level
- Cluster:
customers Data Cluster, one cluster holding every column - Components: one per column; open the cluster from Components (
/app/components) and its page lists them under Included Components
Component Level
Open a component from Components or from the cluster's Included Components list to see the proposed details. For example, the agents might propose something like:
customer_id Component:
Type: XdCount (non-negative integer)
Label: "Customer ID"
Description: "Unique identifier for customer records"
Validation:
  - Min magnitude: 1
email Component:
Type: XdString (text)
Label: "Email Address"
Description: "Customer contact email"
Validation:
  - Format: email
  - Max Length: 320 characters
phone Component:
Type: XdString (text)
Label: "Phone Number"
Description: "Customer contact phone with country code"
Validation:
  - Format: phone
signup_date Component:
Type: XdTemporal (date/time)
Label: "Signup Date"
Description: "Date customer registered"
Validation:
  - Allowed: date (YYYY-MM-DD)
status Component:
Type: XdString (text)
Label: "Account Status"
Description: "Current status of customer account"
Validation:
  - Enumeration: ["active", "inactive"]
  - Default: "active"
last_purchase_amount Component:
Type: quantified decimal
Label: "Last Purchase Amount"
Description: "Value of most recent purchase"
Validation:
  - Min magnitude: 0.00
  - Units: USD (currency)
What to Check
Confirm that the agents: - Chose appropriate data types - Added meaningful descriptions - Proposed sensible validation rules - Detected the patterns in your data - Placed every column in the cluster
Anything that is wrong is corrected in the next step, before publishing.
Step 6: Customize Your Model (Optional but Recommended)
Refine the agents' work to match your exact requirements. Components can only be edited while unpublished.
Edit a Component
Cost: nothing. Edits are free.
- Open Components (
/app/components), clickstatus, and click Edit - Review the proposed settings across the form steps (Basic Information, the type's Constraints step such as String Constraints, Advanced Settings, Semantic Linking, Review & Save)
- Modify if needed:
- Add more enumeration values if you have other statuses
- Add documentation about state transitions
- Set a default value
- Click "Save" on the Review & Save step
Add Custom Validation
- Edit the "email" component
- Add or modify:
- Pattern: keep the proposed email regex or customize it
- Business rule documentation
- Save changes
Enhance Descriptions
- Edit any component
- Add business context:
- "This field is used by the billing system"
- "Validated against customer database daily"
- "Required for GDPR compliance"
- Save
Descriptions travel with the component into every generated output, so this is where the meaning of the data is recorded.
Step 7: Publish Your Model
Publishing makes your model immutable and enables output generation.
Publish Process
Cost: nothing. Publishing is free.
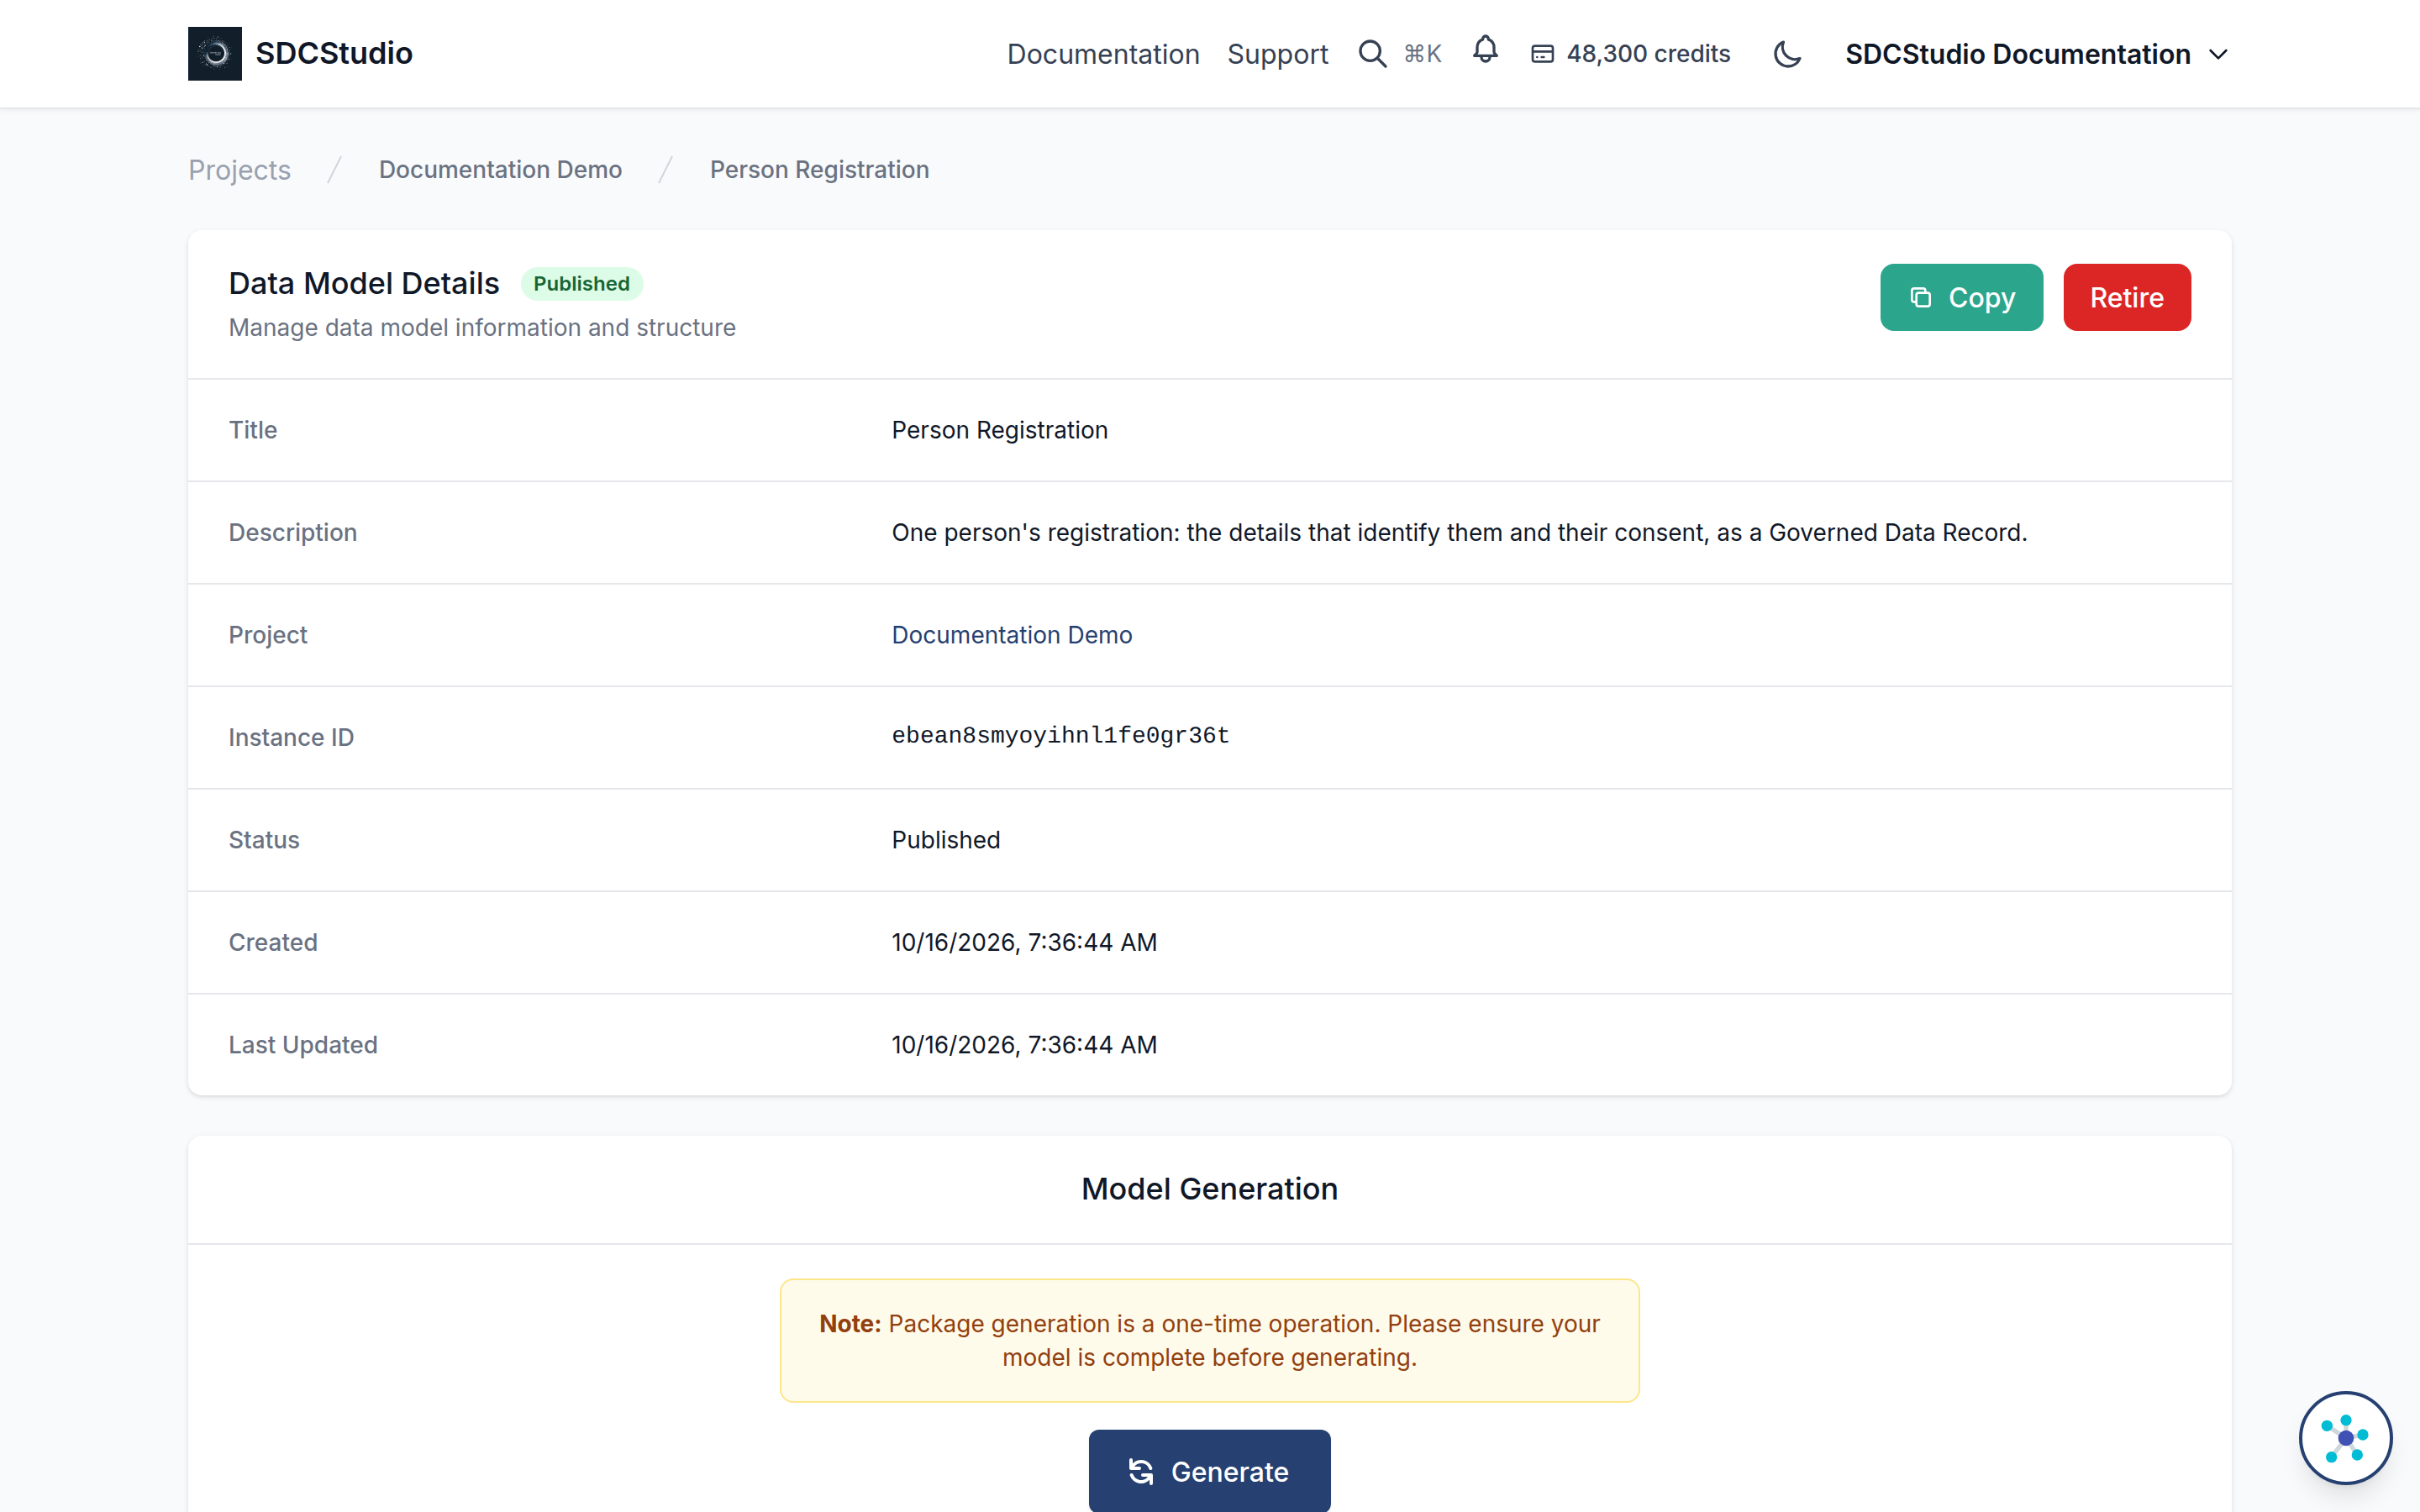
- Publish each child component first: edit it and click Save & Publish on its Review & Save step. An unpublished model's page shows a Model Not Published card with these steps
- Publish the cluster: open
customers Data Clusterfrom Components, click Edit Cluster, and click Save & Publish on its Review & Save step; the model will not publish while its data cluster is a draft - On the model page, click Publish (the project owner, a team admin or staff; a member asks one of them)
Status changes to Published at once. There is no confirmation dialog, only a success message, so check your components before clicking.
What Happened: - The model and its components are now immutable - Output generation is enabled - Applications can be generated
To change a published item, use Copy: it creates an unpublished copy labeled "COPY -- ..." that records its origin (prov:wasDerivedFrom). Rename the label before publishing the copy. An owner or admin can Retire a published item; a retired item stays resolvable but is no longer listed.
Step 8: Generate the Output Package
Now you can create the output package from your published model.
What the Package Contains
The package is one ZIP with every format:
1. XSD Schema (XML Schema Definition)
- Purpose: XML validation schema
- Use: Data validation, integration, XML tools
- Includes: All types, constraints, documentation
2. XML Template (the Governed Data Record with placeholders)
- Purpose: the record's shape with a placeholder at every value; it validates once the placeholders are filled
- Use: Testing, documentation, examples
- Includes: Every field, with a placeholder for each value (the JSON instance below carries sample values)
3. JSON (the same record as JSON)
- Purpose: JSON serialization of the Governed Data Record
- Use: REST APIs, web apps
- Includes: The same structure as the XML template
4. JSON-LD (Linked Data schema)
- Purpose: Semantic web integration
- Use: Knowledge graphs, semantic search
- Includes: RDF mappings, ontology links
5. HTML Documentation
- Purpose: Human-readable documentation
- Use: Team reference, stakeholder review
- Includes: All fields and descriptions
6. RDF (RDF/XML .rdf and Turtle .ttl)
- Purpose: Triple store integration
- Use: Semantic databases, SPARQL queries
- Includes: Subject-predicate-object statements
7. SHACL (Shape constraints, _shacl.ttl)
- Purpose: RDF validation rules
- Use: Semantic validation, data quality
- Includes: All validation constraints as shapes, with a
SHACL_README.md
8. GQL (Graph Query Language)
- Purpose: Property graph database statements
- Use: Neo4j, graph databases
- Includes: CREATE statements for nodes/edges
9. README-AI-PROMPT.md
- Purpose: A prompt for working with the model in an AI assistant
10. Checksum and stylesheet
- Includes: a
.sha1checksum of the schema, anddm-description.xsl, the stylesheet the schema references
How to Generate
Cost: nothing. Publishing and generating the package are free. Download App, further down the page, is 1,500 credits the first time for this model; later downloads of it are free.
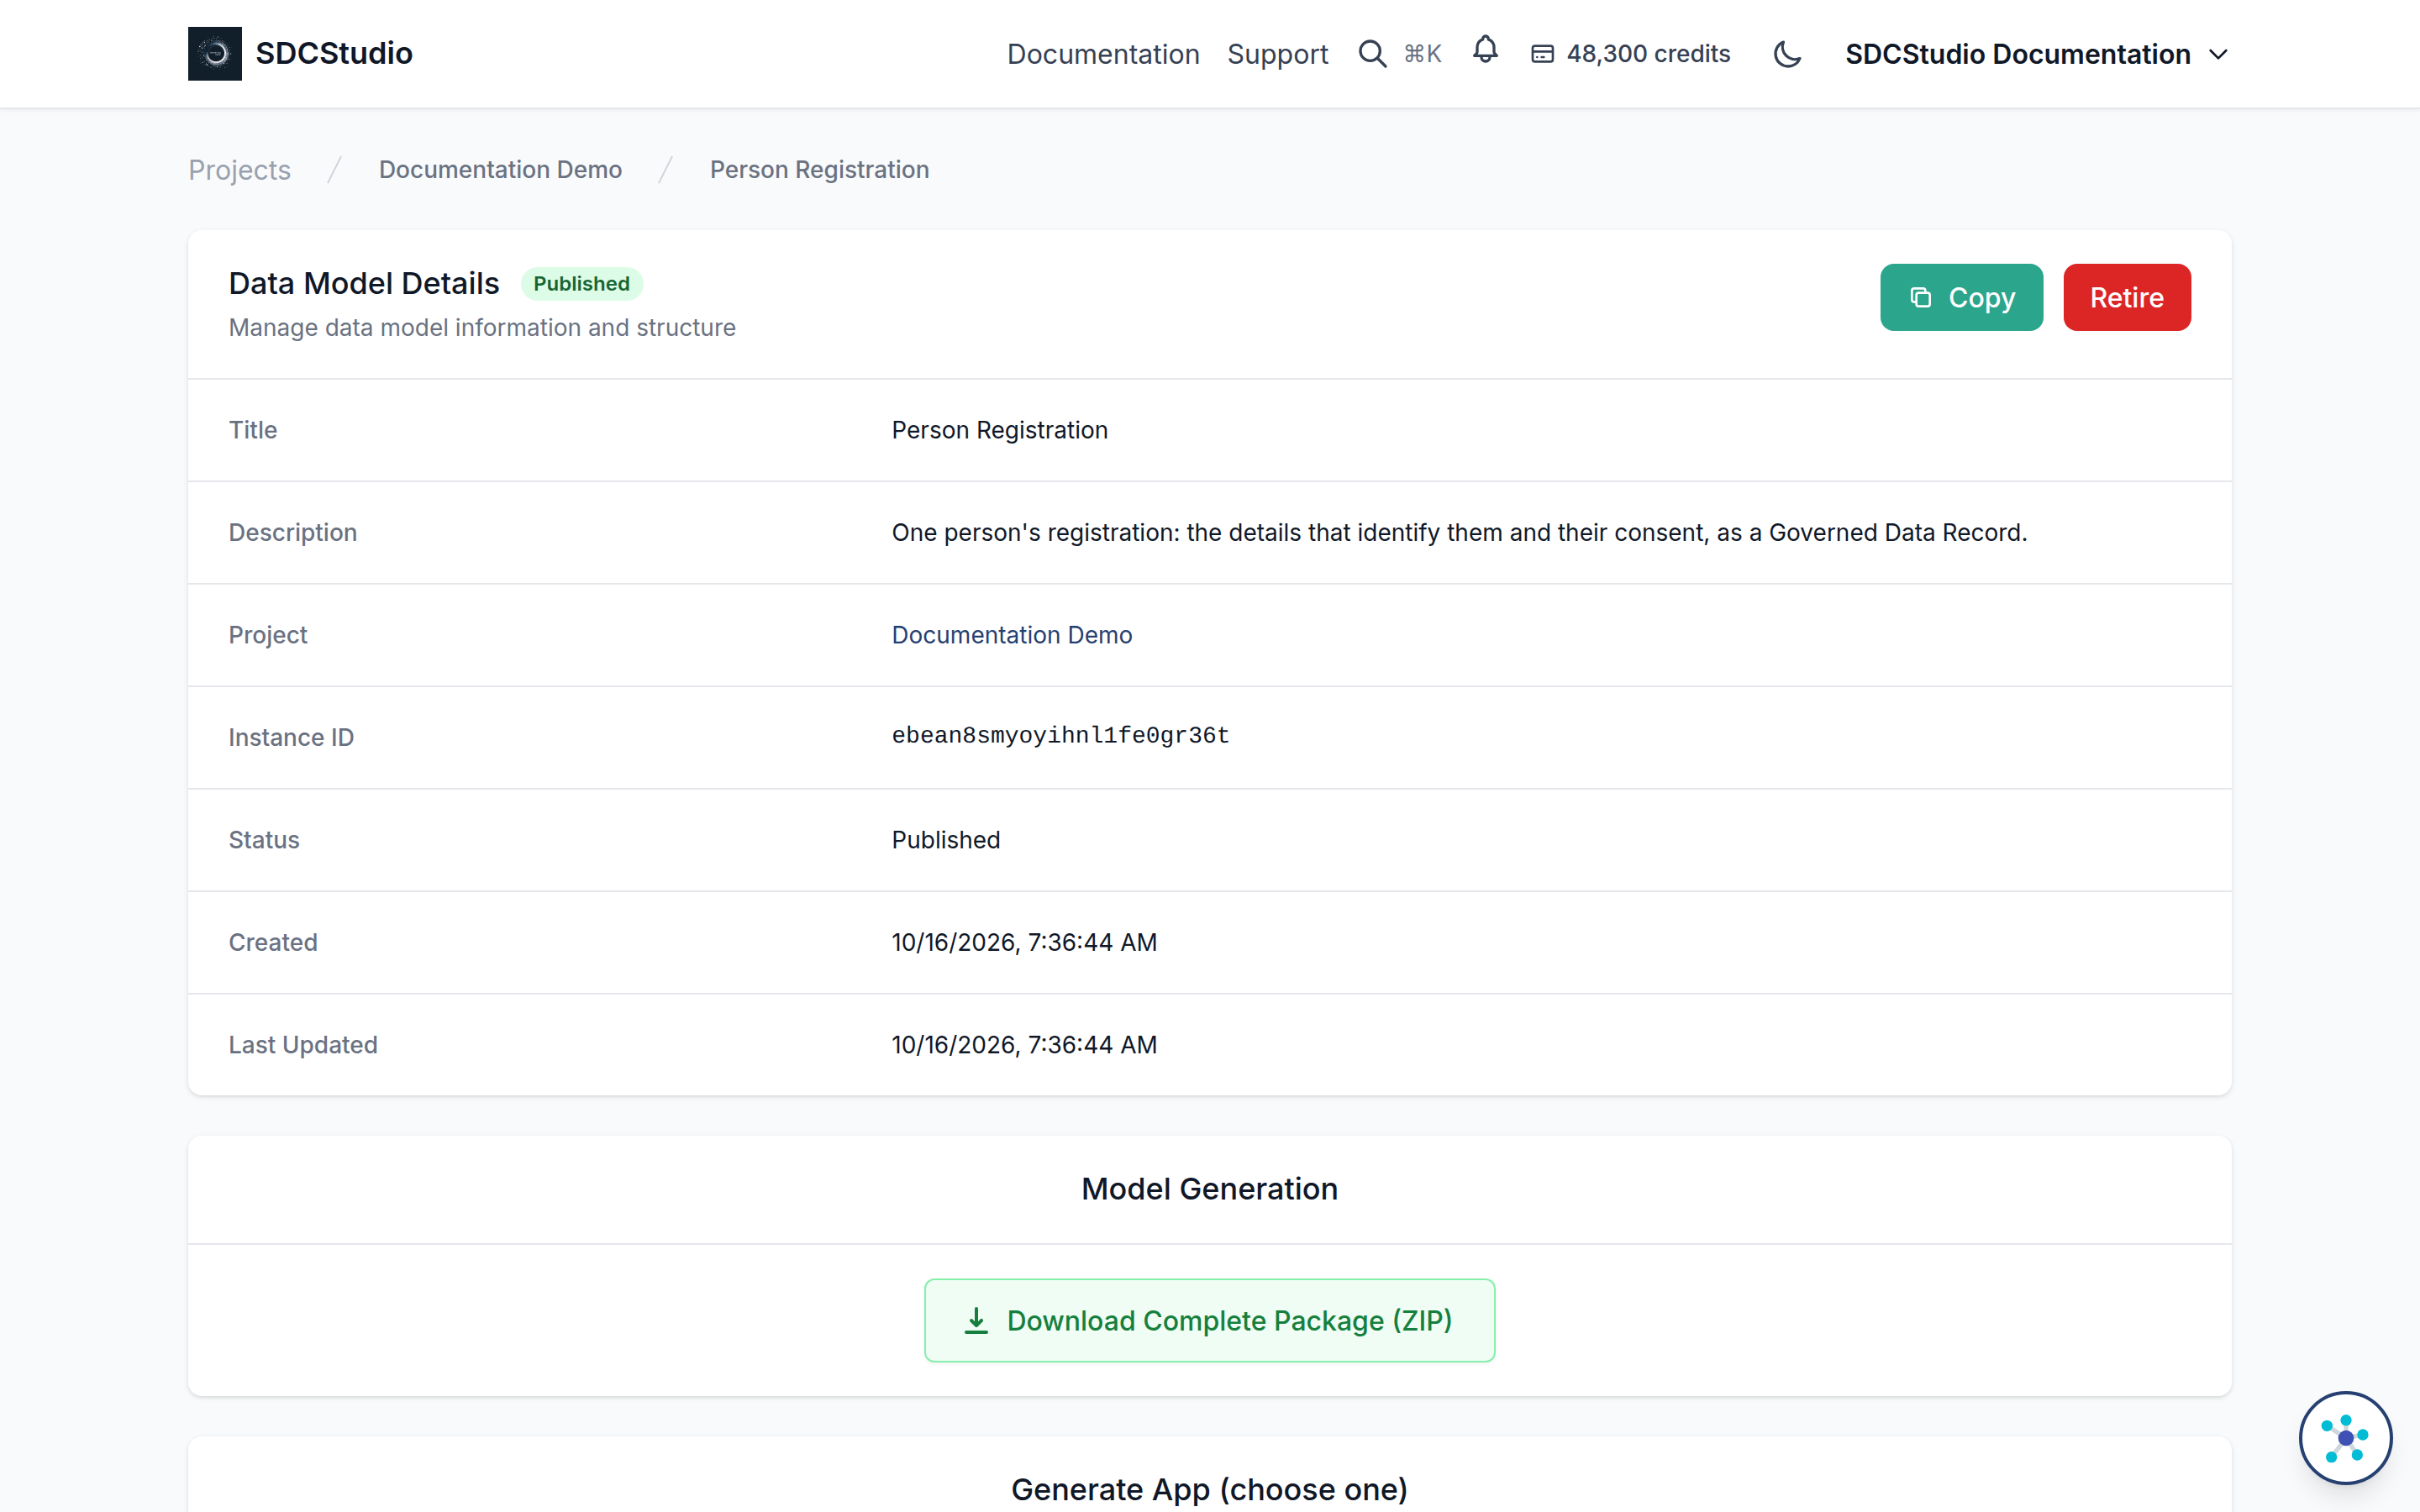
- On the published model page, find the Model Generation card
- Click "Generate". Generation is a one-time operation, so make sure the model is complete first
- Click "Download Complete Package (ZIP)"
Step 9: Generate an Application (Advanced Optional)
SDCStudio can generate a complete application from your published model.
App Generation
- On the model page, once the package exists, find the Generate App (choose one) card below Model Generation
- Choose a profile:
- Lightweight: open source stack for development and small deployments
- Enterprise: the full stack, adding OWL reasoning, a temporal record history and single sign-on (requires 6 GB or more of free RAM to run)
- Click "Generate" under the profile you want
- Click "Download App" when it finishes
- Extract the ZIP and follow the README inside to run it
Cost: 1,500 credits for the first Download App of this model, either profile; later downloads of it are free.
See: App Generation Guide for what each profile contains.
What You've Accomplished
You've completed the full SDCStudio workflow:
- Configured Settings with ontology uploads (the foundation)
- Navigated the web interface confidently
- Created a project to organize your work
- Uploaded a CSV file with customer data
- Watched the agents analyze your data in two phases using your ontologies
- Reviewed proposed components with semantic enrichment
- Customized components with your business rules
- Published your data model
- Generated the output package (XSD, XML, JSON, and more)
- (Optional) Generated a complete web application
Key Takeaways
Settings and Ontologies are Critical
- Upload ontologies first, they drive semantic quality
- Update ontologies as your domain evolves
- Mark the ones that matter as preferred
The Two-Stage Pipeline
- Phase 1 (Fast): Structure parsing
- Phase 2 (Smart): Agent enhancement with ontologies
- Follow progress on the Data Sources page
Agents + Human Review
- The agents do the heavy lifting with ontology guidance
- You refine and add business context
- Publishing locks the result, so review first
Multiple Output Formats
- One model → one package, many formats
- XSD for validation
- JSON for APIs
- RDF for the semantic web
- Applications for end users
Next Steps
Enhance Your Skills
- Data Modeling Guide
- Advanced component types
- Complex structures and relationships
-
Best practices for model design
- Finding and preparing ontologies
- Creating custom vocabularies
-
Ontology best practices
- Deep dive into each output format
- Integration strategies
Try Different Scenarios
- Healthcare Data: Patient records with the FHIR ontology
- Financial Data: Transactions with an accounting vocabulary
- IoT Data: Sensor readings with units and quantified types
- Document Metadata: Content with the Dublin Core ontology
Build Your Component Library
- Create reusable components across projects
- Establish organization standards
- Share components with your team
- Browse the public libraries (Default, NIEM, FHIR, NIH_CDE, SINAN, Business Documents, and others) and copy what you can build on
Troubleshooting
File Won't Upload
- Check the file size (50 MB limit)
- Check the file type (.csv or .md only)
- Verify the CSV format (headers in the first row)
- Ensure UTF-8 encoding
Processing Stuck
- Watch the Data Sources page; reload it to see a change
- A row stuck in Uploaded offers Trigger Processing
- Click View Details on the row to see the error message
Agent Processing Failed
- Status: Agent Error
- Action: Click Retry Processing on the row
- Check: View Details on the row for the error
- Try: Simplifying the data structure
- Contact: contact@axius-sdc.com if it persists
Can't Publish Model
- Publish every child component, then the cluster, before the model
- A label starting with "COPY -- " must be renamed before publishing
- Only the project owner, a team admin or staff can publish
- Review validation errors shown in the form
Generation Fails
- Verify the model is published
- Review error messages in the Model Generation card
- Contact contact@axius-sdc.com if it persists
Getting Help
- Documentation: User Guides - Comprehensive feature docs
- Troubleshooting: Troubleshooting Guide - Common issues
- Support Email: contact@axius-sdc.com
Success Indicators
You're ready for advanced features when you can:
- Configure Settings and manage ontologies
- Navigate the web interface without hesitation
- Upload data and understand processing stages
- Review and customize proposed components
- Publish models and generate the output package
- Troubleshoot common issues independently
- Explain how ontologies improve semantic quality
Ready to explore advanced features? Check out the Data Modeling Guide for complex structures, or Semantic Enhancement to master ontology integration.