Uploading and Processing Data
Overview
SDCStudio turns a CSV file or a Markdown template into a draft data model: one component per column, one cluster holding those components, and a data model that owns the cluster. You upload the file, the server processes it in two background stages, and you follow the result on the Data Sources page. This guide covers the upload, the two stages, the statuses and the cost. What the analysis decides for each column is described in AI Processing.
Supported files
Two file types are accepted, chosen by the file extension:
- CSV (
.csv): a header row of column names followed by data rows. The first five values of each column are what the analysis sees. - Markdown template (
.md): a template with YAML front matter and at least one## Data:section. The format is defined in Template Format; the Upload page checks the front matter before it lets you upload.
Any other extension is rejected with Unsupported file type. Export spreadsheets to CSV first; a paper or PDF form can be converted into a Markdown template with Form2SDCTemplate. The Upload page refuses files over 50 MB.
The Upload page
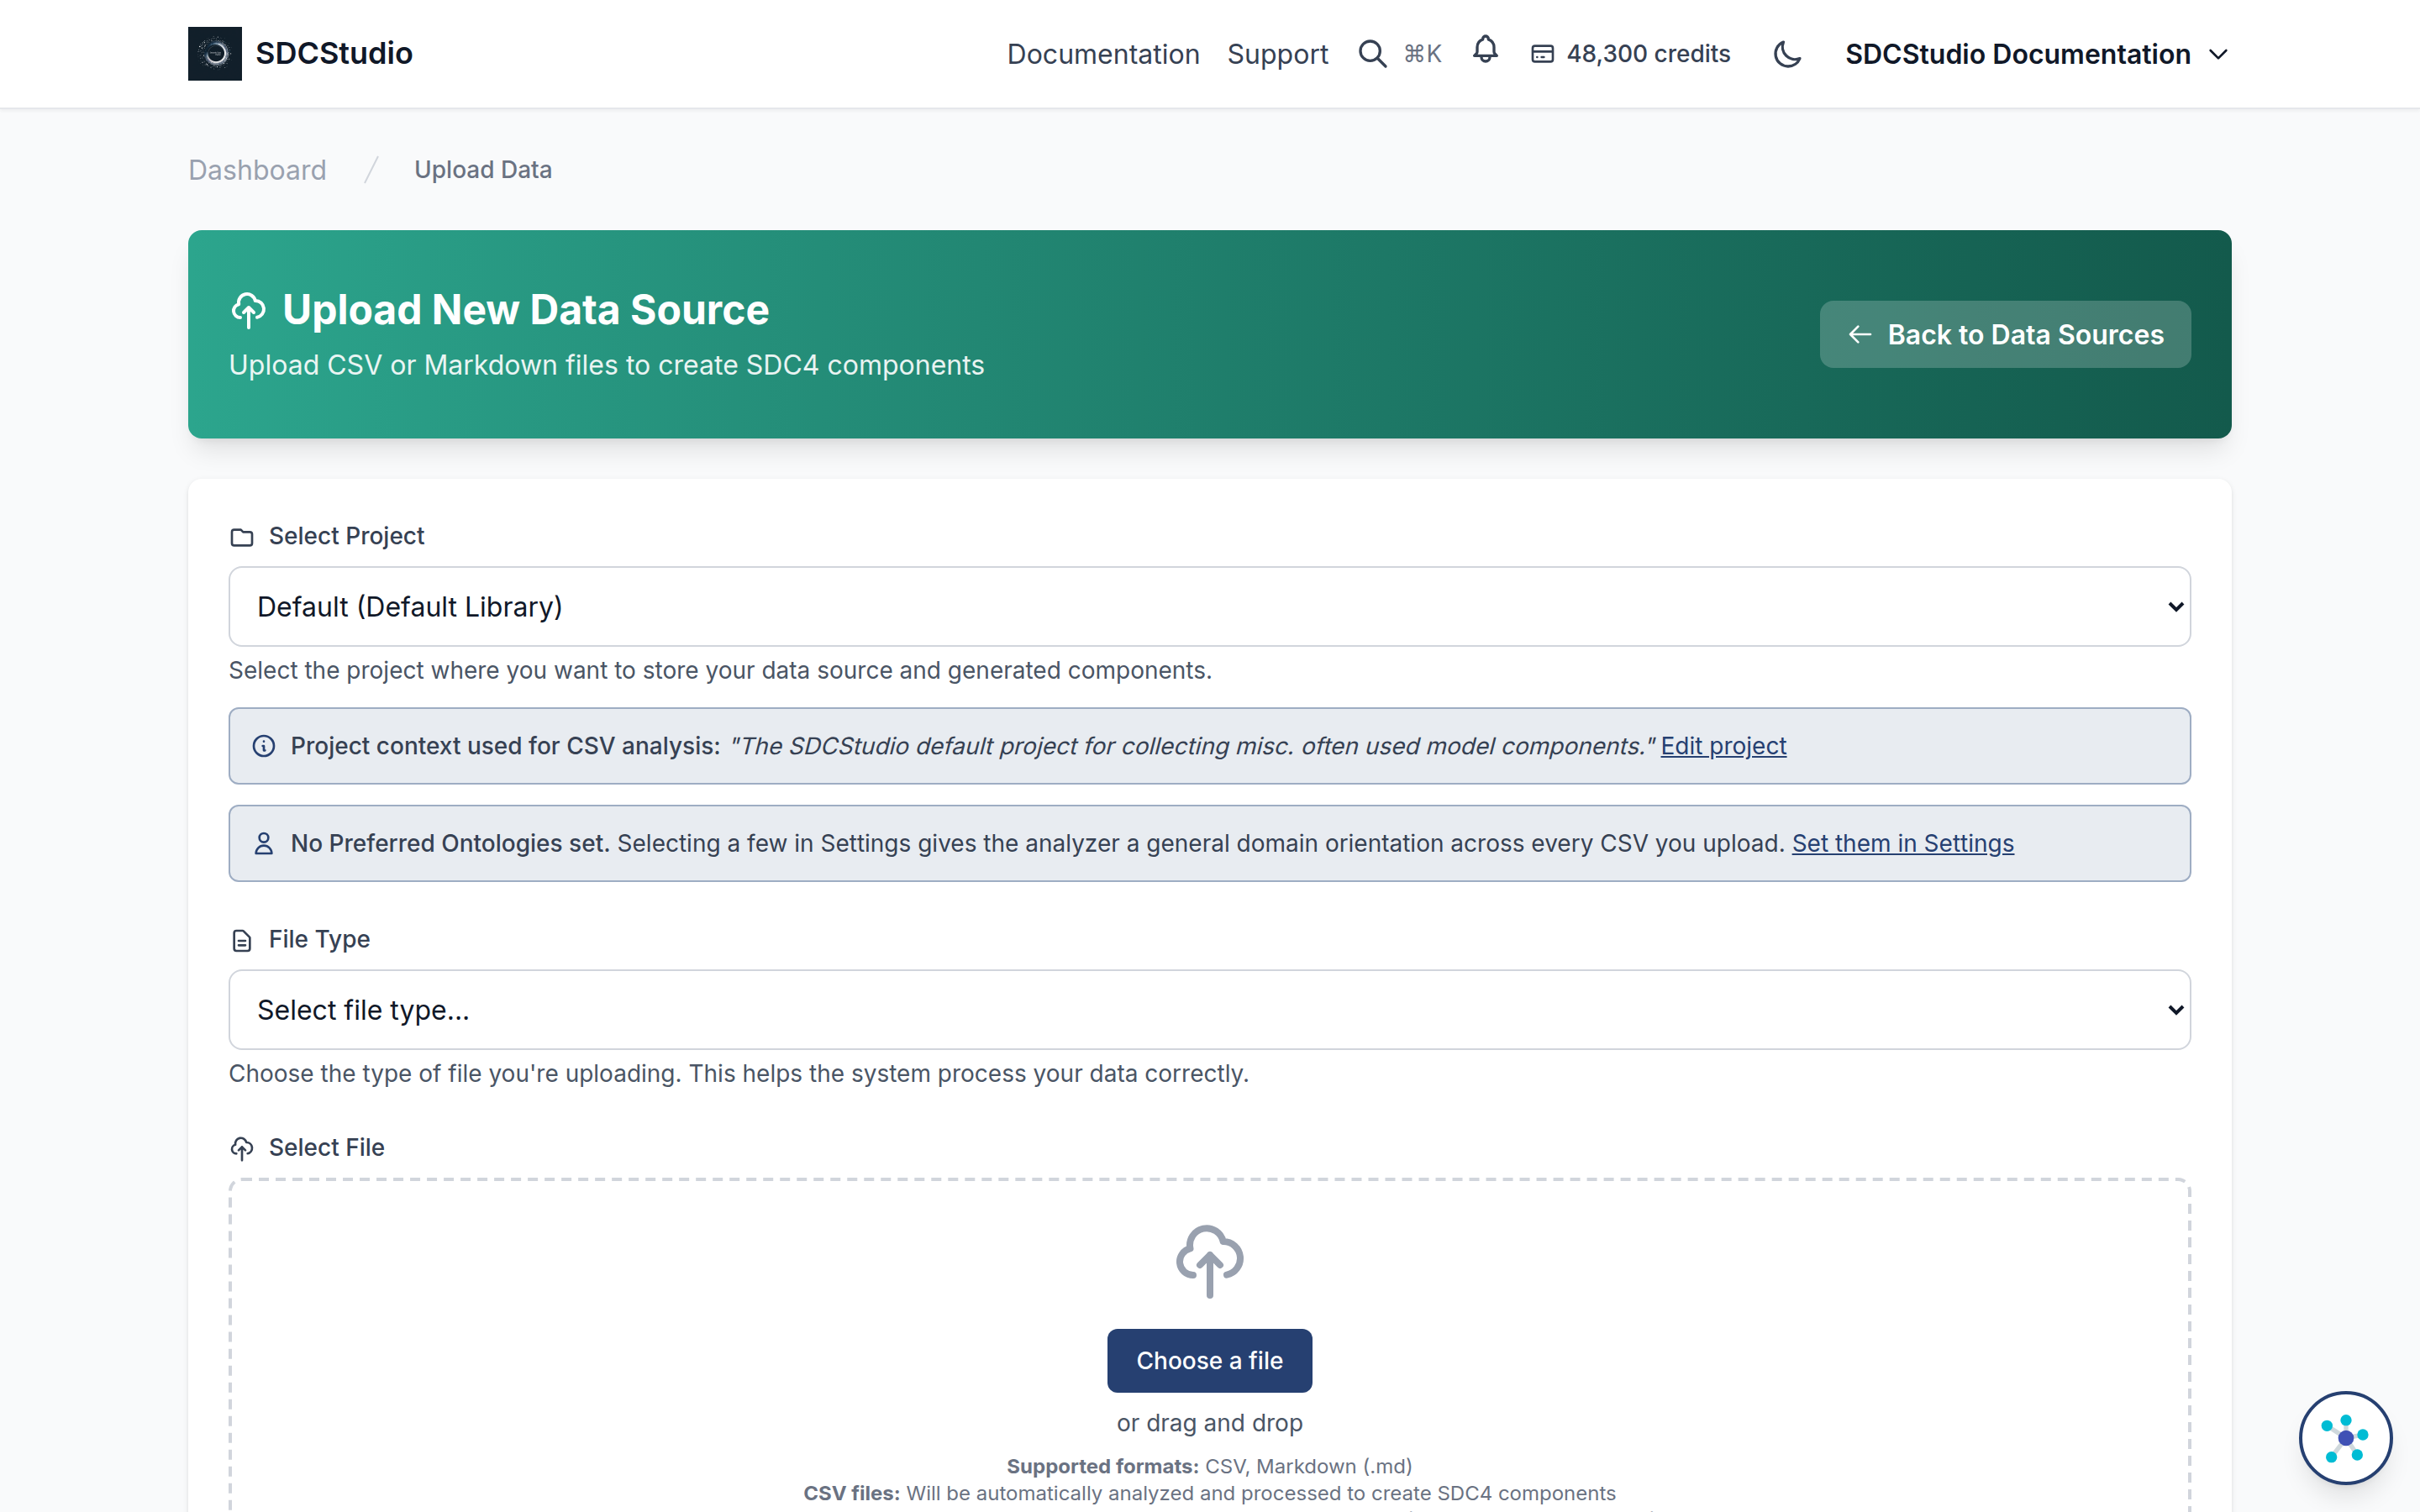
Open Data Sources from the navigation (/app/data-sources) and click Upload New Data, or go to /app/upload directly. The page has three controls and a button.
Select Project. The list shows the projects you own, most recently updated first. The server accepts uploads only into projects you own; choosing a shared or library project returns Invalid project selected. Below the selector a banner shows the first 140 characters of the chosen project's description, which is sent to the analysis as domain context, or asks you to add one if the project has none. A second banner lists your Preferred Ontologies from Settings, or tells you none are set. Both are inputs to the analysis; see AI Processing for how they are used.
File Type. CSV or Markdown. The server decides by extension regardless of this choice, so pick the one that matches the file.
Select File. Click Choose a file or drop a file on the dashed area. As soon as a file is selected the page reads it and runs a check in the browser:
- For CSV: the file must have a non-empty first line. Rows among the first ten whose comma count differs from the header produce a warning, not an error.
- For Markdown: the file must start with YAML front matter containing
template_versionwith major version 4,dataset.nameanddataset.description. A template with no body after the front matter gets a warning.
Errors block the upload; warnings do not. A green File validation passed message means you can continue.
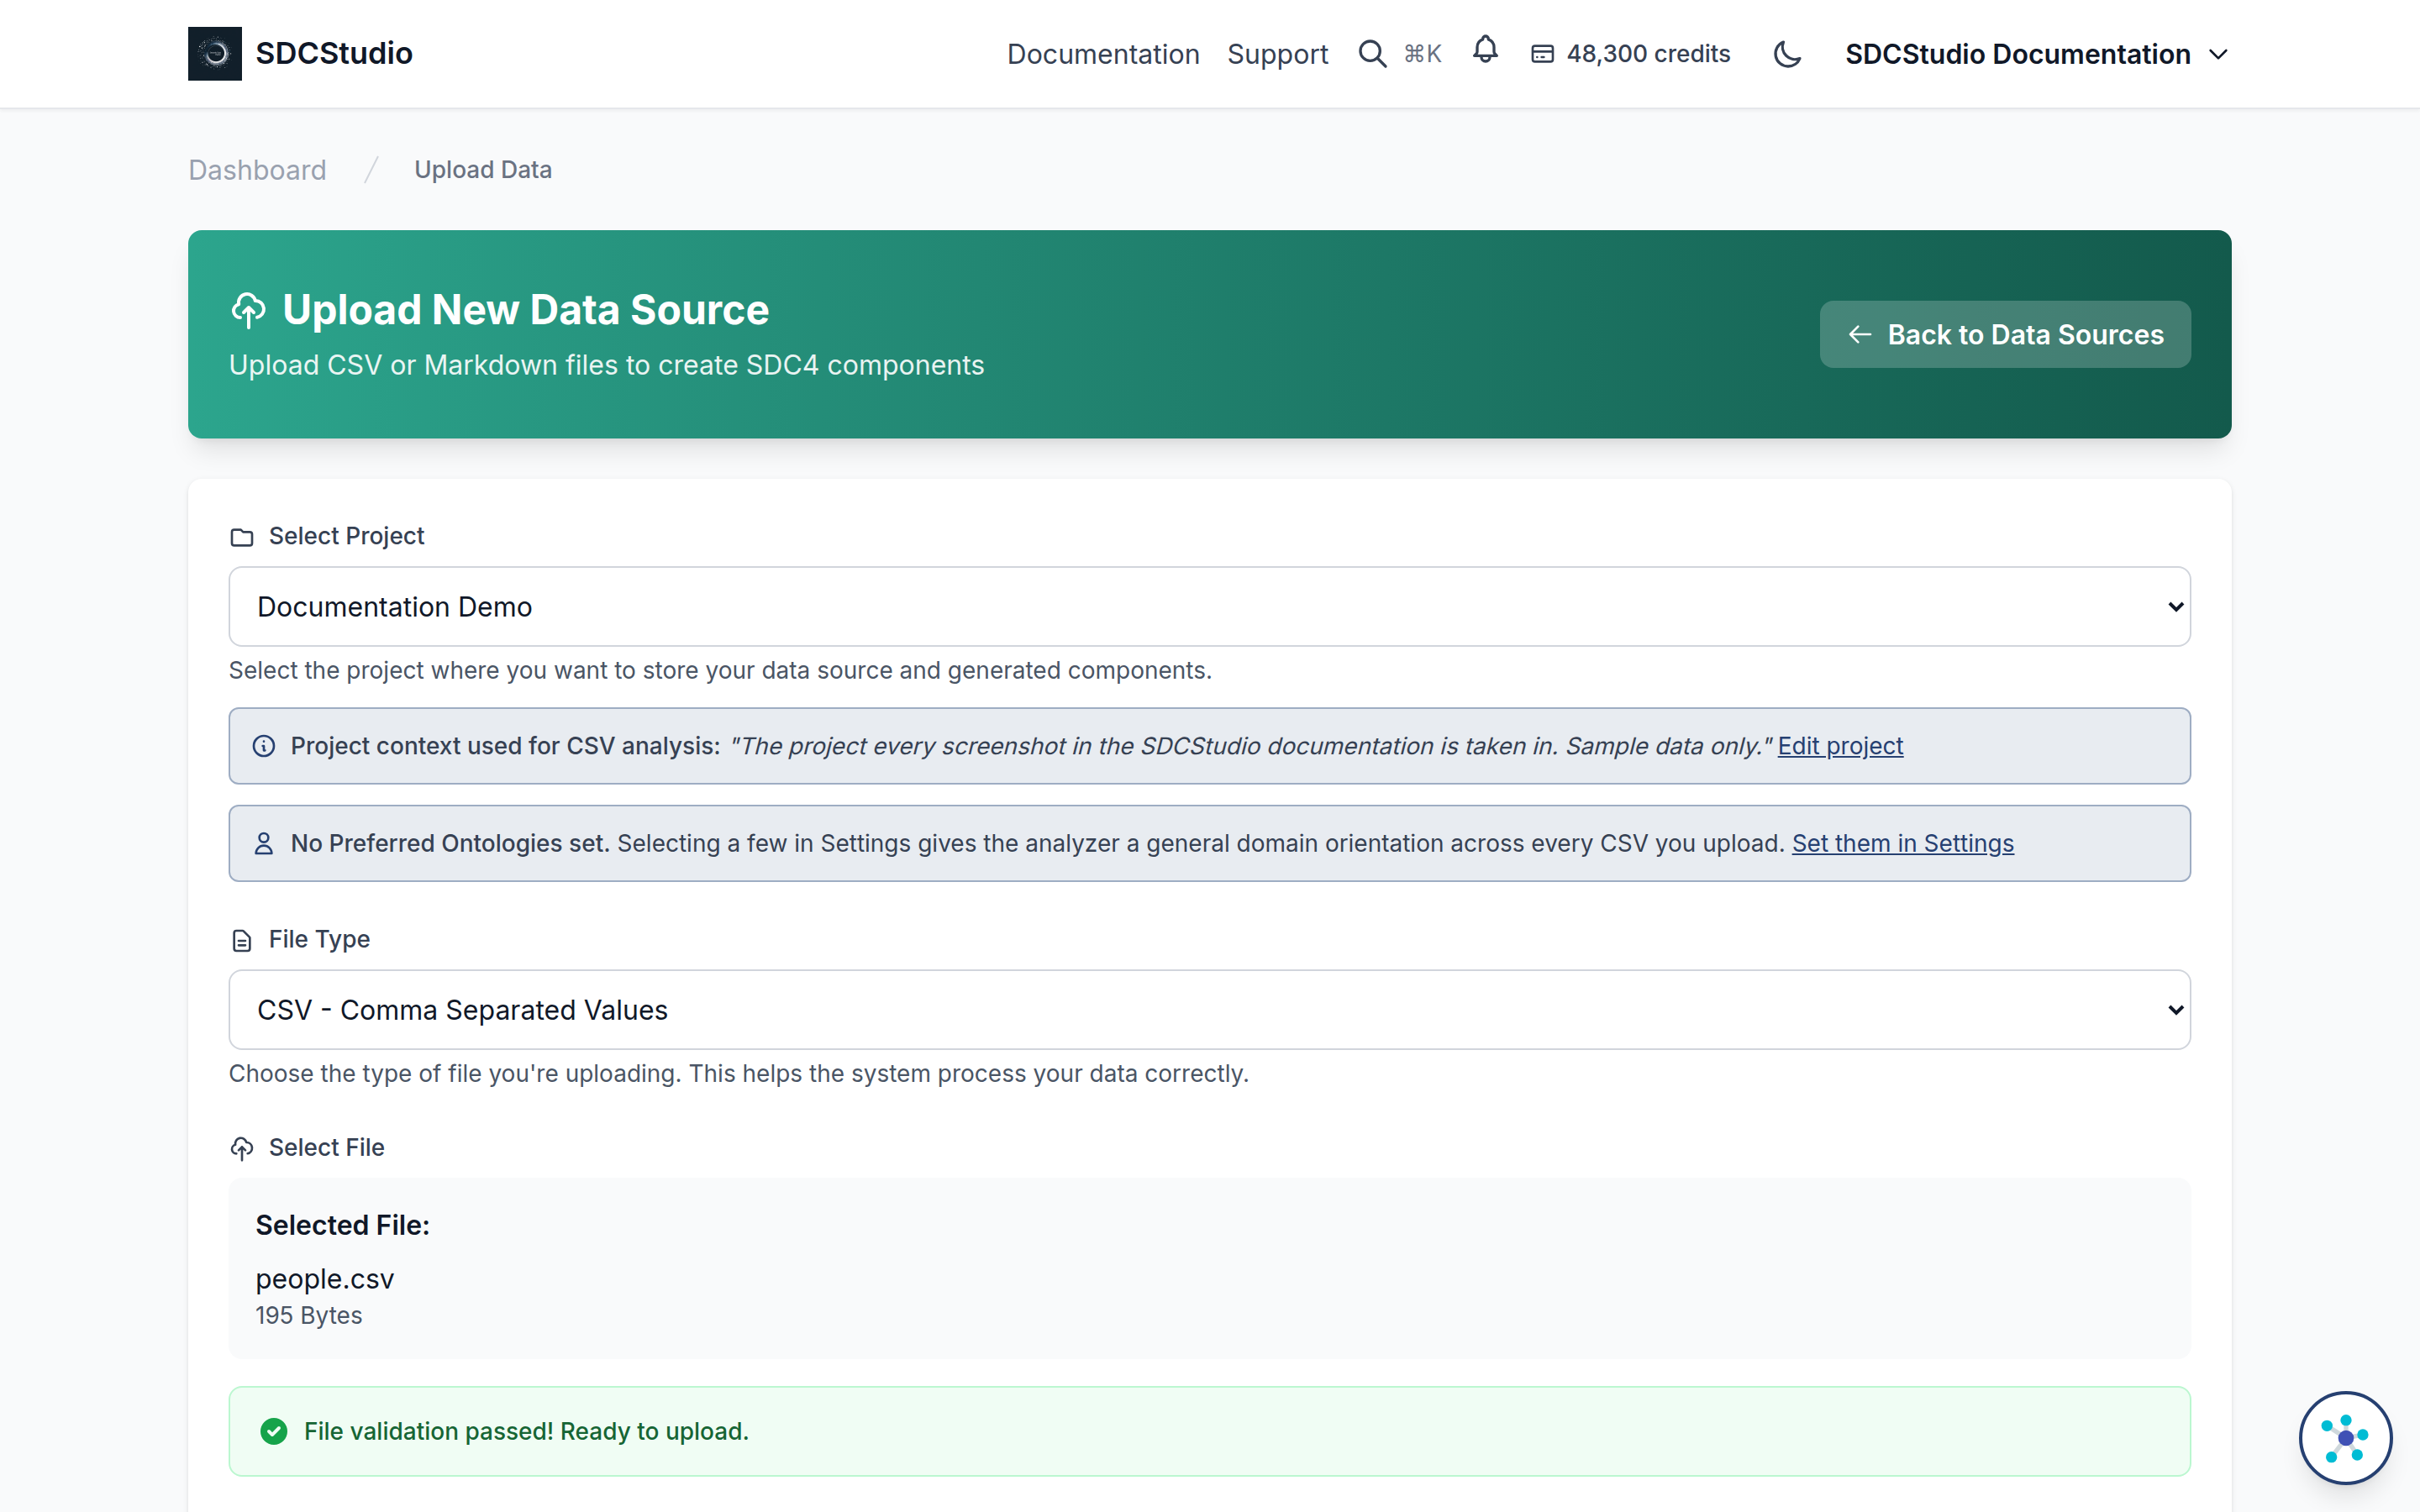
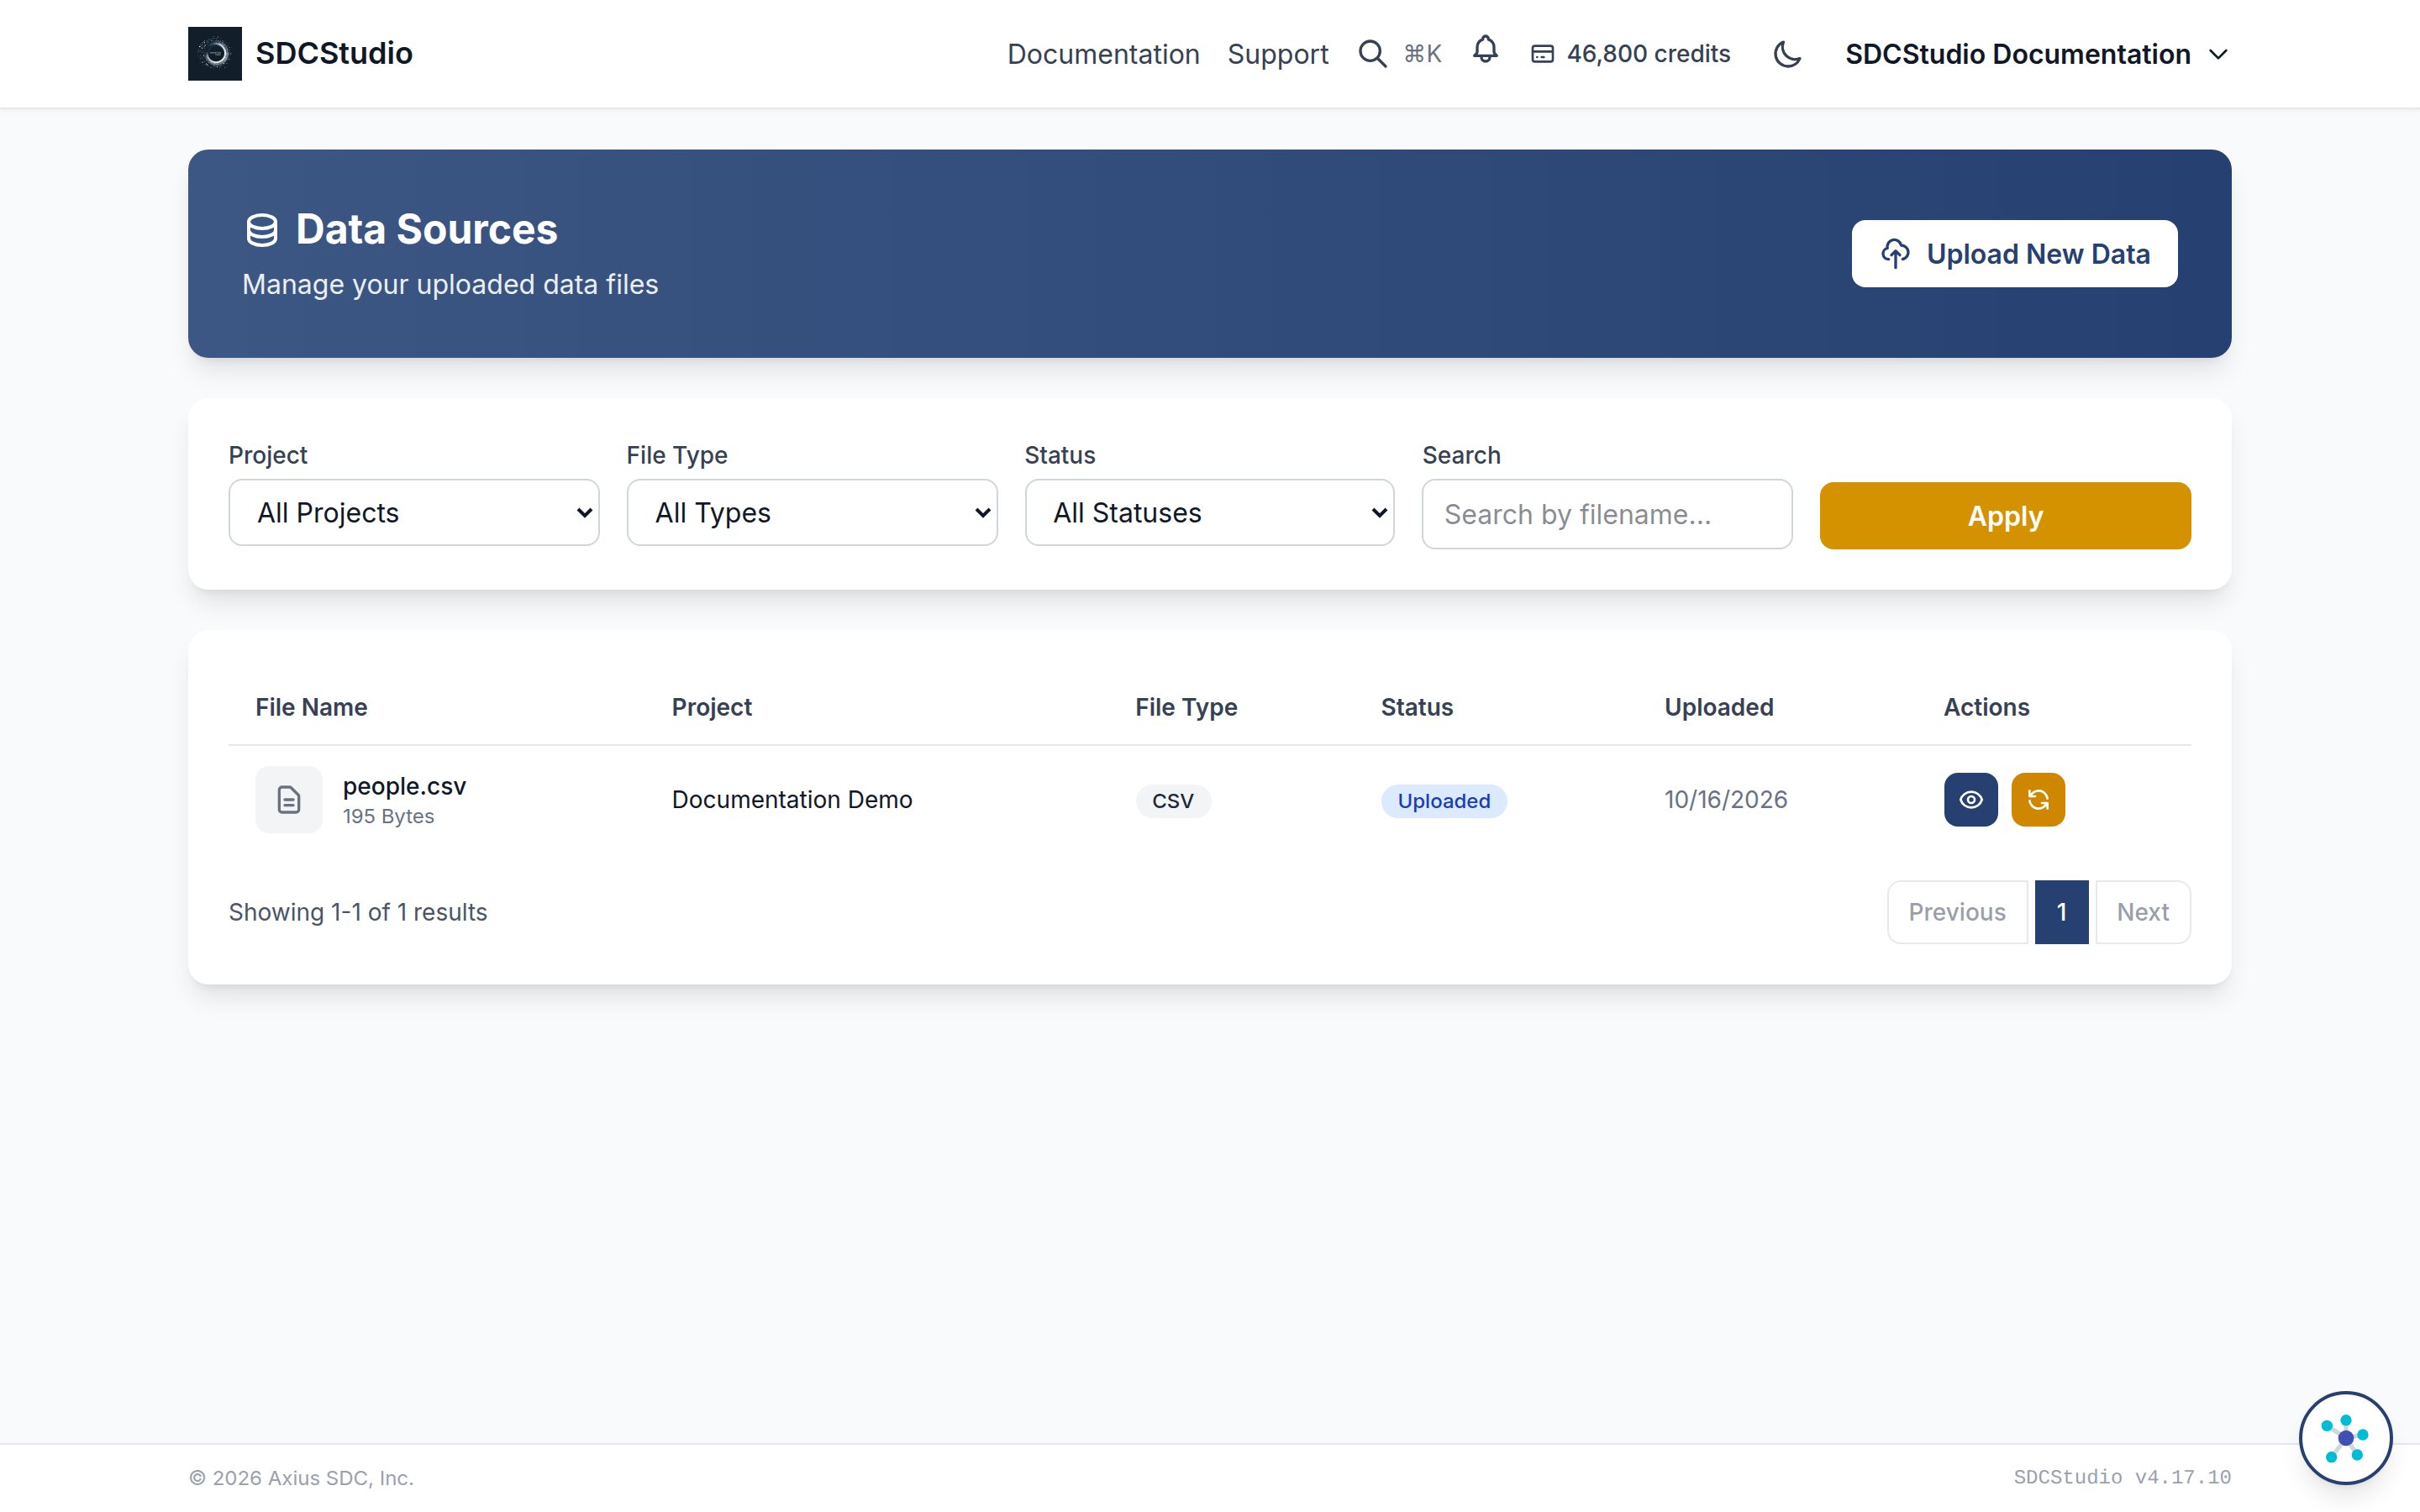
Upload File. The button is disabled until a project, a file type and a validated file are all set. During the transfer a bar shows upload progress; this is the only live progress indicator in the whole flow. On success the page shows File uploaded successfully and returns you to Data Sources after a moment.
Duplicates
Each project keeps one record per file name. A CSV with the same name as one already in the project is not stored or processed again; the existing record is returned and the page says the file was already uploaded. Markdown files are also matched on content, so an unchanged template under a new name is still a duplicate. To process a changed file, give it a new name.
What happens after upload
Processing runs in two Celery tasks. Nothing further is needed from you, and nothing on the page updates by itself; reload Data Sources to see the current status.
Stage 1: structural parsing. The status moves from uploaded to parsing, then parsed. A CSV goes through the csv2pd parser, which profiles the dataset, analyzes every column in parallel, and groups all columns into a single cluster. A Markdown template goes through the md2pd parser, which reads and validates the template, then optionally enriches sparse columns. The parsed description is cached for the next stage. If this stage fails the status becomes error and the message is kept with the record.
Stage 2: agent processing. The status moves through agent_processing and modeling to completed. This stage creates the real objects in your project: a component for each column, a cluster that holds them, and a data model titled after the file name for CSV or the dataset.name for a template. If a model with that title already exists in the project the new one gets a numeric suffix such as (2). A failure here sets agent_error. Everything the run creates is a draft, and every new component is private until you make it public.
A second run for the same file is skipped while one is in progress: parsing holds a lock for 15 minutes and agent processing for 30.
Uploading through the API
POST /api/v1/uploader/api/data-sources/, multipart, with uploaded_file (the CSV or .md file) and project (the project's ct_id), authenticated by a session or Authorization: Token sdcs_.... Processing starts as it does from the page. A key needs Spend, since processing mints components, and is refused with 403 key_scope before anything is stored; the run's charge counts against the key's spending limit (see API Keys). Every upload, from the page or the API, has a job: GET /api/v1/jobs/?data_source=<ct_id> finds it, and it reads completed when processing has finished (see the assembly reference). To build a model from components you name rather than from a file, use the assembly API instead.
Cost
Before stage 1 starts, your balance must cover at least one component, 100 credits; otherwise the status is error with an Insufficient credits message. Before stage 2 creates anything it counts the columns and clusters that will be new and checks your balance against the total; if it is short, the status is error and nothing is created.
Cost: 100 credits for each new component and each new cluster the upload creates, taken when processing completes. Columns matched to existing components are free, and nothing is charged if processing fails. A column is matched when a template names a component with ReuseComponent or carries an existing ct_id, or when a component with the same label and type already exists in the project; the charge is for the components the run created, never more than the estimate the balance check quoted. See Wallet and Billing for balances, purchases and the transaction history.
Status reference
The Data Sources table shows each status by its label; the value is what the API returns.
| Value | Label | Badge color | Meaning |
|---|---|---|---|
uploaded |
Uploaded | Blue | The file is stored and the first task is queued |
parsing |
Parsing | Yellow | Stage 1 is reading the file |
parsed |
Parsed | Orange | Stage 1 finished; stage 2 is queued |
agent_processing |
Agent Processing | Orange | Stage 2 is loading the parsed data and checking the cost |
modeling |
Modeling | Purple | Stage 2 is creating components, the cluster and the model |
completed |
Completed | Green | The data model exists in your project |
error |
Error | Red | Stage 1 failed, or the wallet check failed |
agent_error |
Agent Error | Red | Stage 2 failed after parsing succeeded |
Timing depends on the number of columns and on the language model's response time, since every column takes several model calls.
The Data Sources page
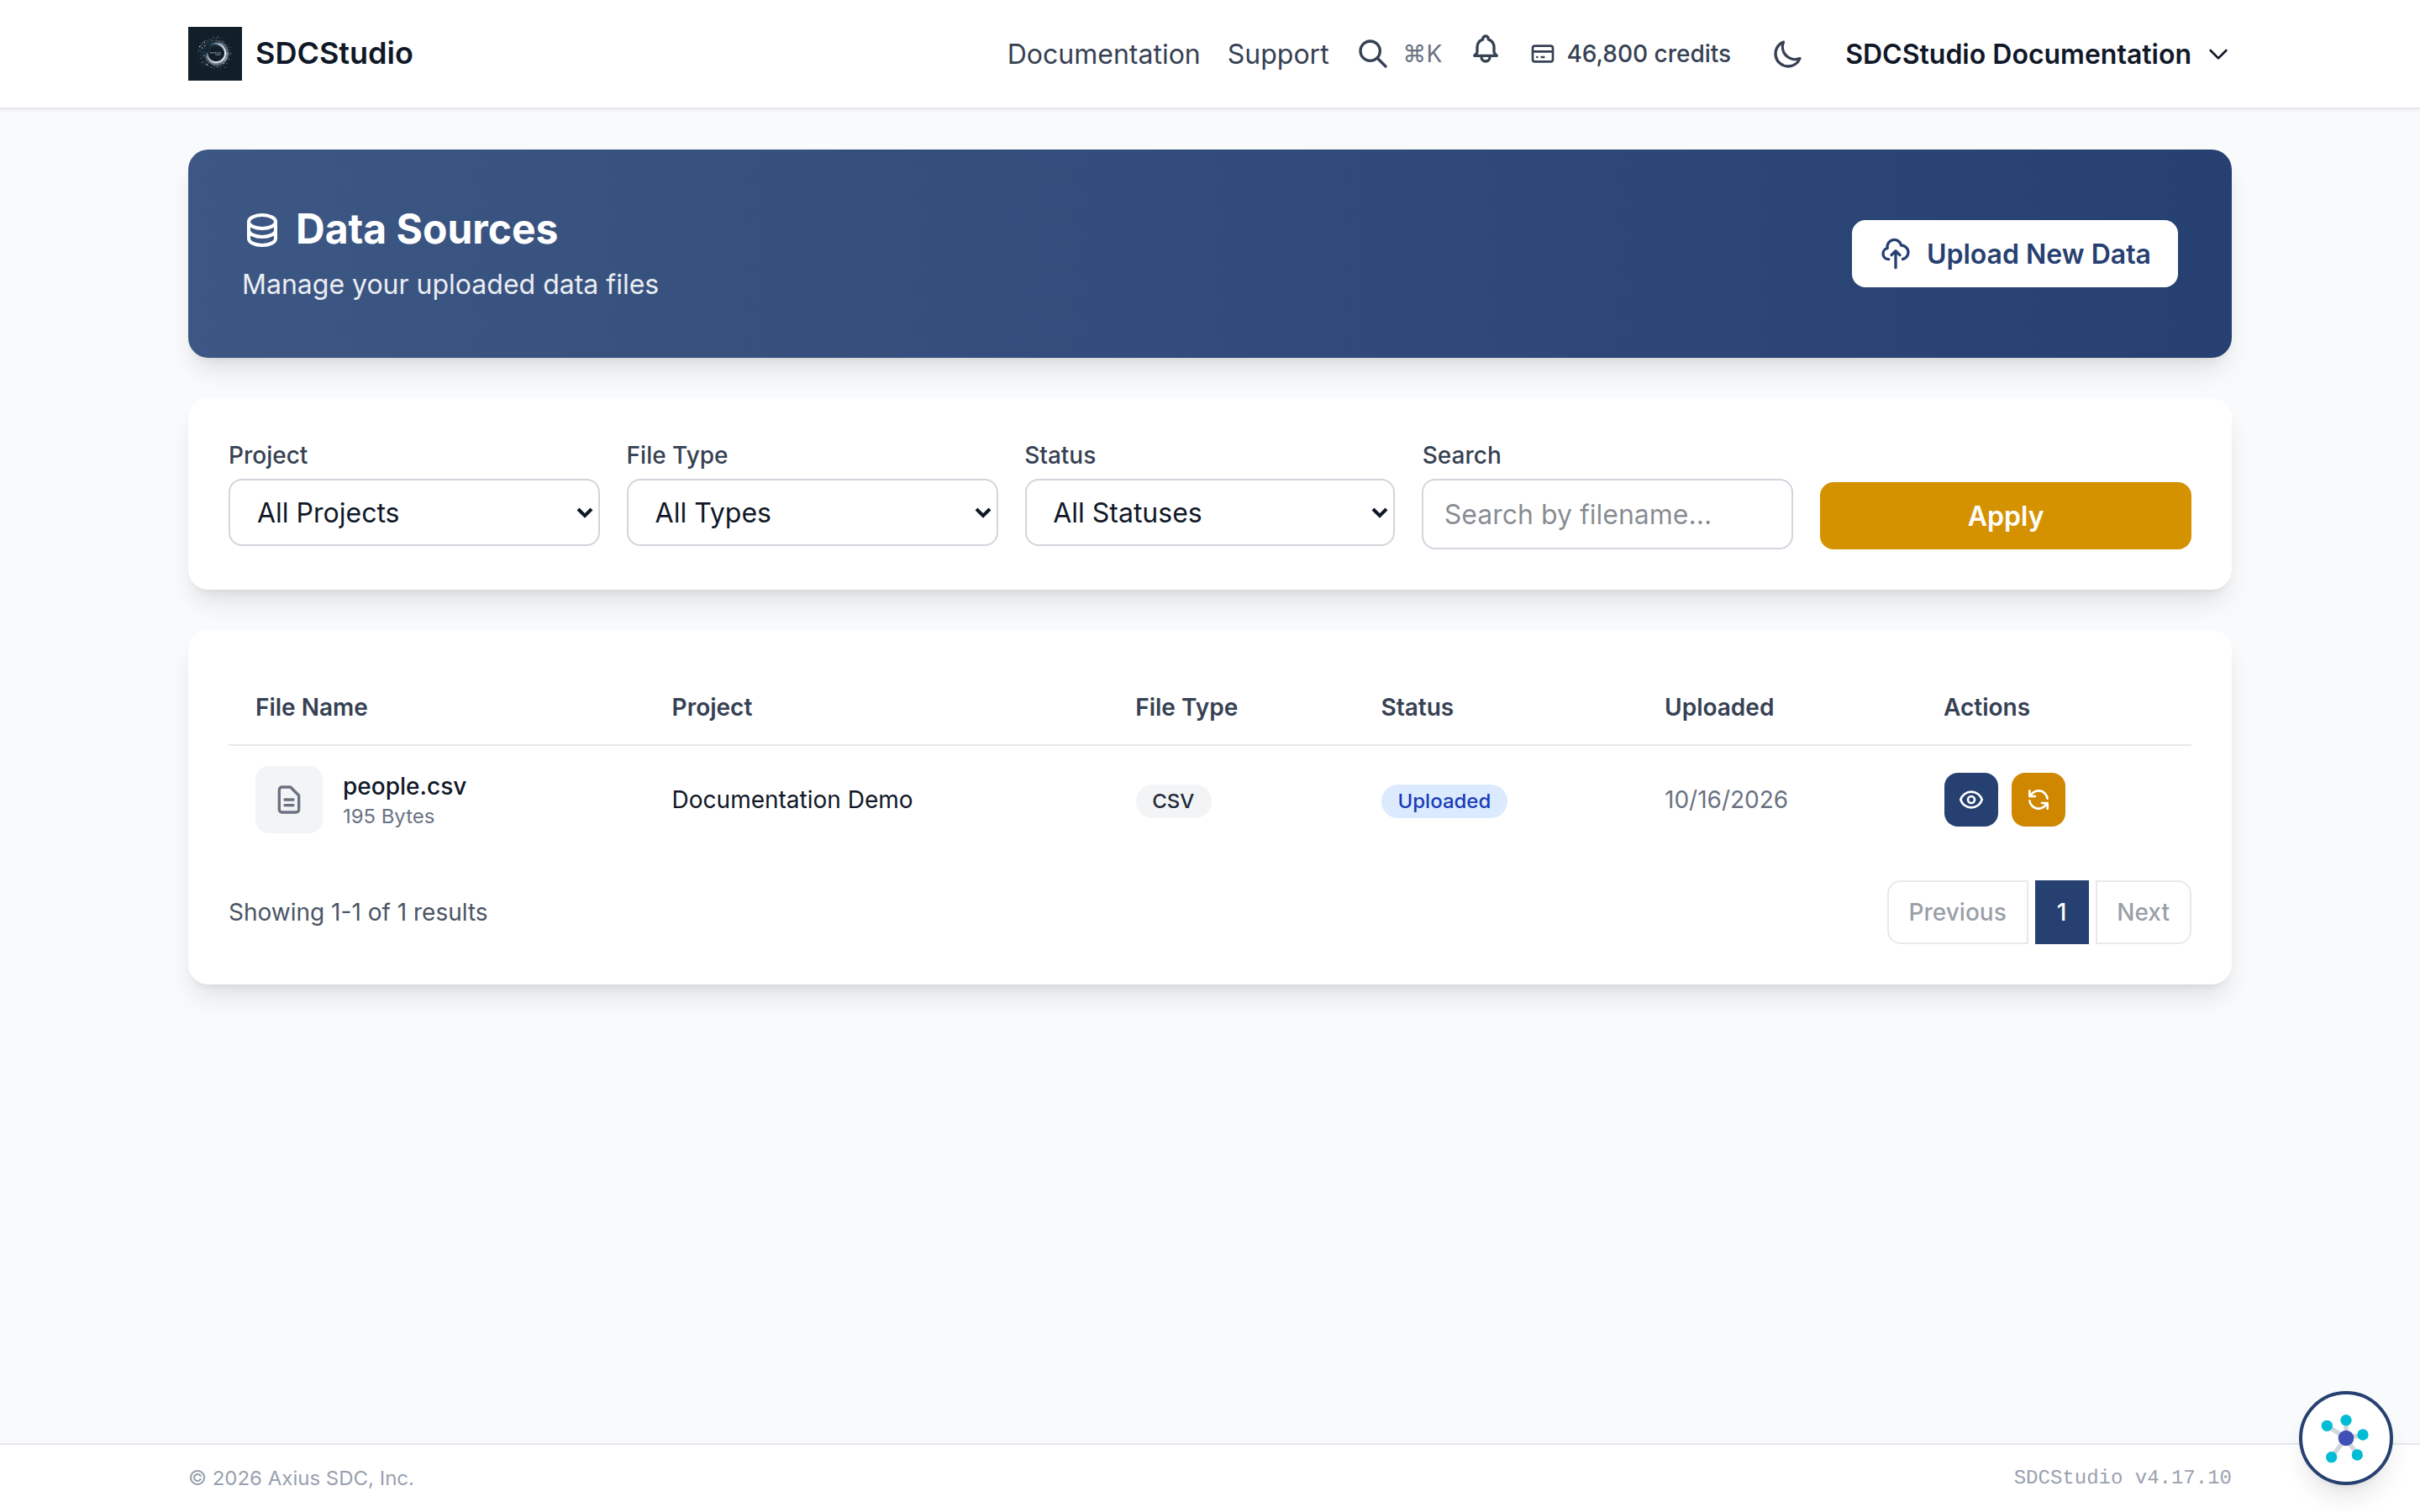
The page lists every upload in projects you own or belong to, ten per page, newest first. It has filters by project, file type, status and file name. Each row shows the file name and size, project, file type, status badge and upload date, and up to two actions:
- View Details opens a panel with the file information, the status, the error message with its phase and time when there is one, parsing durations, and the task identifiers useful when reporting a problem.
- Trigger Processing on an
uploadedrow starts the first stage; Retry Processing on anagent_errorrow runs the agent stage again on the parsed data, without re-uploading or re-parsing. Both show a message above the table and reload the list. Rows in any other status have neither button. - View Details on a
completedrow also has a Generated Data Model section with a View Data Model:</strong> link to the model.</li> <li><strong>Review Metadata</strong> on a <code>completed</code> row opens a server-rendered page listing the columns the parser found.</li> </ul> <p>The page does not refresh itself. Reload it to see a status change.</p> <h2 id="after-processing-completes">After processing completes</h2> <p>The new data model is in your project, in draft, under the title described above; open it from <strong>View Details</strong>, <strong>View Data Model</strong>, or find it on the Models page. Each component is labeled with its column name. Where a component with the same label and type already existed in the project it was reused rather than created again; where one with the same label but a different type existed, the new one carries the suffix <code>(duplicate label)</code> so you notice it.</p> <p>Review the model before publishing. Types, constraints, units and semantic links were inferred from column names, five sample values and your project description, and the draft is yours to correct. See <a href="data-modeling.html">Data Modeling</a> for editing, <a href="semantic-enhancement.html">Semantic Enhancement</a> for the ontology links, and <a href="generating-outputs.html">Generating Outputs</a> for what a published model produces.</p> <h2 id="when-something-goes-wrong">When something goes wrong</h2> <p><strong>The upload itself fails.</strong> The page shows the server's message: <code>No file provided</code>, <code>No project selected</code>, <code>Invalid project selected</code>, <code>Unsupported file type</code>, or the exception text when storing the file failed. Fix the cause and upload again.</p> <p><strong>Status <code>error</code>.</strong> Open View Details and read the message. <code>Insufficient credits</code> names the shortfall; add credits first. A parser message points at the file: a malformed row or unreadable encoding in a CSV, or a template that fails validation. Fix the file and upload it under a new name.</p> <p><strong>Status <code>agent_error</code>.</strong> Parsing succeeded but creating the model failed. The message in View Details usually names the component or the step; a <code>ReuseComponent</code> reference that resolves to nothing is a common cause. Click <strong>Retry Processing</strong> on the row to run the agent stage again on the parsed data; if the cause is in the file, fix it and upload it under a new name.</p> <p><strong>Status unchanged for longer than the lock window.</strong> Reload first. A run that has outlived its lock has failed without recording an error; upload the file under a new name.</p> <p>More cases are collected in <a href="troubleshooting.html">Troubleshooting</a>.</p> </article> </div> </main> <!-- Footer --> <footer class="bg-[#0a2342] text-white py-12 px-6 md:px-12 mt-20"> <div class="container mx-auto text-center"> <p class="text-sm text-[#e1e6ea]"> © 2026 Axius SDC, Inc. | <a href="/tutorial/" class="hover:text-[#2ca58d] transition">Tutorial</a> | <a href="/docs/" class="hover:text-[#2ca58d] transition">Documentation</a> | <a href="https://sdcstudio.axius-sdc.com" class="hover:text-[#2ca58d] transition">SDCStudio</a> </p> </div> </footer> </body> </html>