SDCStudio Quick Start Guide
Welcome to SDCStudio
SDCStudio is an AI-assisted data modeling platform that helps you create, manage, and generate SDC4-compliant data models and applications. This guide walks you through the web interface, from sign-in to a generated output package.
What You'll Learn
- How to navigate the web interface
- How to configure your Settings and upload ontologies
- How to create your first data model
- How to upload and process data files
- How to generate the output package (XSD schema, XML template, JSON instance, and more)
Prerequisites
- A web browser
- Data files to work with (CSV, or a Markdown dataset template)
- (Optional) Project or domain specific ontologies or vocabularies (.ttl, .owl, .rdf, .n3, or .nt)
Step 1: Access SDCStudio
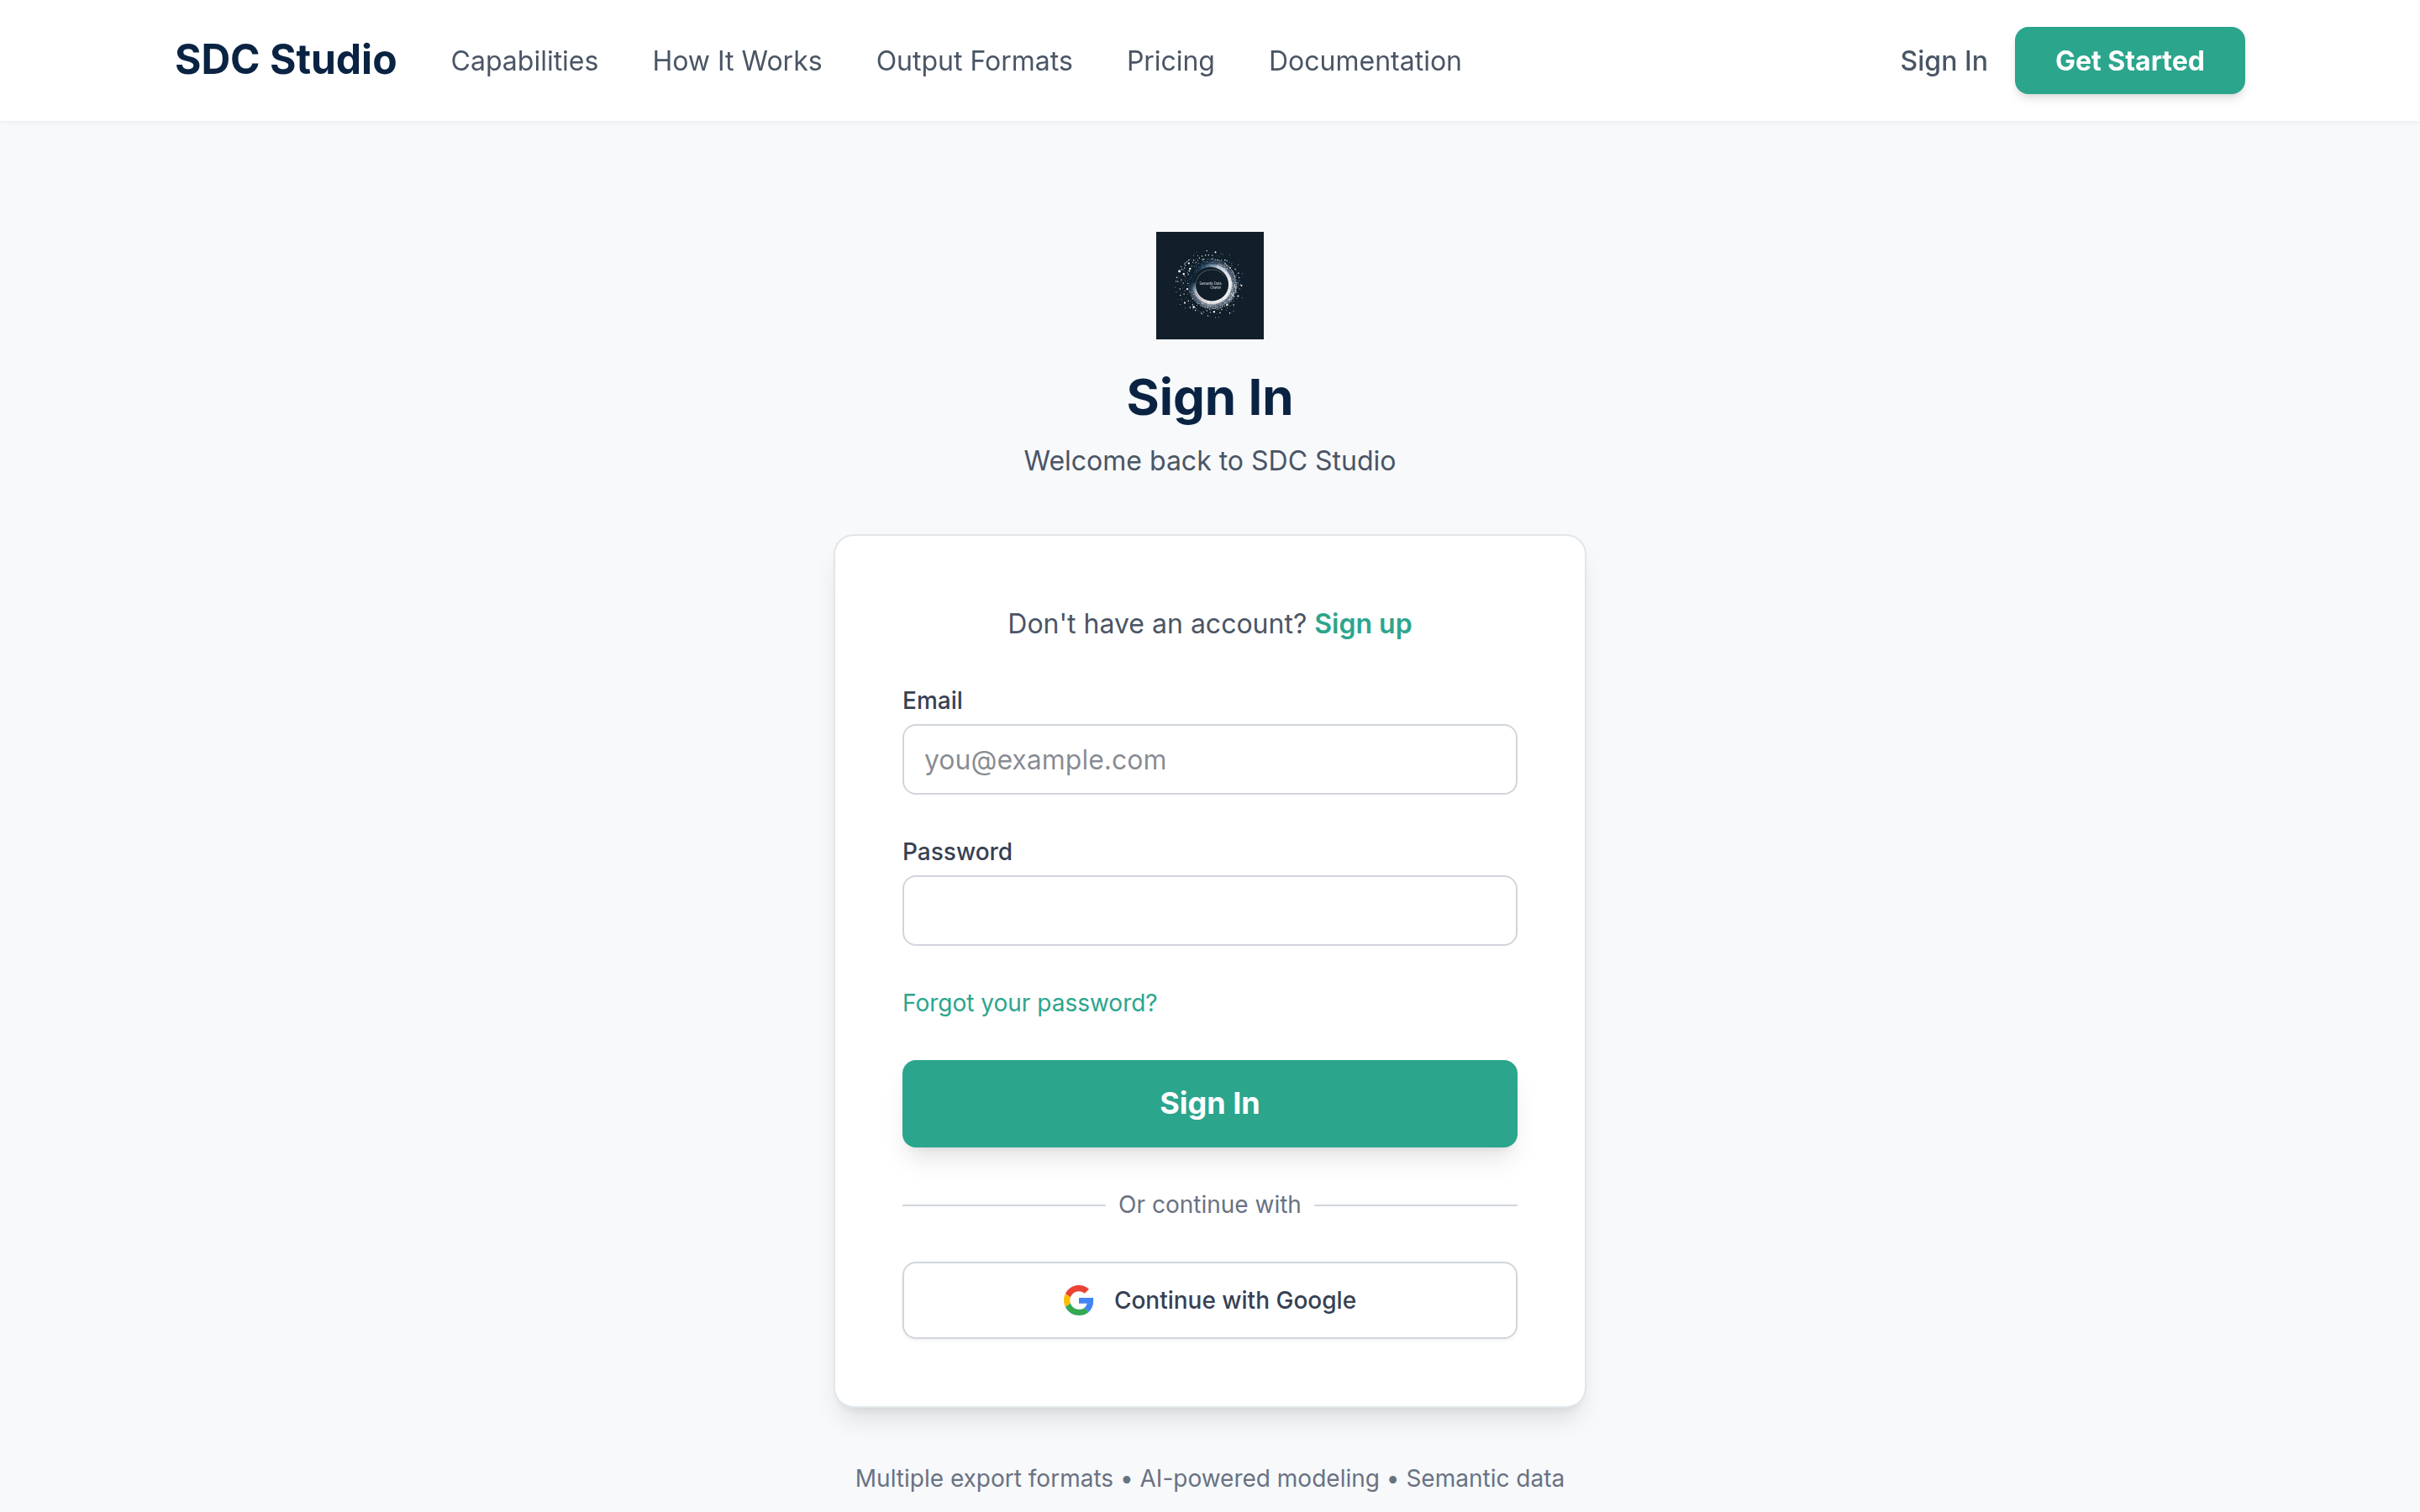
- Open your browser and navigate to https://sdcstudio.axius-sdc.com
- Sign in with your account credentials
- Fund your wallet if prompted. A new account is taken to
/app/welcomeand must fund its wallet before anything else in the app opens: click Fund $10 & Start and pay $10 (10,000 credits) through Stripe; larger packs are sold afterwards in Settings > Wallet. The credits are yours and are spent per operation; nothing is charged by time. The gate applies to accounts created on or after 1 August 2026 and releases for good the first time the wallet holds a positive balance. Until then the rest of the app is not reachable; the public catalog API and the practitioner directory need no account. - You land on your Dashboard, the starting point for everything below
Step 2: Configure Your Settings (Important)
Before creating models, configure your profile and upload any ontologies your domain needs:
Navigate to Settings
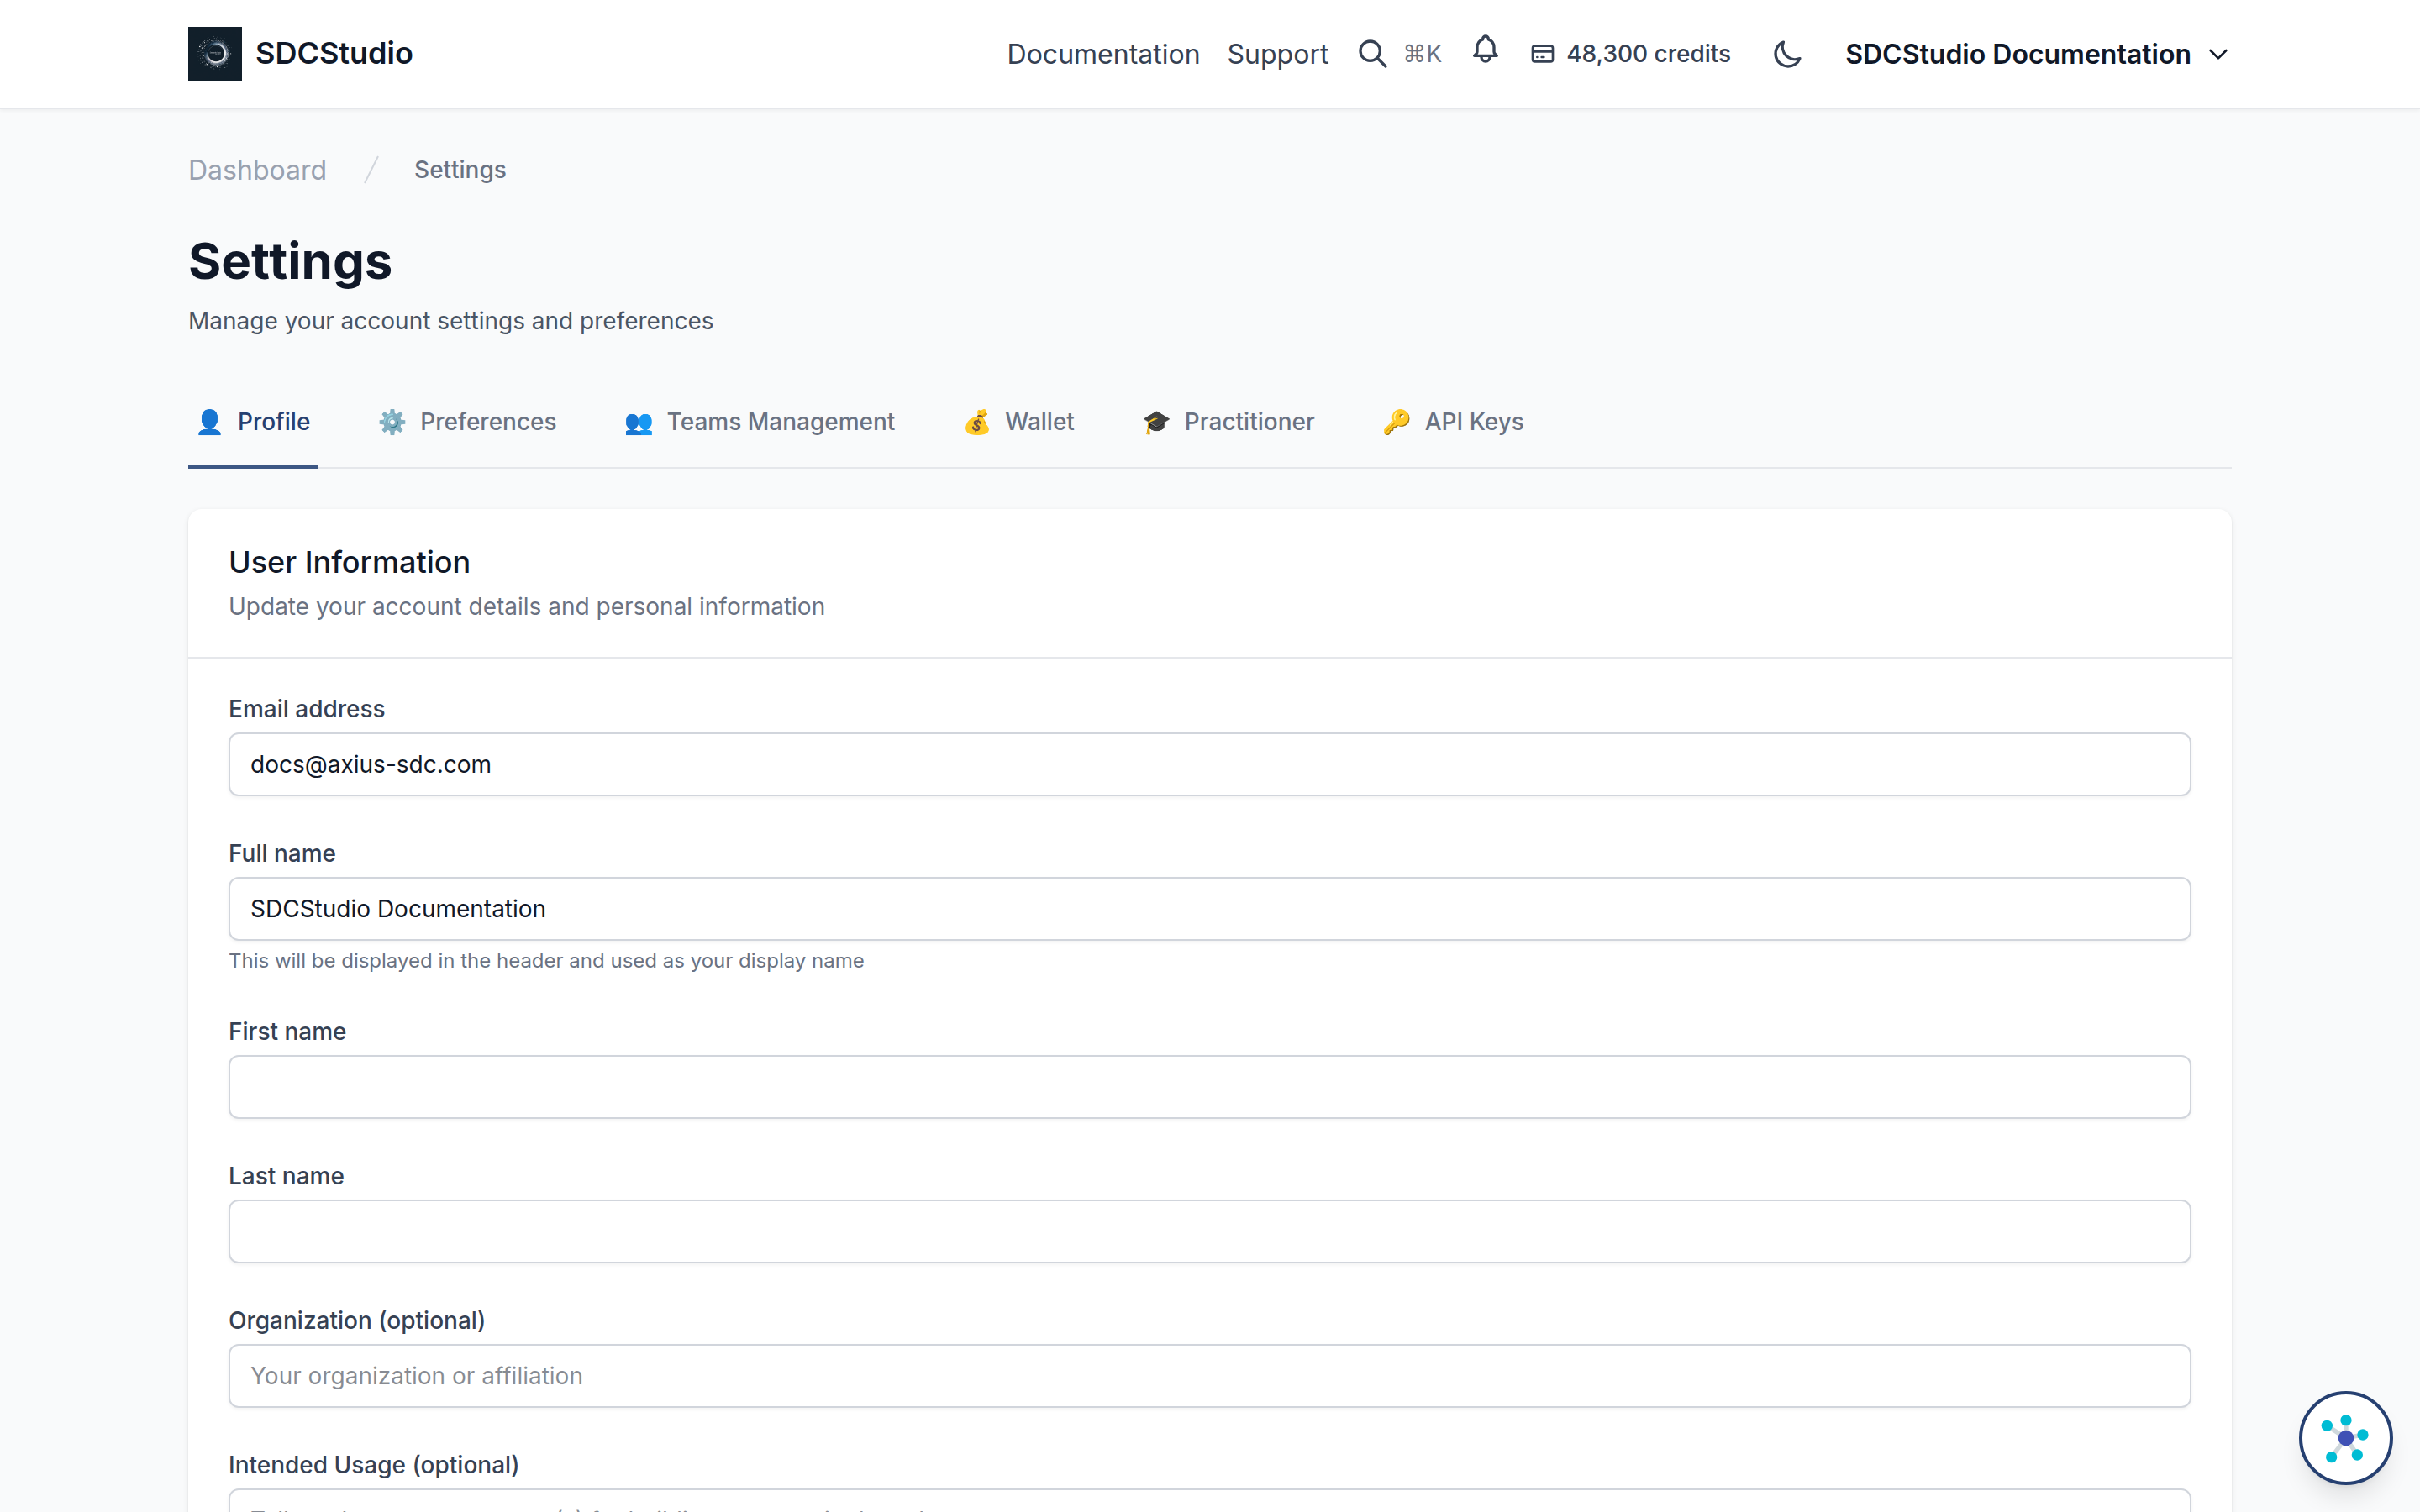
- Open the user menu (top right) and click Settings, or go directly to
/app/settings - You'll see six tabs: Profile, Preferences, Teams Management, Wallet, Practitioner, and API Keys
Upload Project Ontologies (Optional but Recommended)
Why Upload Ontologies? - Improves the agents' understanding of your specific domain - Provides better semantic suggestions - Ensures consistency with your organization's vocabulary - Enhances data model quality
Important Note:
- Ontologies are managed on their own page, /app/ontologies, not inside Settings
- Upload the vocabularies your project uses: your organization's data dictionary, project-specific terminology, or a public ontology your domain relies on
- Ontologies uploaded with a Team, Corporate, or Public access level are visible to others, so choose the access level deliberately
How to Upload:
- Open the Ontologies page: from Settings, open the Preferences tab, scroll to Modeler Information, and click Manage Ontologies; or go directly to
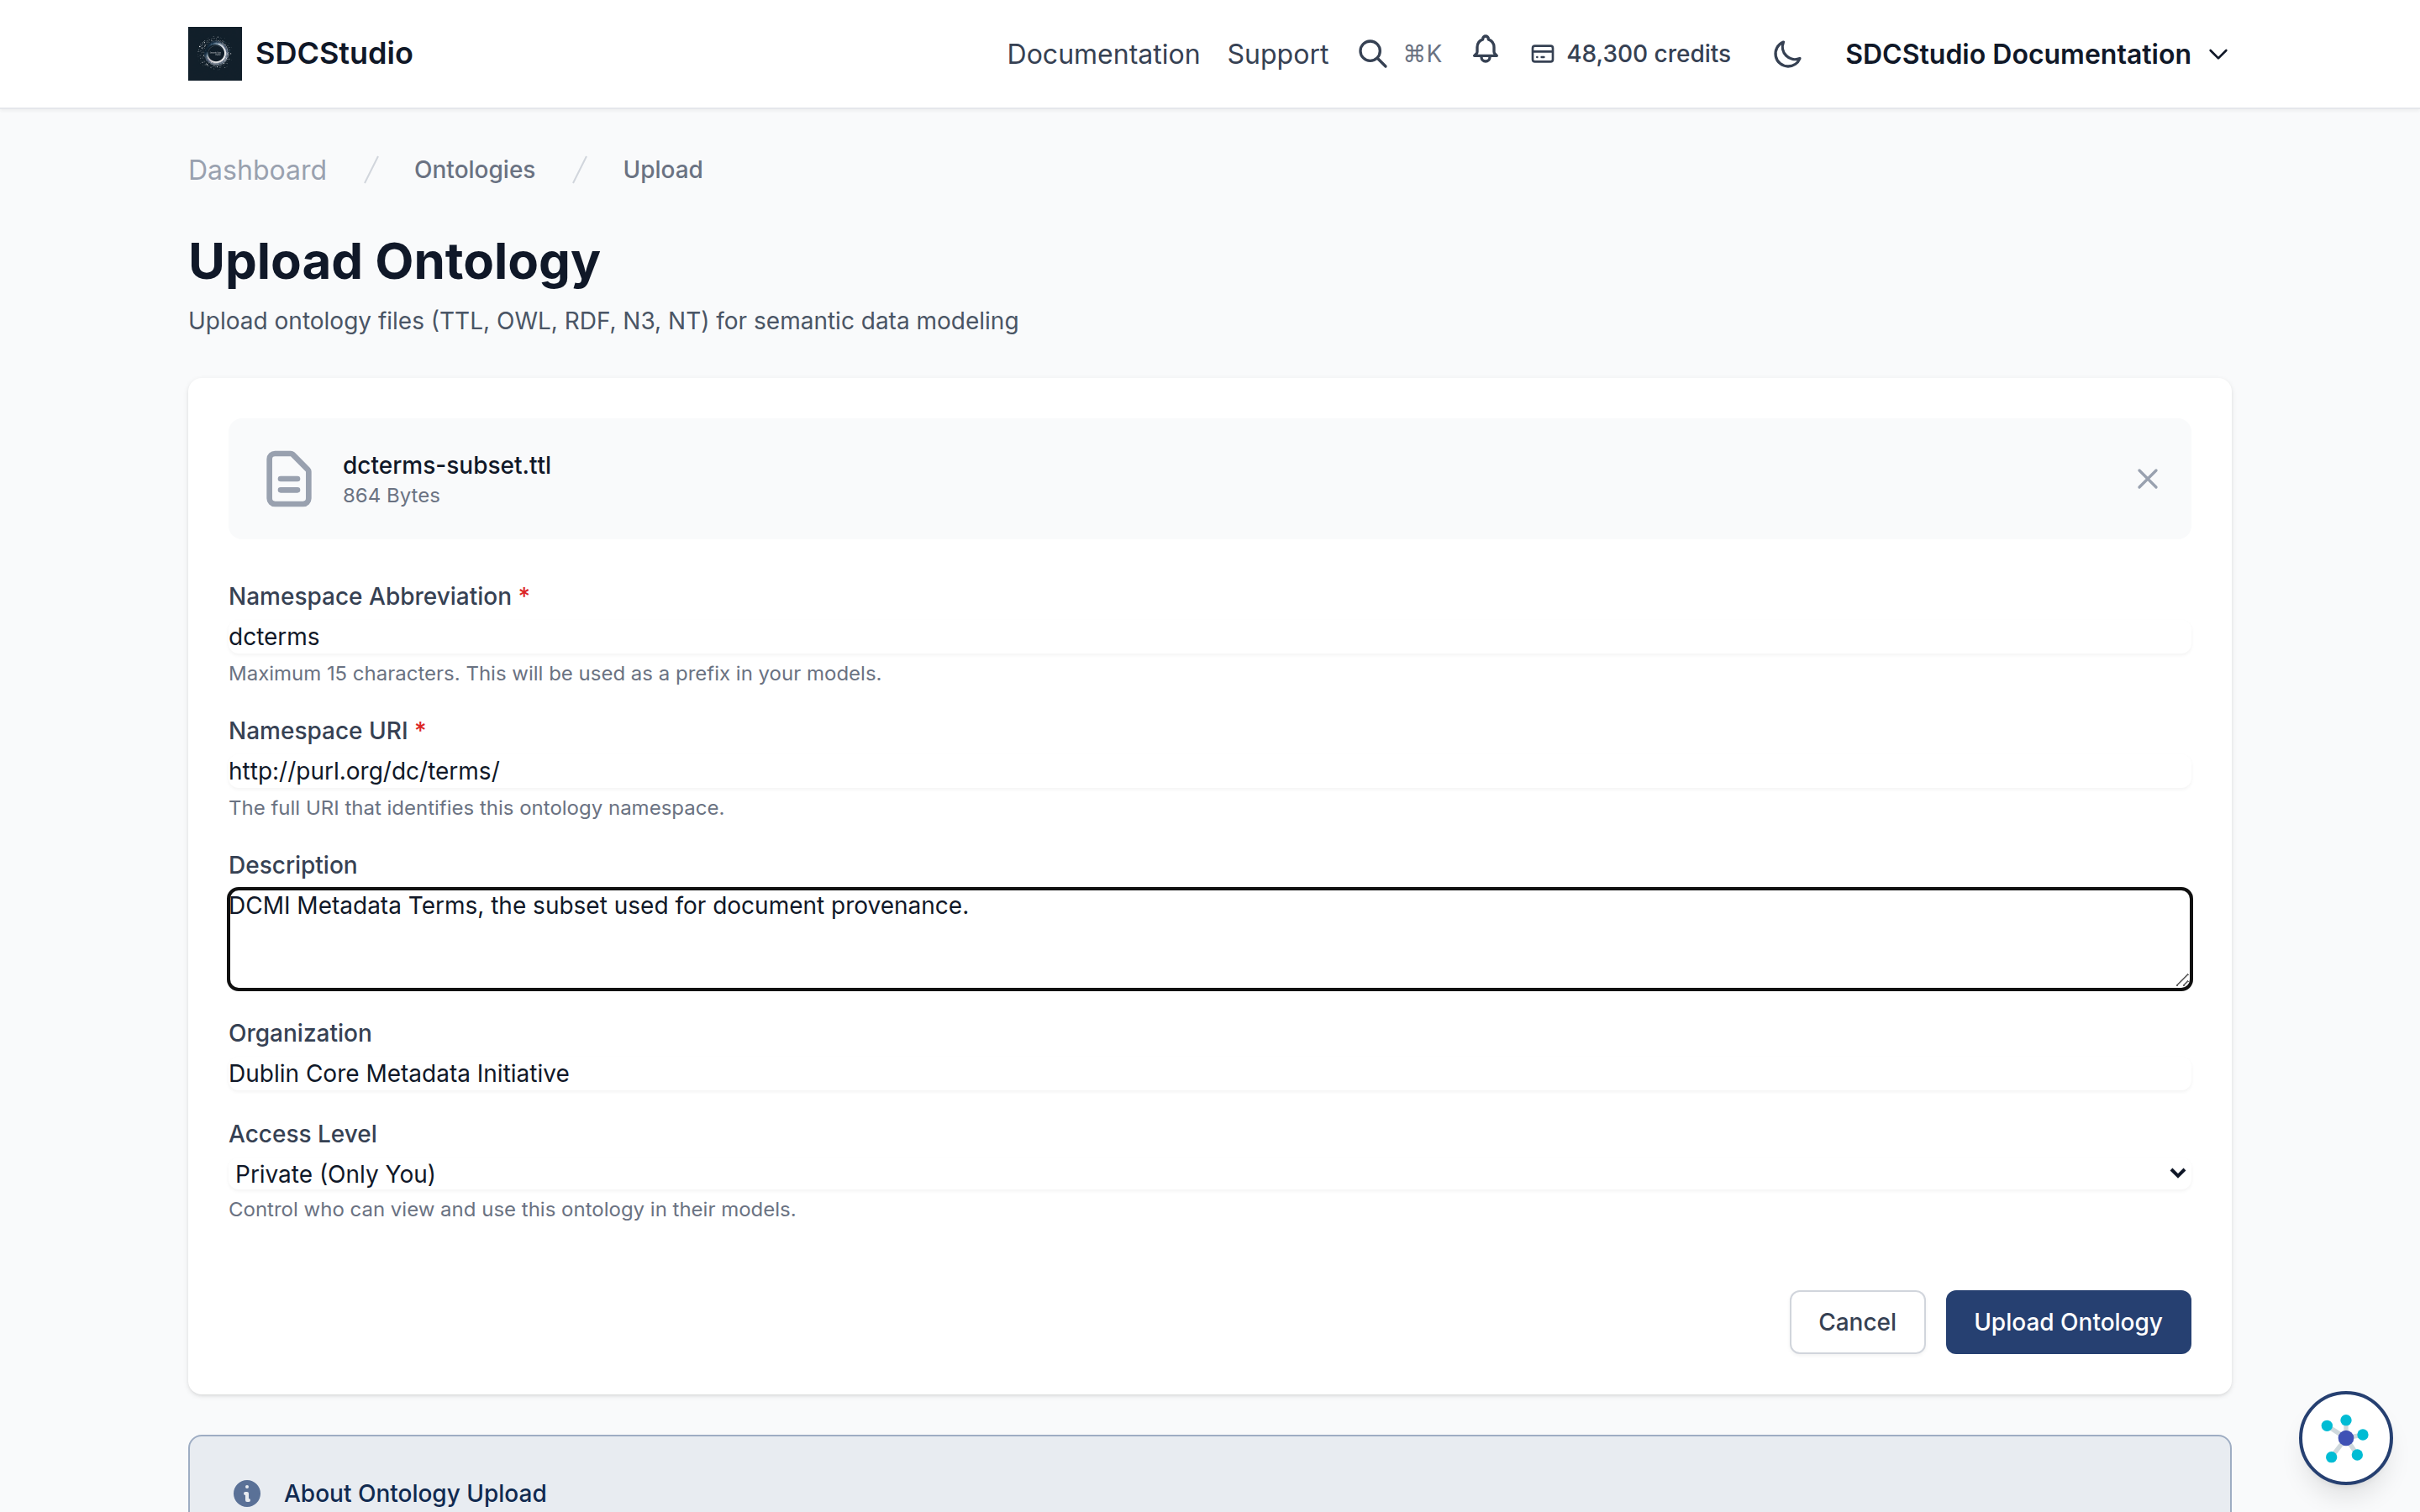
/app/ontologies - Click "Upload Ontology"
- Choose your file: Turtle (.ttl), OWL (.owl), RDF/XML (.rdf), Notation3 (.n3), or N-Triples (.nt), up to 10 MB
- Fill in the form:
- Namespace abbreviation: the prefix used in your models (for example,
foaf), at most 15 characters - Namespace URI: the ontology's namespace (for example,
http://xmlns.com/foaf/0.1/) - Description: purpose and scope
- Organization: who publishes the ontology
- Access Level: Private, Team, Corporate, or Public
- Click "Upload Ontology"
- Back in Settings > Preferences, move the ontology into Selected Ontologies under Preferred Ontologies and click Save Modeler Settings so the agents prioritize it
Your ontologies are now available for semantic enrichment.
Configure Your Profile
- Click the "Profile" tab
- Update your information:
- Full Name, First Name, Last Name
- Organization
- Intended Usage (optional; a short note on how you use SDCStudio)
- Click "Save Changes"
Step 3: Navigate the Interface
Main Navigation
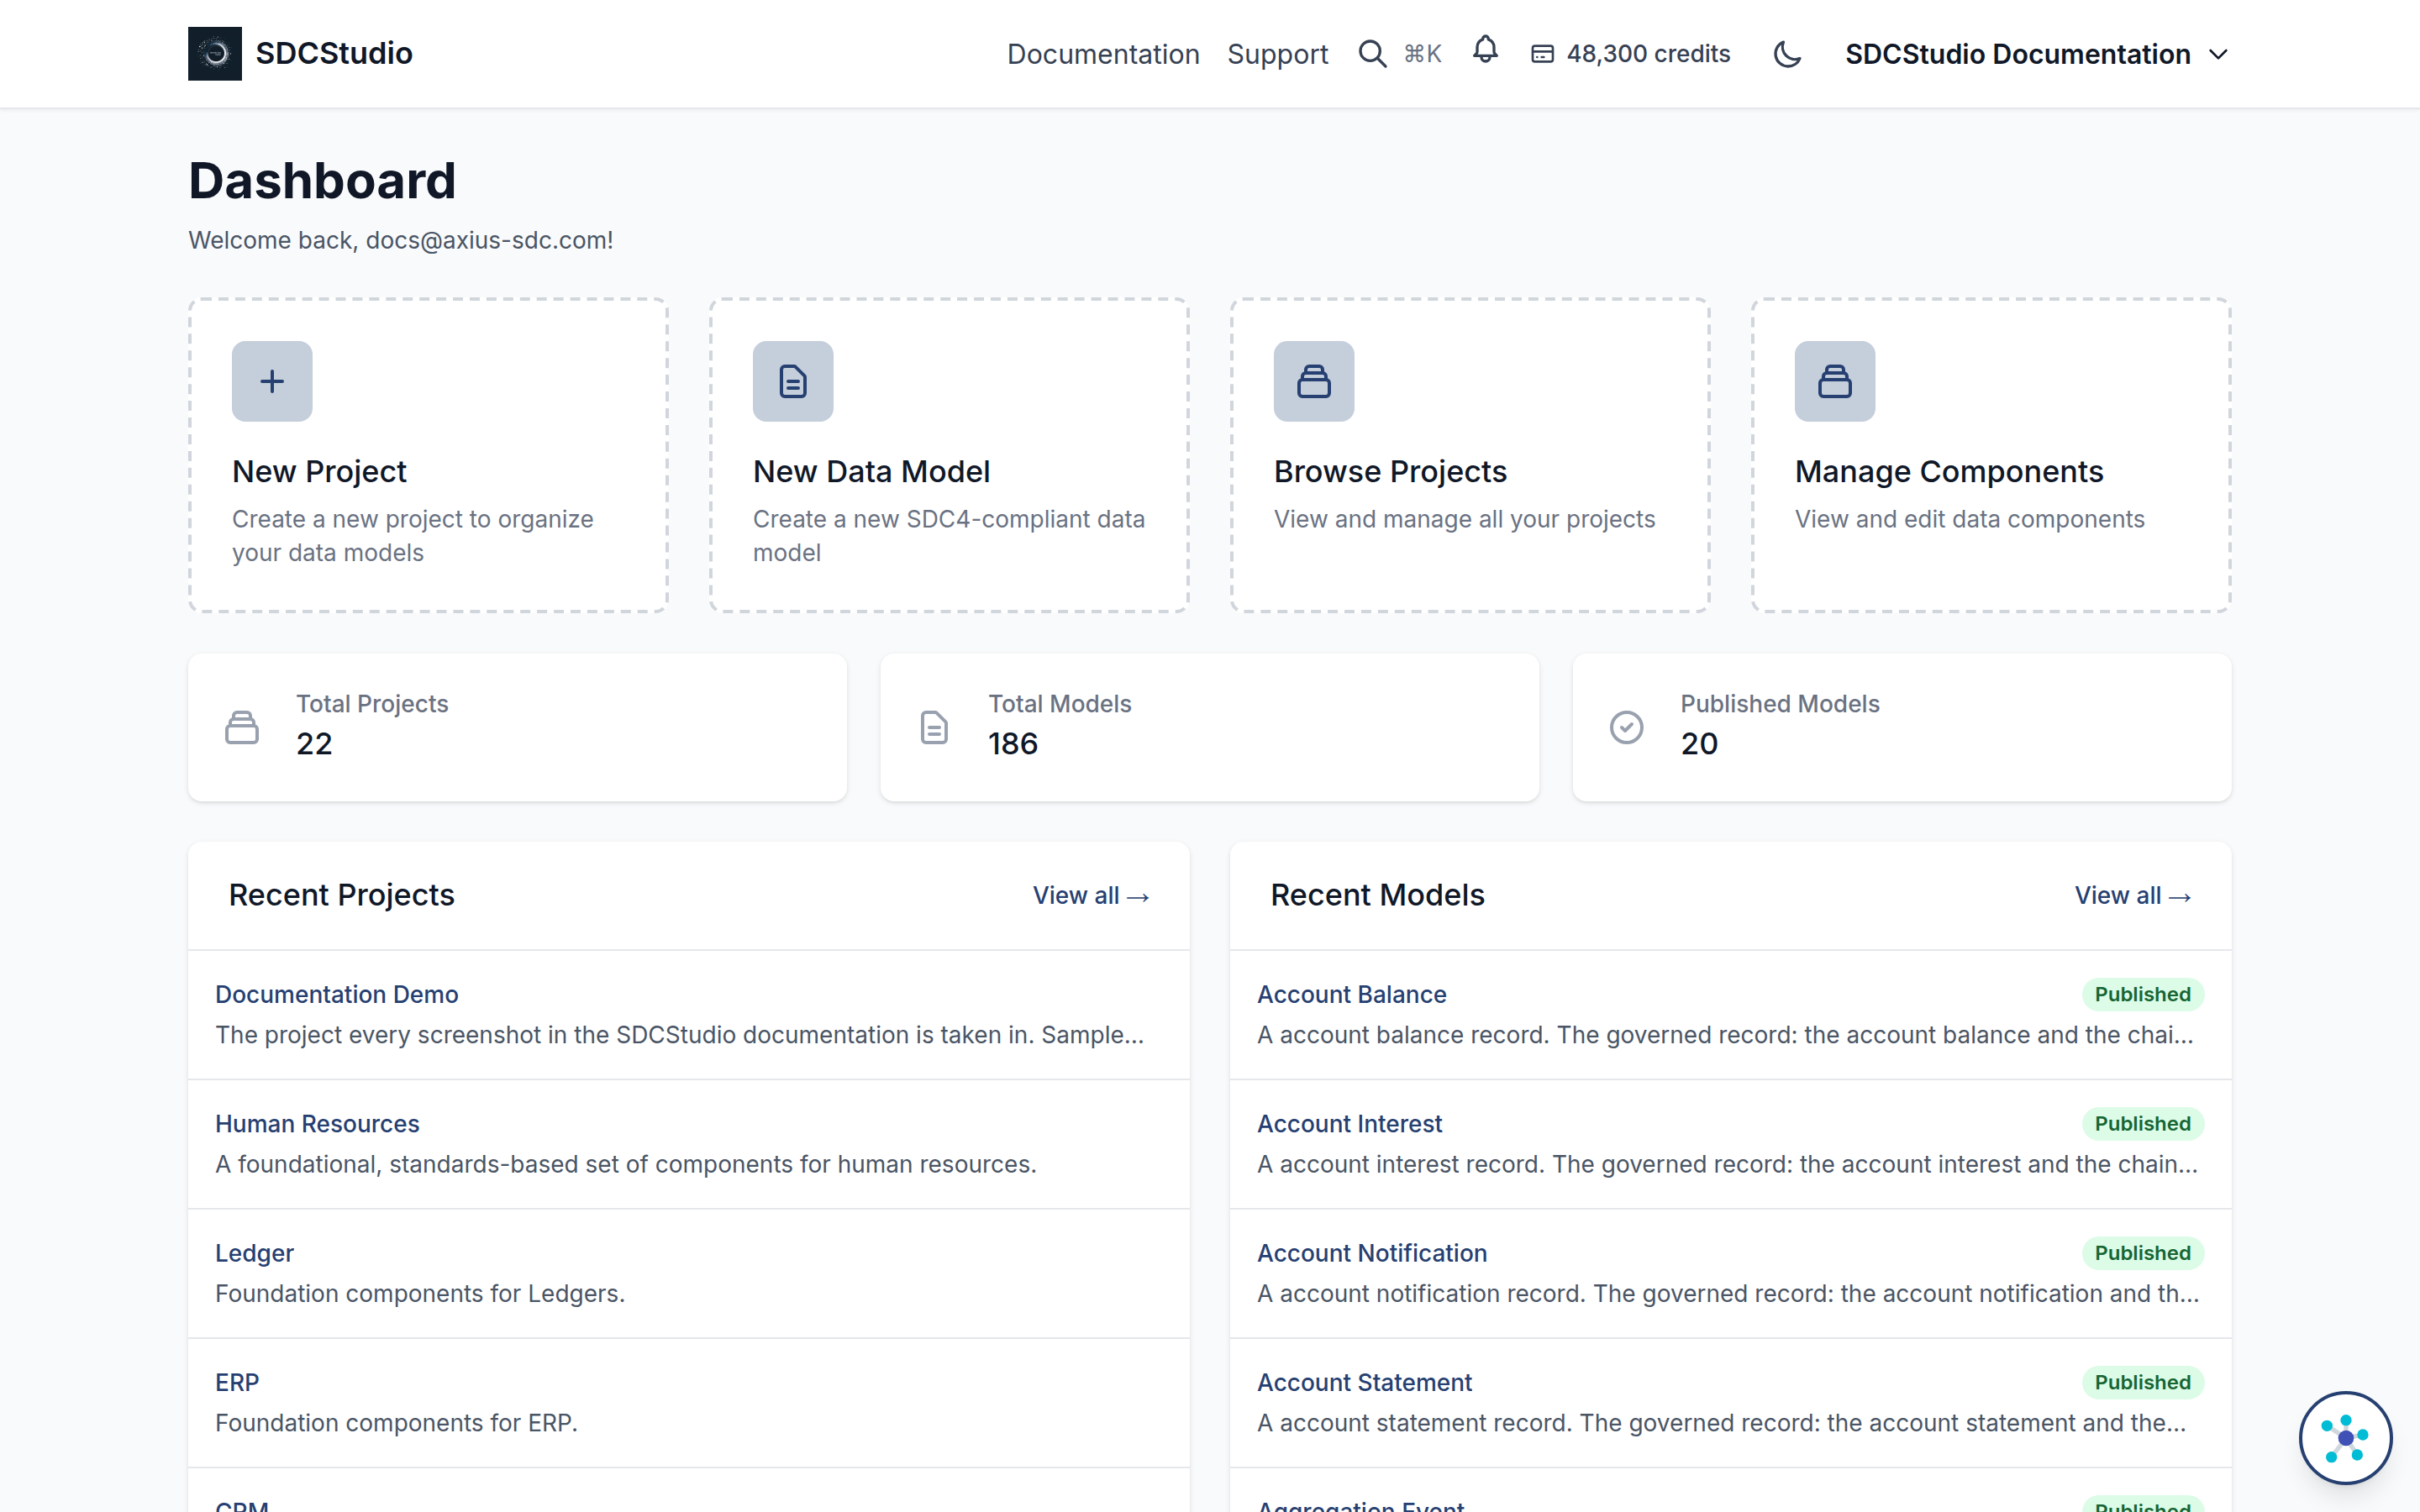
The Dashboard (/app/dashboard) links to the main areas, and every page shows breadcrumbs back to it:
- Dashboard - Four cards ("New Project", "New Data Model", "Browse Projects", "Manage Components"), counts of your projects, models, and published models, and the Recent Projects and Recent Models lists
- Projects (
/app/projects) - Create and manage projects - Data Models (
/app/models) - Browse and edit your data models - Components (
/app/components) - Manage reusable data components - Data Sources (
/app/data-sources) - View uploaded files and processing status, and start a new upload - Ontologies (
/app/ontologies) - Upload and manage ontologies - Settings (
/app/settings) - Profile, preferences, teams, wallet, practitioner credentials, and API keys
The top bar has Documentation, Support, Search (Ctrl+K or Cmd+K), notifications, your credit balance, and the theme toggle. The user menu (your name, top right) offers My Dashboard, Upload Data, Settings, About SDCStudio, and Log Out; a funded account also sees Practitioners.
Key Interface Features
- Progress: the Data Sources page shows each upload's status; reload it to see a change
- Status Indicators: Color-coded status badges show processing progress
- Contextual Actions: Buttons and menus appear based on what you're viewing and your role in the project
- Search and Filter: Quickly find models, components, and data sources
Step 4: Create Your First Project
Your account already has one project, created with it: named after you, private, and set as your default. You can build in it, rename it on its page, or create another to keep this work separate.
Cost: nothing. Projects are free; the charges begin with components and models.
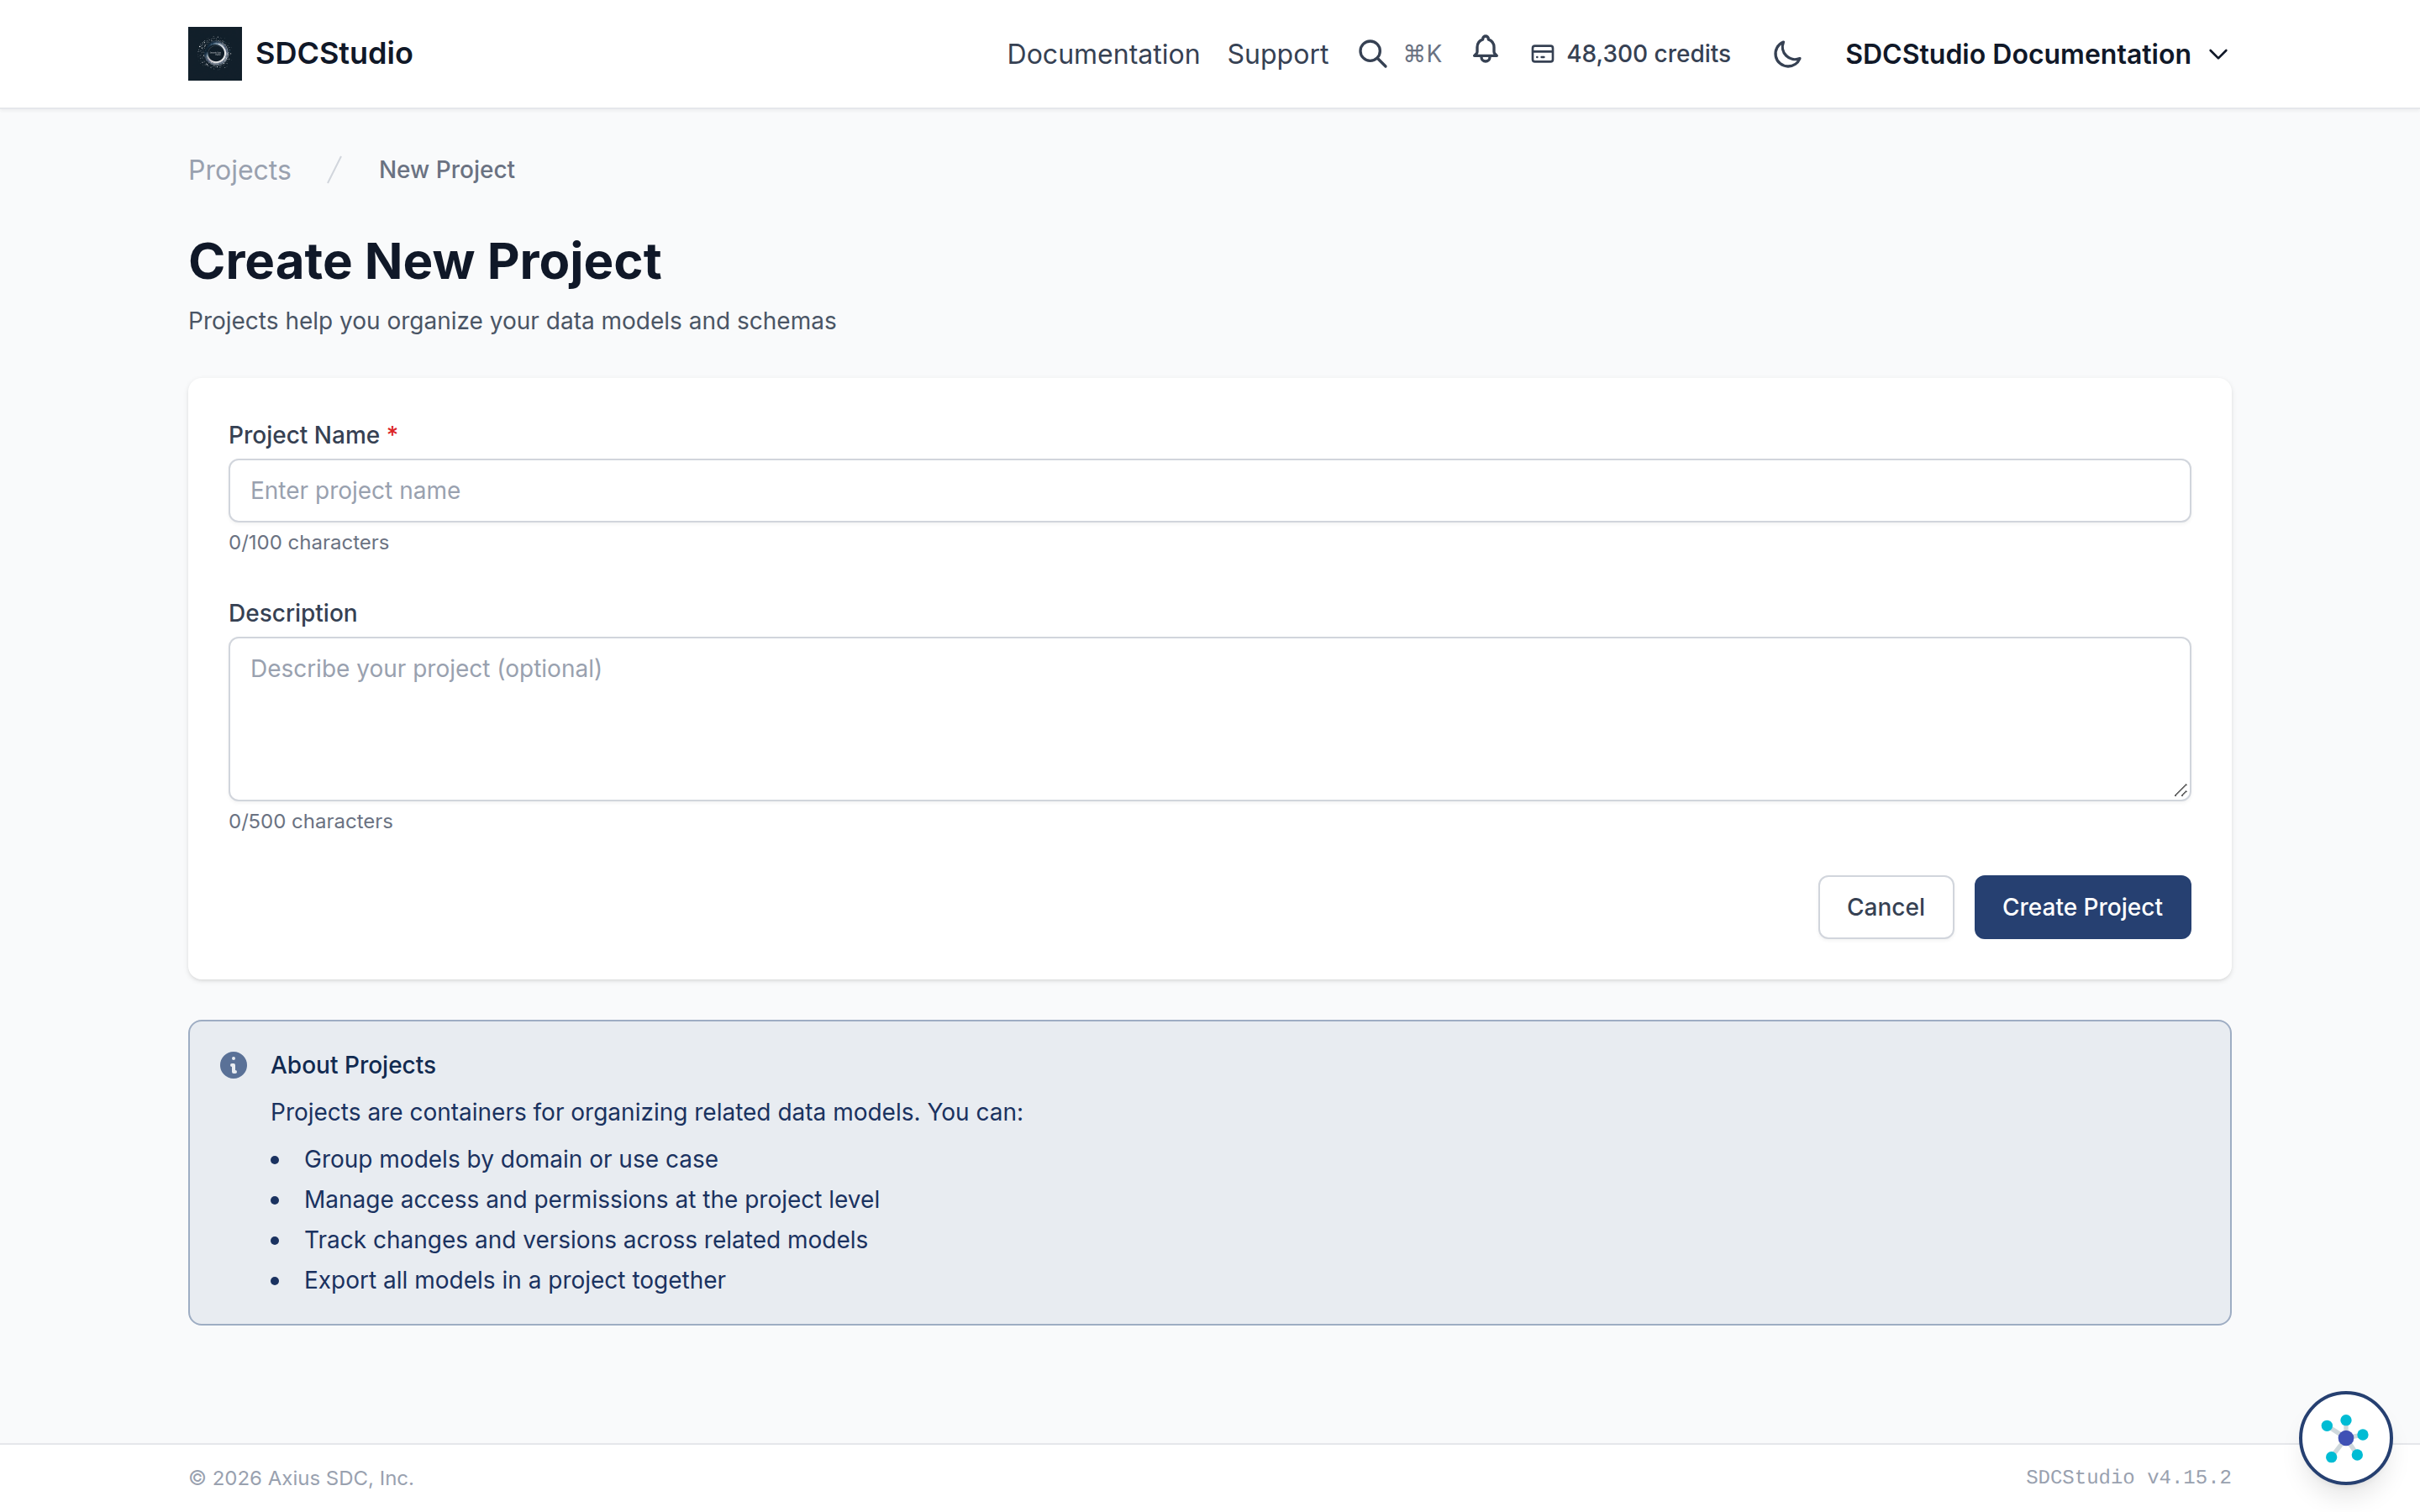
- Navigate to "Projects" (
/app/projects) - Click the "New Project" button
- Fill in project details:
- Name: Choose a descriptive name (e.g., "Customer Analytics"), 3 to 100 characters
- Description: Brief description of your project's purpose (optional, up to 500 characters)
- Click "Create Project"
The project's team is created with it; you manage members and roles on the project's page, in its Members section.
Step 5: Upload Your Data
Cost: 100 credits for each new component and each new cluster the upload creates, taken when processing completes; columns matched to existing components are free, and nothing is charged if processing fails.
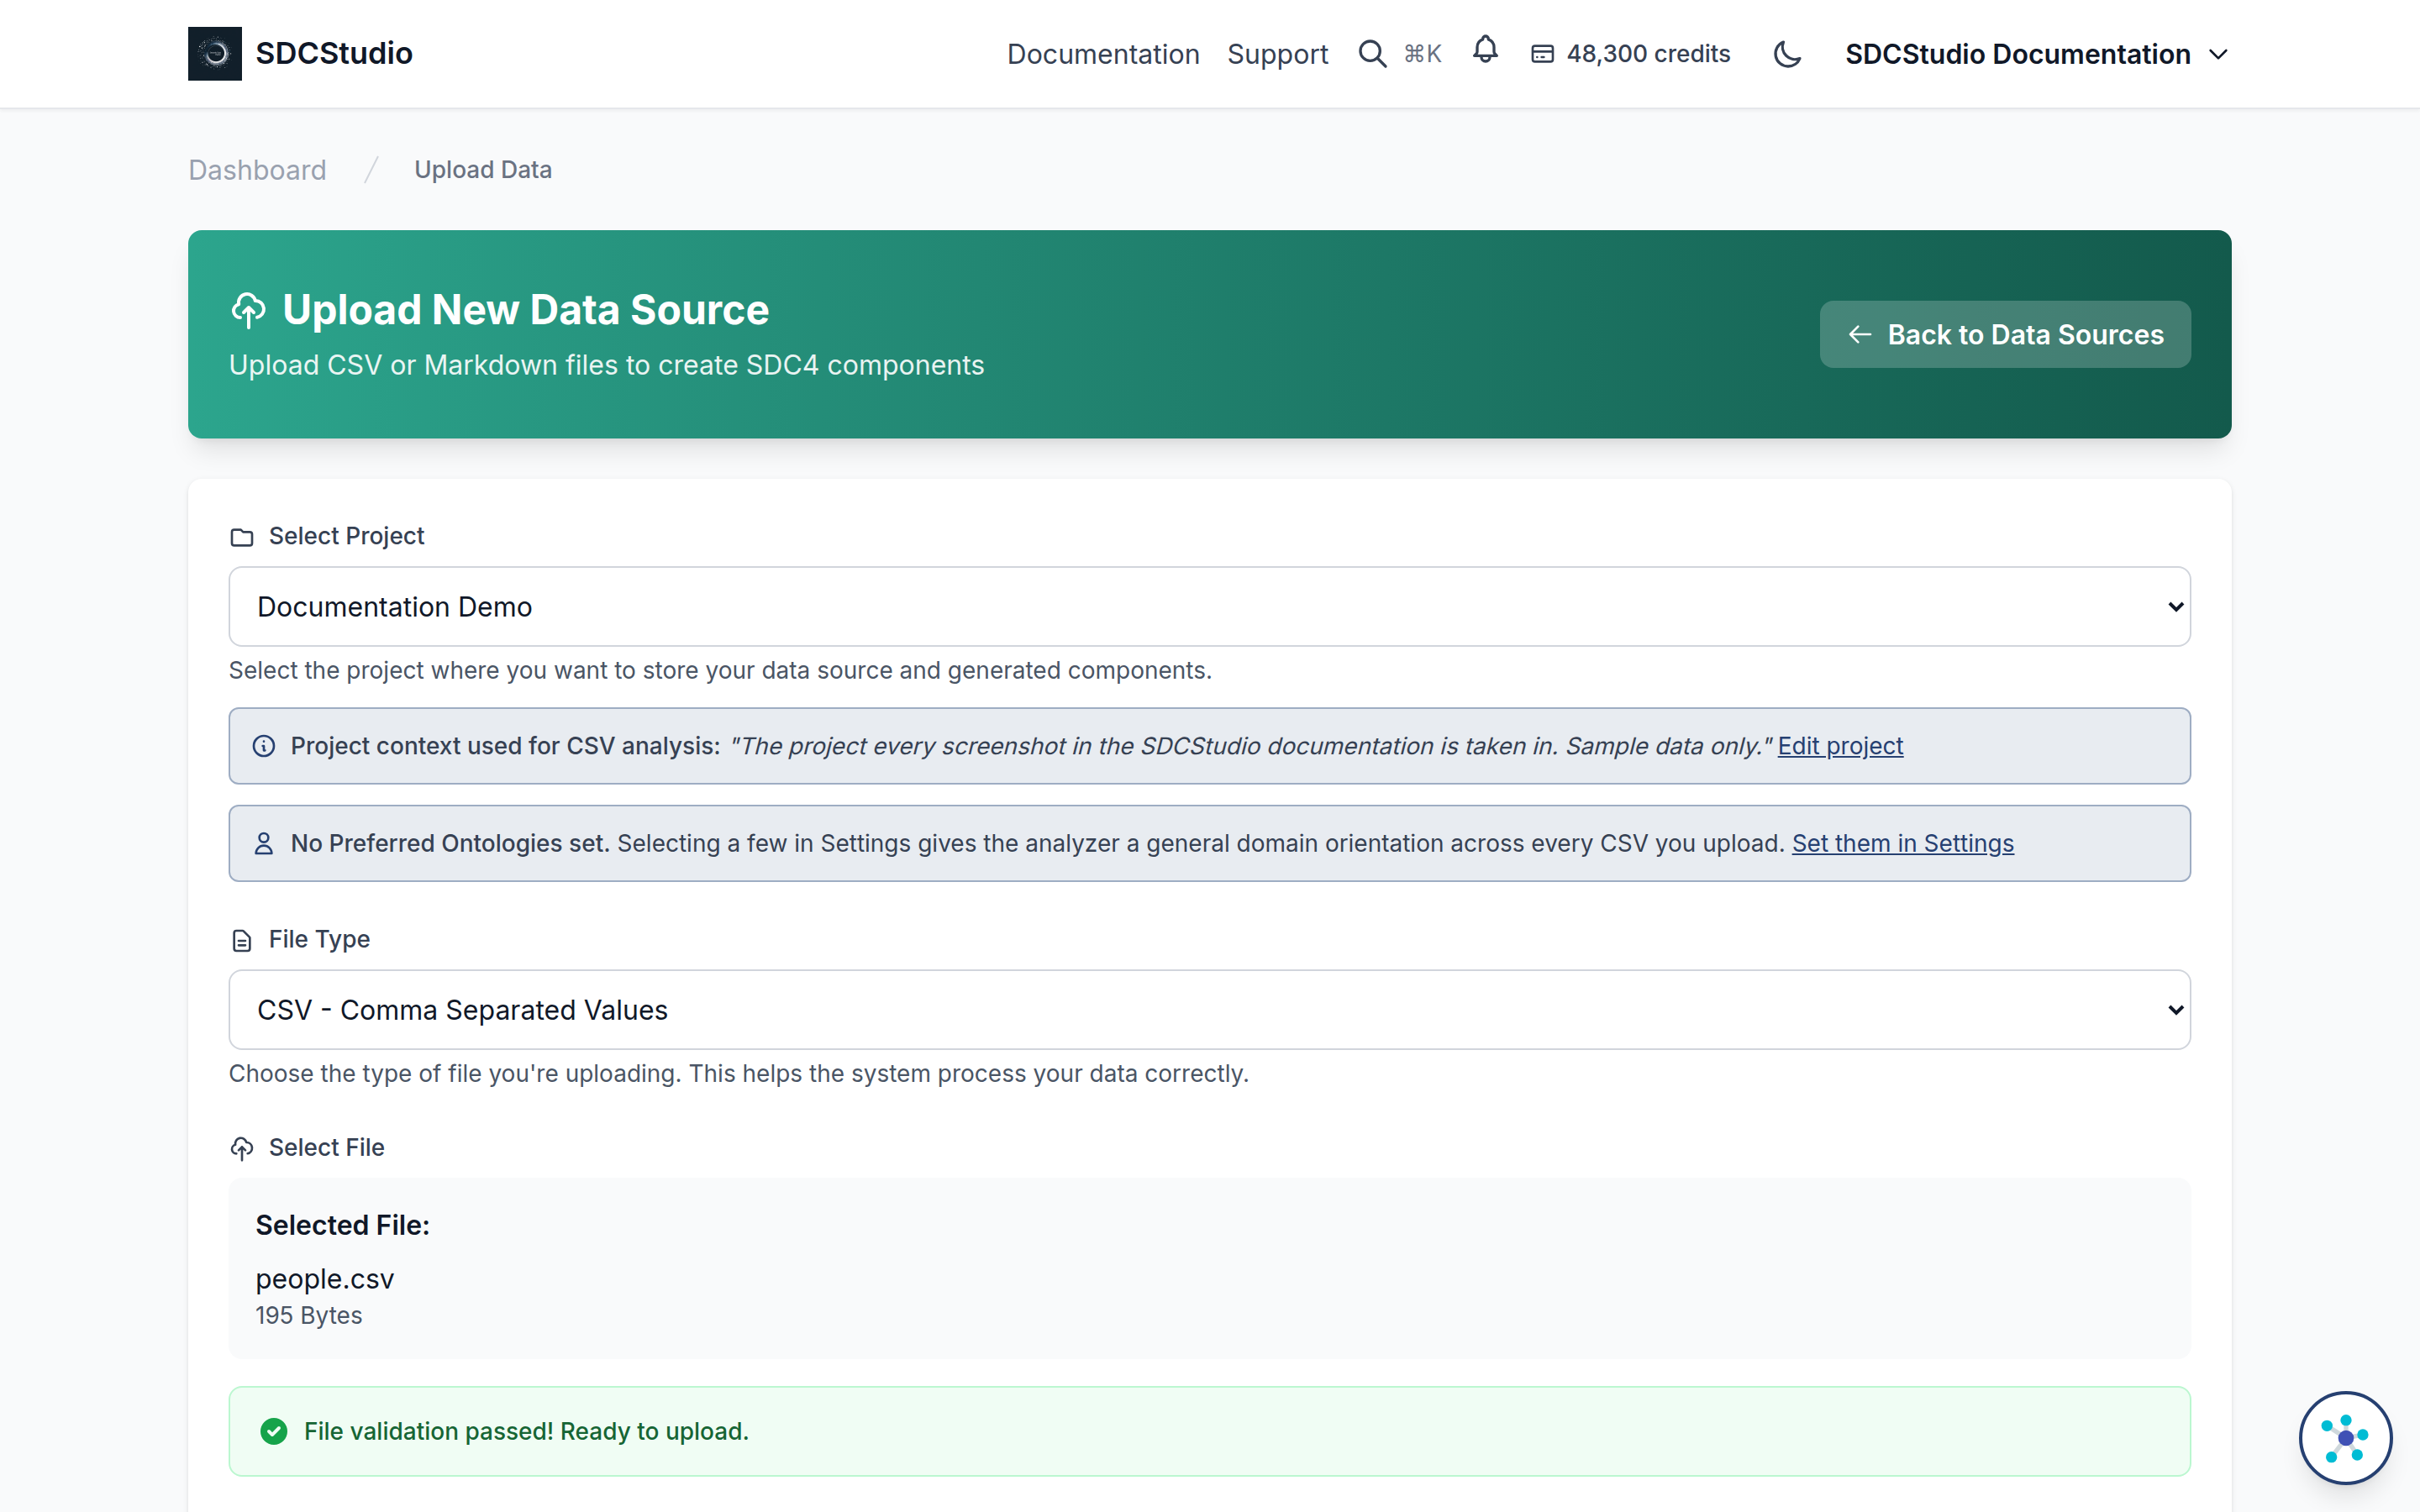
- Open the user menu and click Upload Data (this opens Data Sources,
/app/data-sources) - Click "Upload New Data" (
/app/upload) - Select Project: choose the project you just created
- Select File Type:
- CSV: Spreadsheet data with headers (recommended for a first attempt)
- Markdown: a dataset template (.md)
- Choose a file (.csv or .md, up to 50 MB)
- Click "Upload File"
Step 6: Watch the Processing (The Two-Stage Pipeline)
SDCStudio processes your data in two phases. Follow progress on Data Sources (/app/data-sources); reload the page to see a change.
Phase 1: Structural Parsing (Fast)
Status Badge: Uploaded → Parsing → Parsed
What's Happening: - File format detected and validated - Columns/fields identified - Basic data types inferred (XdString, XdCount, XdTemporal, etc.) - Structure mapped for agent analysis
A parsing failure shows as Error.
Phase 2: Agent Enhancement (Longer)
Status Badge: Agent Processing → Modeling → Completed
What's Happening: - Semantic Analysis: the agents work out what each field represents - Pattern Recognition: for example, they might detect email or phone formats - Ontology Matching: your preferred ontologies are used for suggestions - Validation Rules: the agents might propose constraints - Grouping: every column's component is placed in one cluster named after the file
A failure in this phase shows as Agent Error; the row offers Retry Processing, which reruns the agents without re-parsing the file.
Step 7: Review Your Generated Data Model
Once the status shows Completed:
- Open your project from Projects; the model appears in its Data Models list (or open Data Models,
/app/models) - Click the model created from your file
- Explore what the agents created: the model page shows the model's details and a Data Model Visualization graph of its cluster and components (hover a node for its type). To open a component, go to Components (
/app/components), filter by your project, and click it; the cluster named "Data Cluster" lists its Included Components
What the Agents Generated
The agents propose SDC4-compliant components with, for example: - Data Types: XdString for text, XdCount for integers, XdTemporal for dates, etc. - Validation Rules: Pattern matching, range constraints, required fields - Semantic Enrichment: Descriptions and labels informed by your ontologies - Structure: one cluster, named after the file, holding one component per column
Treat these as proposals: review each component before publishing.
Step 8: Customize Your Model (Optional)
You can refine the agents' work while a component is still unpublished:
- Open a component from Components (
/app/components) and click Edit - Modify properties across the form steps (Basic Information, the type's Constraints step such as String Constraints, Advanced Settings, Semantic Linking, Review & Save):
- Data type settings
- Validation rules
- Labels and descriptions
- Required/optional status
- Click "Save" on the Review & Save step (or Save & Publish to publish it at once)
- Repeat for other components as needed
Step 9: Publish Your Model
Cost: nothing. Publishing is free.
Publishing makes your model immutable and enables output generation:
- Publish each child component first: edit it and click Save & Publish on its Review & Save step. An unpublished model's page shows a Model Not Published card with these steps
- Publish the cluster: open the "
Data Cluster" from Components, click Edit Cluster, and click Save & Publish on its Review & Save step; the model will not publish while its data cluster is a draft - On the model page, click Publish (the project owner, a team admin or staff; a member asks one of them)
- Status changes to
Publishedat once; there is no confirmation dialog, only a success message
Published models and components cannot be edited. To change one, use Copy: it creates an unpublished copy labeled "COPY -- ..." that records where it came from (prov:wasDerivedFrom). Rename the label before publishing the copy. An owner or admin can Retire a published item; a retired item stays resolvable but is no longer listed.
Step 10: Generate Outputs
Now you can generate the output package:
What the Package Contains
- XSD Schema: XML Schema Definition for validation
- XML Template: the Governed Data Record with a placeholder at every value; the JSON instance carries sample values
- JSON: the same record as JSON
- JSON-LD: Linked data schema
- RDF: RDF/XML (.rdf) and Turtle (.ttl)
- SHACL: Shape constraints (
_shacl.ttl) with aSHACL_README.md - GQL: Graph database CREATE statements
- HTML Documentation: Human-readable documentation
- README-AI-PROMPT.md: a prompt for working with the model in an AI assistant
- Checksum: a
.sha1of the schema
How to Generate
Cost: nothing. Publishing and generating the package are free. Download App, further down the page, is 1,500 credits the first time for this model; later downloads of it are free.
- On the published model page, find the Model Generation card
- Click "Generate". Generation is a one-time operation, so make sure the model is complete first
- Click "Download Complete Package (ZIP)"
Generate an Application (Optional)
Cost: 1,500 credits for the first Download App of a model, either profile, taken at download; later downloads of that model are free. Generating the build is free, and a failed build charges nothing.
Once the package exists, a Generate App (choose one) card appears below it with two profiles:
- Lightweight: open source stack for development and small deployments
- Enterprise: the full stack, adding OWL reasoning, a temporal record history and single sign-on (requires 6 GB or more of free RAM to run)
Click Generate under the profile you want, then Download App.
Common File Types and Processing
CSV Files (Recommended for First Time)
- Best for: Tabular data, spreadsheets, database exports
- Processing: Column-by-column analysis with type detection
- Strength: Pattern recognition and validation
Markdown Dataset Templates
- Best for: Datasets described in the SDC Markdown dataset template (for example, from the SDC Obsidian template)
- Processing: Structured template parsing
- Strength: Carries descriptions and context with the data
Tips for Success
Start with Settings
- Upload ontologies before your first data model
- Better ontologies = better semantic suggestions
- Update ontologies as your domain knowledge grows
Start Simple
- Begin with a small CSV file (5-10 columns)
- Understand the workflow before tackling complex data
- Try both file types
Review, then publish
- Agent output is a proposal; review every component
- Published components are immutable, so get labels and constraints right first
- Build a library of reusable components
Use Meaningful Names
- Clear project names help organization
- Descriptive component labels improve usability
- Good documentation makes collaboration easier
Troubleshooting
Upload Issues
- File Too Large: The limit is 50 MB; break larger files into smaller ones
- Unsupported Format: Convert to CSV or a Markdown dataset template (.csv and .md only)
- Encoding Errors: Ensure UTF-8 encoding
Processing Issues
- Stuck in Uploaded: Open Data Sources and use the row's Trigger Processing action
- Error: Check the file format and headers, then upload again
- Agent Error: Click Retry Processing on the row; View Details shows the error message
- Slow Processing: Large files take longer, be patient
Interface Issues
- Page Not Updating: Data Sources does not refresh itself; reload the page
- Missing Buttons: Ensure the model is in the right state (e.g., published) and that you are the project owner or an admin
- Navigation Confusion: Use breadcrumbs at top to track location
Next Steps
Now that you've completed your first workflow:
- Explore More Features
- Data Modeling Guide - Advanced modeling techniques
- Semantic Enhancement - Ontology best practices
-
Generating Outputs - All output formats
-
Work with Ontologies
- Add domain-specific vocabularies
- Upload the public ontologies your domain relies on
-
Create custom ontologies for your organization
-
Browse the Public Libraries
- Public projects such as Default, NIEM, FHIR, NIH_CDE, SINAN, Business Documents, Peppol, UN-EDIFACT, and ISO 20022 are free to browse
-
Copy a published component into your own project to build on it
-
Try Different Data Types
- Temporal data with XdTemporal
- Quantified data with XdQuantity (includes units)
-
Complex structures with nested clusters
-
Build Your Component Library
- Create reusable components
- Share components across projects
- Establish organization standards
Getting Help
- Documentation: User Guides for detailed features
- Troubleshooting: Troubleshooting Guide
- Support: contact@axius-sdc.com
Success Checklist
You're ready to move forward when you can:
- Navigate the web interface confidently
- Configure Settings and upload ontologies
- Create projects and upload data files
- Understand the two-stage processing pipeline
- Review and customize generated data models
- Publish models and generate outputs
- Troubleshoot common issues
Ready for a detailed walkthrough? Check out Your First Data Model for a step-by-step guide with example data.